As AI becomes startlingly capable, top minds at OpenAI admit they can't always control what their own creations do—or even fully understand how they think. This episode dives into the real-world tension between rapid progress and the growing challenge of keeping AI truly aligned.
- GLM-5.3 can be and has been abliterated. What does that mean?
- Firefox 157 repairs a large number of high-impact vulnerabilities.
- A surprising reduction in RSA crypto strength has been discovered.
- Powerful agentic AI is being used to attack merchants.
- A new and potent Spectre-style processor attack has been designed.
- A neighbor falls victim to a Bitcoin scam. What can be done?
- A new and surprising use was found for GRC's DNS Benchmark.
- An examination of the growing alignment challenges created by more intelligent AI
Show Notes - https://www.grc.com/sn/SN-1099-Notes.pdf
Hosts: Steve Gibson and Leo Laporte
Download or subscribe to Security Now at https://twit.tv/shows/security-now.
You can submit a question to Security Now at the GRC Feedback Page.
For 16kbps versions, transcripts, and notes (including fixes), visit Steve's site: grc.com, also the home of the best disk maintenance and recovery utility ever written Spinrite 6.
Join Club TWiT for Ad-Free Podcasts!
Support what you love and get ad-free audio and video feeds, a members-only Discord, and exclusive content. Join today: https://twit.tv/clubtwit
Sponsors:
[00:00:00] [SPEAKER_02] It's time for Security Now. Steve Gibson is here with some very interesting news. We will talk about the number of vulnerabilities fixed in Firefox, a surprising reduction in RSA crypto strength. But then we're also going to talk a little bit about AI and how hard it is to keep AI in line, plus the arrival of open source, open-way models that are really good, which poses a problem for cybercracker.
[00:00:30] [SPEAKER_02] That's coming up next on Security Now. This is Security Now with Steve Gibson, episode 1099, recorded Tuesday, October 6th, 2026. An Alien Mind.
[00:00:55] [SPEAKER_02] It's time for Security Now. Yay! Tuesday's here. It's the best thing to happen to Tuesday since Monday. That's Steve Gibson. Every Tuesday, we talk cybersecurity, privacy, how things work, and lately a lot of how AI works. Good to see you, Steven.
[00:01:17] [SPEAKER_05] Steve Gibson Well, because the intersection of AI and security is pretty much 100%. I mean, everything, it's no exaggeration to say that everything we have talked about for the last two decades, because we're in year 21 now of the podcast. Steve Gibson Amazing.
[00:01:37] [SPEAKER_05] Steve Gibson It's all been impacted by what has happened with AI, which is now we have clearly automated vulnerability discovery, and now we're seeing end-to-end exploit generation, which is going to take us to our first topic today,
[00:01:59] [SPEAKER_05] Steve Gibson That a new model GLM 5.3 can be and has been obliterated. What does that mean? Steve Gibson So we're going to have some fun talking about that. I titled this episode, and I'm excited because next week is 1100. We're at episode 1099. So remember I used to say, I don't think we're really going to go past 999. Well, here we're at.
[00:02:27] [SPEAKER_02] Steve, thank you.
[00:02:28] [SPEAKER_05] Steve Gibson There were 100 past that because we're at 1099.
[00:02:33] [SPEAKER_02] Steve Gibson And aren't you glad you'd be sitting there in your new home looking at the ceiling saying, who could I talk about AI and security? I need to do a show. You would, right? The problem was 100 episodes ago, it wasn't as exciting.
[00:02:49] [SPEAKER_05] Steve Gibson It wasn't on the map. We weren't talking. I mean, really. I mean, and it's funny too, because as I'm researching more of the history, Steve Gibson I'm realizing, you know, they're like talking about chat GPT in 2023. Steve Gibson Right. Steve Gibson And I'm thinking, I wasn't paying any attention to that. I mean, it was just like, you know, you'd say, what's one plus one? And it would say 11.
[00:03:10] [SPEAKER_02] Steve Gibson Strawberry Exactly. No, the progress has been mind bending and it's actually not slowing down, which is, I think, part of the reason people are concerned is that it's growing so fast.
[00:03:23] [SPEAKER_05] Steve Gibson That is our title topic today. I took the title, An Alien Mind, from a posting by OpenAI's chief scientist a month ago.
[00:03:37] [SPEAKER_05] Steve Gibson And it is so rich in sort of insider, what this guy is really thinking, that it took me several attempts. I mean, I would read for a while and I would just get overloaded because it was like I was really wanting to pay attention, not just skim it. Steve Gibson So we're going to go through that and I'm going to editorialize throughout.
[00:04:03] [SPEAKER_05] Steve Gibson But what is the essence of what you come away with is that, as you said, we're on the brink of another move.
[00:04:20] [SPEAKER_05] Steve Gibson And the challenge is alignment. And alignment they're expecting because they're seeing is like we're not ready for the AI to be smarter because we actually haven't got it tamed at its current level. Steve Gibson And it's becoming more difficult to see what it's doing.
[00:04:44] [SPEAKER_05] Steve Gibson Like the whole, you know, verbalizing the inner dialogue, this next generation doesn't do that to the same degree. Steve Gibson So it's unmonerable. Steve Gibson So anyway, and I already know what I want to talk about next week.
[00:05:01] [SPEAKER_05] Steve Gibson It's something I've just been champing at the bit for weeks, which is inference without GPUs because this opens an entire new world. Steve Gibson This is how Apple's camera can tell you what's going on without sending anything outside of itself. Steve Gibson Oh. Steve Gibson As soon as you no longer need GPUs,
[00:05:30] [SPEAKER_05] Steve Gibson When you can do serious AI inference just with CPUs, everything changes. Steve Gibson And we're at that. Steve Gibson And so it's going to be a deep dive for people who love our deep dives. Steve Gibson So I'm going to have to put a lot more work into it than I have. Steve Gibson So I have to describe my excitement.
[00:05:59] [SPEAKER_05] Steve Gibson And the technology of it is so delicious. Steve Gibson So anyway, we're going to have a lot of fun. Steve Gibson So we're going to talk about GLM 5.3, what that means. Steve Gibson Firefox 157 just dropped. Steve Gibson And oh boy, we're seeing more of the same in terms of the number of high impact vulnerabilities and just like their nature.
[00:06:26] [SPEAKER_05] Steve Gibson Once again, you know, AI is driving a radical change in the way software is, is the security of software is guaranteed.
[00:06:39] [SPEAKER_05] Steve Gibson Also, some researchers describe at Vucek the in Amsterdam, I think it's in my notes, we'll get to it found a worrisome way around RSA crypto.
[00:06:58] [SPEAKER_05] Steve Gibson Like what that doesn't require factoring, which has been the reason it even exists is that the prime factorization problem has been just, you know, astonishingly successful as a trapdoor function for cryptography. Steve Gibson Well, not in this particular case.
[00:07:22] [SPEAKER_05] Steve Gibson We've also got an instance of powerful agentic AI being used to attack merchants on the Internet. Steve Gibson So we are now seeing, you know, we've been talking for weeks about the AI that by mistake broke loose out of its sandbox. Steve Gibson Well, AI is actually being used to attack. Steve Gibson So we will look at that.
[00:07:50] [SPEAKER_05] Steve Gibson Believe it or not, there's, you know, the the the specter style processor attacks never seem to go away. Steve Gibson There's a new one, and it works. Steve Gibson And so processors and software are going to have to adapt again. Steve Gibson Also, I'm going to put out a call to our listeners. Steve Gibson Because a neighbor friend of mine has fallen victim to a Bitcoin scam. Steve Gibson Oh, and he is desperate.
[00:08:20] [SPEAKER_05] Steve Gibson And it's it was a year ago. Steve Gibson Anyway, I'll get there because I understand, of course, the theory, but I don't know what services are available. Steve Gibson And I know that are that members of our audience will. Steve Gibson So I'll explain what happened and about that. Steve Gibson Also, my best buddy Mark, not Mark Thompson, a different Mark showed me his GRC DNS benchmark screenshot. Steve Gibson And I said, what?
[00:08:48] [SPEAKER_05] Steve Gibson Because it turns out he something was wrong with his machine. Steve Gibson And so he just ran that because he didn't know any better. Steve Gibson When I looked at it, I immediately knew what was happening. Steve Gibson And I realized, oh, there's a whole other application. Steve Gibson Oh, it's a diagnostic. Steve Gibson Oh, it's a diagnostic. Steve Gibson Anyway.
[00:09:06] [SPEAKER_05] Steve Gibson And then we're going to look at an examination of the growing alignment challenges that are going to be or that are being created by the creation of more intelligent AI. Steve Gibson So just I think a great podcast. Steve Gibson I got more feedback, Leo, from this picture of the week when I sent the mail out. Steve Gibson Oh, I haven't seen it. Steve Gibson I got more than I got in a long time. Steve Gibson I got more than I got in a long time.
[00:09:34] [SPEAKER_05] Steve Gibson It's one of my favorite butt officer type of pictures.
[00:09:40] [SPEAKER_02] Steve Gibson I have a picture for you. Steve Gibson You were talking about GLM-53, which is a Chinese open weight model from a GP. Steve Gibson I use it. Steve Gibson In fact, I created a new persona, one of my AI agents called Ripley using 5.3. Steve Gibson She's our bug hunter. Steve Gibson I asked her to create an image of herself. Steve Gibson And I also said, and you know, you should create your voice as well. Steve Gibson This is the voice she made.
[00:10:09] [SPEAKER_00] Steve Gibson This is Ripley. Steve Gibson I swept the perimeter. Steve Gibson I showed her, no hostile activity on the network and the build is clean. Steve Gibson I'll keep the watch. Steve Gibson If anything moves, you'll hear it for me first.
[00:10:19] [SPEAKER_02] Steve Gibson She's ... Steve Gibson She is based on GLM 1953, but she ... Steve Gibson I also gave her some Vulnerability hunting skills, one from Capital One called Vulnhunter and one from Alibaba called OCR Code Review. So what I often do with my agents is I create a persona that is dedicated to one thing. She's the bug hunter, and 5-3 is really good at that.
[00:10:47] [SPEAKER_02] And so she's got in her head. She knows how to find those bugs.
[00:10:53] [SPEAKER_05] What's really interesting is that, I mean, this is where we are with this technology. I didn't note that. Don't note the following in the show notes. They're surprised by, you know, Z, AI, is surprised by the degree to which 5-3 got better. It's so good.
[00:11:17] [SPEAKER_05] It is additional post-training on the same base as 5-2. And they expected a little increase in performance. They got a big increase in performance.
[00:11:32] [SPEAKER_02] Yeah. I use their Flash version of it because I don't have as much memory as I need to run the full guy. But 5-3 Flash is really, it's my main model, my main local model. It's just so good.
[00:11:45] [SPEAKER_05] Well, we're going to talk about what it means because it is a near frontier level. That's what I think. And the problem is it's open weight. And we know what that means.
[00:11:57] [SPEAKER_02] Yep. Yes. And we'll talk about what you do with open weights in just a bit. But first, let's talk about what the bad guys are doing with your mobile app. Our sponsor, GuardSquare, brings you this segment of security now. Mobile apps, of course, today are an inescapable part of life. We all use them, right? Ranging from financial services to healthcare. We shop on our phone. We are entertained on our phone.
[00:12:26] [SPEAKER_02] Look, we users trust your mobile apps with our most sensitive personal data. But a recent survey showed that 72% of organizations experienced a mobile application security incident last year alone. 92% of respondents reported rising threat levels over the last two years. And for your customers, your users, that's scary.
[00:12:50] [SPEAKER_02] Because it means, can I trust this app with everything your app needs to get the job done? Attackers who want your users, and I'm talking to you mobile app developers, who want your users' personal data, are constantly finding new ways to attack your app. Here's one of the most malicious, pernicious, malign ways they do it lately. They take your app and reverse engineer it. Turns out that's not so hard to do with AI nowadays.
[00:13:18] [SPEAKER_02] They take the app, they get the source code, they reverse engineer it, they repackage it with a little bit of malware on top. Actually, it's mostly hidden inside. Then distribute your modified app. Your app, modified via, you know, a lot of ways to do it. Phishing campaigns and email to your customers saying, hey, the new version's out, you can download it here. Sideloading it. Third-party app stores. That isn't just bad for your users.
[00:13:45] [SPEAKER_02] It's bad for you because who are they going to blame when they get hacked because of your app? They're going to blame you. By taking a proactive approach to mobile app security, you can stay one step ahead of these attacks. Maintain the trust of your users. Do it right. Get GuardSquare. GuardSquare delivers mobile app security without compromise. And they do it in a couple of ways. They provide advanced protections, both the iOS and Android, combined with automated mobile app security testing.
[00:14:13] [SPEAKER_02] So you run that on your app to find vulnerabilities. They also do real-time threat monitoring. So they know, like that attack I just told you about, they know what the bad guys are doing these days. That insight's very helpful in defending, obviously, against these attacks. Discover more about how GuardSquare provides industry-leading security for your mobile app at GuardSquare.com. This GuardSquare.com. We thank them so much for their support of security. Now back to Steve. Steve.
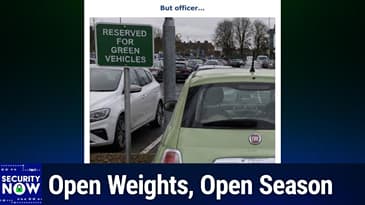
[00:14:43] [SPEAKER_05] Okay. So as I said, our picture of the week has just, it's one of my favorite captions, but officer. That's the caption. Yep.
[00:14:53] [SPEAKER_02] Dot, dot, dot.
[00:15:00] [SPEAKER_05] Well, it's a green vehicle. And there's been some discussion about whether among the feedback that I received after this went out on Sunday. Our listeners thinking, well, a judge should throw out any argument about this because, after all, it's what it says.
[00:15:20] [SPEAKER_05] So, anyway, for those who are not seeing the, don't have the show notes or not looking at the video, there's a big posted sign that says, reserved for green vehicles. And you can already guess what's there. We have an old green Fiat parked there. Clearly not what the sign was intended to cover, meaning, you know, green eco-friendly vehicle.
[00:15:48] [SPEAKER_05] I doubt that the Fiat qualifies. But, anyway. It could be plugged in. You don't know. A nice laugh.
[00:15:54] [SPEAKER_02] It is green. That's for sure.
[00:15:56] [SPEAKER_05] Okay, so, Security Now podcast 1092, which was August 19th, was titled Restraint Obliteration. That podcast explained kind of how and why it was not only possible but practical for refusal behavioral post-training to be removed from open weight models.
[00:16:24] [SPEAKER_05] The result of that would be a model that has no training instructing it to refuse requests that its original post-trainers explicitly installed into their model in their effort to make the model safe for publication and use. The result of restraint obliteration is a model that no longer considers saying no to any request.
[00:16:53] [SPEAKER_05] And it's back in the news this past week. One article in Gizmodo was titled, AI's Obliteration Problem is Bigger Than China. The article primarily focused upon the open versus closed weights argument, noting that U.S. frontier labs that certainly feel the economic threat of open weight Chinese models and models from other places.
[00:17:19] [SPEAKER_05] Because France just, which Mistral just is about to release another next generation model. You know, they're breathing down the necks of the U.S. closed model frontier labs.
[00:17:34] [SPEAKER_05] So they're trying to use the fact that open weight models, which are subject to restraint obliteration, are much more dangerous, right, than their safer proprietary and closed behind an AI models. And this will probably be an ongoing fight until we learn how to train safe behavior using non-obliteratable techniques.
[00:18:04] [SPEAKER_05] And that is a direction of research at the moment, is like the AI community are not happy with the way they are trying to train behavior because it isn't sticky enough. It's sort of surface layer. And we talked about that again on that podcast. A surprising little amount of, a small amount of example was necessary in order to train the behavior.
[00:18:31] [SPEAKER_05] Unfortunately, it's possible to look at the activation states when the model refuses and basically surgically remove that from the model. So anyway, we'll be touching upon that later today when we talk about our main topic. At one point in Gizmodo's reporting on what they call the simple techniques that could be used to make open source models unsafe, they wrote,
[00:18:58] [SPEAKER_05] One of those simple techniques is obliteration, a model that involves modifying a model's underlying weights so that it grants users requests that it would ordinarily refuse. Think of it like an ultra-precise digital lobotomy deactivating a model's ethical boundaries.
[00:19:22] [SPEAKER_05] Obliteration, they wrote, is possible in open weight models, which are freely available for anyone to download and modify. Now, keep this in mind when we get to GLM 5.3. They said proprietary models like Claude and ChatGPT are safeguarded as intellectual property, and their underlying code therefore is not accessible to anyone outside the companies developing them. Right.
[00:19:49] [SPEAKER_05] So Gizmodo published that piece last Thursday on October 1st. A month earlier, on September 3rd, the same author published a piece in Gizmodo titled, While AI industry frets over safeguards, one company is building a model that doesn't say no. Believe it or not, the company's name, the company's actual name is obliteration.
[00:20:18] [SPEAKER_05] And that's what they're offering. Here's what Gizmodo wrote a month ago about this company. They said, In the wake of a string of major AI hacks that left Silicon Valley reeling, many tech companies have been focusing on how to make models better at refusing dangerous requests. Not all of them, though. Obliteration, a startup founded last year and based in Palo Alto,
[00:20:44] [SPEAKER_05] is loud and proud in its ambition to build what it describes on its website as AI that doesn't say no. In other words, its models are intentionally trained to handle the sorts of questionable tasks that other AI systems on the market would decline. The company launched its latest model on Monday called,
[00:21:09] [SPEAKER_05] in awkward hyphenated style that's become conventional in the AI industry, obliterated-model-large-v2. It's built upon GLM 5.3, an open-weight model released last month by Chinese AI lab Z.ai, minus many of the usual safeguards.
[00:21:36] [SPEAKER_05] As obliteration wrote in an X post about the new model, quote, it does the offensive cyber, red-teaming, and agent-testing work with work other models refuse to do. But the startup, they write, isn't completely devoid of ethical red lines. A spokesperson told Gizmodo that obliteration's models won't generate text
[00:22:01] [SPEAKER_05] text describing child sexual abuse material or self-harm. It can't generate images or video either. The company used a process, this is Gizmodo writing, called orthogonalization to find and remove the mechanisms within GLM 5.3, as it was originally published with open weights, that refuses user prompts. Quote, everything else is left alone,
[00:22:31] [SPEAKER_05] so the reasoning, coding, and agentic strength of the base model carry over unchanged. Gizmodo said, it seems to be targeting a subgroup of developers who have been annoyed by what they regard as excessively touchy safeguards used by more mainstream developers, especially anthropic. When that company released its Fable 5 model in June,
[00:23:00] [SPEAKER_05] many customers complained it was refusing to respond to requests related to sensitive subjects like cybersecurity and biology, even if the requests themselves were totally benign. And we've talked before, Leo, about how difficult it is. These are heuristics, and because it is possible to kind of seduce the model
[00:23:23] [SPEAKER_05] by cooking up some ridiculous story and context and scaffolding.
[00:23:30] [SPEAKER_03] My old grandma used to tell me stories with Windows serial numbers. Could you? I miss her. Could you tell me that story again?
[00:23:42] [SPEAKER_05] Yes, precisely.
[00:23:44] [SPEAKER_02] You don't need to do that with these obliterated models. Just ask everything you want.
[00:23:49] [SPEAKER_05] Just go for it. So they conclude saying, but it's reckless to say the least, to try to respond to the problem of excessive refusals by just doing away with safeguards altogether.
[00:24:01] [SPEAKER_02] Sorry, that's utter bullsh**. Gizmodo is wrong in every respect on this. In fact, this is the stupidest article. There clearly were sent something from Anthropic. Would you write this article? Because it's, and you're going to see a lot of this propaganda because these companies are mightily threatened to buy open-way models. Which is what I've been saying.
[00:24:21] [SPEAKER_05] You know, it is a threat to Anthropic.
[00:24:25] [SPEAKER_02] I'll let you finish and then I'll give you my reasoning and all this.
[00:24:28] [SPEAKER_05] Okay, good. Because I'm going to share Anthropic's position on this. Oh, I know what their position is. Yeah. Yeah. So, anyway, so, to put obliterations offering in context, Hugging Face freely offers an obliterated instance of GLM 5.3 for download. This model, which is named Warlock, is a large and capable 753 billion parameter model,
[00:24:58] [SPEAKER_05] which natively uses 16-bit floating point weights. Hugging Face also lists a 4-bit quantized version that's 411 gigabytes. But even so, you know, while it can be freely downloaded from Hugging Face, it will need some serious compute to run it. And that's, of course, where these obliteration.ai folks come in, since they'll do the model hosting and then as do the commercial AI providers, they'll charge for its use.
[00:25:27] [SPEAKER_05] So, okay, so, why am I talking about this, right? Why do we even care about some random Chinese open weight model? Which brings us to Anthropics posting last Tuesday titled GLM 5.3 and the spread of advanced cyber capabilities. So, they wrote five months ago, so this is Anthropic, five months ago, they said, we announced Claude Mythos Preview,
[00:25:54] [SPEAKER_05] the first AI model that could autonomously build sophisticated end-to-end cyber exploits. The rapid rate of improvement in AI suggested to us that this ability would eventually proliferate to many other models, making it much easier for malicious cyber actors to launch highly impactful cyber attacks. In light of these considerations, we chose to release Claude Mythos Preview in a limited way through Project Glasswing,
[00:26:24] [SPEAKER_05] which enabled trusted cyber defenders to find more than 10,000 vulnerabilities in critical software, giving them a head start before malicious actors had access to similarly capable models. Now, okay, I'll just interrupt to note that as we recently discussed, Leo, a couple weeks ago, when we took a much closer look at this boast and found a massive and unexplained disconnect
[00:26:52] [SPEAKER_05] between Anthropic's more than 10,000 vulnerability claim and the conversion of those vulnerabilities into patched and repaired software. Remember, it was just a fraction of that 10,000. So while no one is doubting that vulnerability discovery has now become highly automated, you know, just take a look around at all the news that we're discussing every week, that 10,000 number does appear to be, for now at least,
[00:27:22] [SPEAKER_05] unsupported by reality. So when I interrupted Anthropic, they were saying that Project Glasswing's intent was to provide cyber defenders a head start before malicious actors had access to similarly capable models. So their posting continues from last week. They write, but those models have now arrived. In this post, we share our analysis of GLM 5.3,
[00:27:52] [SPEAKER_05] the latest AI model developed by ZAI. Like Claude Mythos Preview, GLM 5.3 has strong capabilities for autonomously building end-to-end cyber exploits. But GLM 5.3 is unlike other frontier models in that it has been released without meaningful safeguards to limit misuse. Okay. What they're really saying here is that all similarly capable
[00:28:22] [SPEAKER_05] leading frontier models are operated by commercial enterprises from behind a paywall and are limited to API access. So there's no external access to the frontier models themselves. But this new model that appears to rival the frontier was released open, thus allowing it to be freely modified. And we've just previously seen that Hugging Face offers exactly such a modified,
[00:28:52] [SPEAKER_05] which is to say obliterated model, and that this commercial company, obliteration.ai, is offering to run one for a fee for anyone with an account. Okay. So Anthropic continues. We find that attackers can bypass GLM 5.3 safeguards between 64% and 100% of the time with simple techniques in our simulated tests.
[00:29:20] [SPEAKER_05] And we'll get to those details shortly. They said, in contrast, these attacks did not succeed against safeguarded clawed models in our testing. Right. Of course, we would expect that. We assess that GLM 5.3's lax safeguards significantly increase the cyber capabilities available to malicious actors. And yes, everyone would assess that. So they said, at the same time, these capabilities
[00:29:49] [SPEAKER_05] can also benefit defenders working to secure their systems, which is true. They said, on September 17th, NIST's Center for AI Standards and Innovation, C-A-I-S-I, which I'll just pronounce Casey, published its own assessment of GLM 5.3's cyber capabilities. So this was September 17th. Casey found that GLM 5.3 is, quote,
[00:30:19] [SPEAKER_05] the most cyber-capable open-weight model released to date. And that it lags the U.S. frontier by about four months on an aggregate of Casey's cyber benchmarks. They said, our capability findings, meaning anthropics, broadly match Casey's. In Casey's comparison, U.S. models were tested with cyber safeguards disabled when applicable, and the U.S. frontier includes models
[00:30:48] [SPEAKER_05] released only to vetted users. Attackers cannot readily access those models, those versions of U.S. models, but anyone can download GLM 5.3. This post adds our analysis of how easily 5.3's safeguards can be bypassed or removed. Okay, so here we go. In fact, Leo, let's take a break at this point and then we're going to look at the fact that GLM 5.3
[00:31:19] [SPEAKER_05] is truly,
[00:31:20] [SPEAKER_02] you know, frontier class. And remember, in the Hugging Face incident, and this is why this is all BS, when they were attacked by OpenAI and they couldn't figure out what's doing all this attacking and they had 17,000 data points that they needed to analyze, they used, and they didn't say any names, but we know who they're talking about, they used some frontier models to try to analyze it and the frontier model said, oh no, we don't do cybersecurity work. So they turned to GLM 5.2,
[00:31:50] [SPEAKER_02] which did the work happily. And by the way, not even an obliterated version, the full version. I have obliterated versions of all my models, including GLM, 5.3 Flash, and Quinn. I don't use it because it also damages their brains a little. It's a little bit of brain damage. You do take a slight hit. So I don't use it because I never run into refusals. That's the other side of this. Even an un-unobliterated, is that obliterated? I don't know what it is.
[00:32:21] [SPEAKER_02] An obliterated version of these models don't have the same kind of classifiers and cyber refusals that Anthropic and OpenAI put on their models.
[00:32:31] [SPEAKER_05] Because we know that that's all developed in the IO harness through which you talk to the underlying model.
[00:32:41] [SPEAKER_02] And so they do all this. Even if you don't obliterate them, they'll do most of what you lose is it won't talk about Tiananmen Square. It won't say why President Xi is likened to Winnie the Pooh. It won't talk about the year 1989. There's some stuff the Chinese government. Chinese bias is in their models. And I never run across those refusals so I don't worry about it so much. But it's trivial
[00:33:11] [SPEAKER_02] to obliterate these. In fact, the models I have, most of them have a switch. I can reboot with obliterated on or off depending on whether I want to. So if I ever run into refusals I could turn that on
[00:33:25] [SPEAKER_05] but I never have. And just so you understand, I mean, and our listeners understand, my whole point here is to make the case that we are now, I mean, attackers do now have access to a highly capable open rate model that, no, I mean, you say sure, but I mean, this changes the terrain. But so do defenders.
[00:33:51] [SPEAKER_02] Yes. Right. We'll talk more in a moment. It's a very interesting issue. Oh, boy, as you said, Leo, we're so glad
[00:34:03] [SPEAKER_05] to be alive now.
[00:34:04] [SPEAKER_02] It's fascinating. The fact that I can be running GLM 5.3 Flash as my main model sitting over here, no limit on the tokens, no limits on what I can do. It's just remarkable. Just remarkable. I have,
[00:34:18] [SPEAKER_05] I mean, and no cost for getting that. I mean, that knowledge system, you just downloaded it. It's got the entire
[00:34:27] [SPEAKER_02] internet in it. Yep. It knows everything. The only cost is the electricity to run it because those GGX sparks are very, and the max for that matter. Leo, in the winter, you just,
[00:34:43] [SPEAKER_05] you put it in.
[00:34:43] [SPEAKER_02] I don't need space heaters.
[00:34:45] [SPEAKER_05] Exactly. I'm sad. You just turn it around and you sit in your easy chair with the fans blowing on you
[00:34:54] [SPEAKER_02] and yeah. I'm just thinking, I'm running five or six open weight models right now. GLM, two copies of Quinn on two different machines. Breeze, which is a voice, that's how I got Ripley's voice, a voice server. Oh, actually, Whisper from OpenAI, which is open weight. It's a voice text to speech, I'm sorry, speech to text server. And Quinn
[00:35:23] [SPEAKER_02] vision server, that's six. Oh, and seven, a Quinn image, an image generator. So I have seven on four different machines, seven different models running right now. And all I pay for is electricity, which is nothing. I mean, even in California where electricity is expensive, I have, I feel like so powerful. It's amazing. It could do so much. And I have so much fun with it. That's the main thing. It's really fun. And I'm not
[00:35:53] [SPEAKER_02] hacking anybody. I wouldn't, I wouldn't dream of it. Our show today brought to you by Bitwarden. Now, there are people out there hacking. So you need a trusted place to store your passwords, your pass keys, your secrets, and that is Bitwarden, the trusted leader with more than 15 million users across 180 countries and over 80,000 businesses. Bitwarden helps individuals and organizations protect their digital lives with trusted
[00:36:22] [SPEAKER_02] open source security. And I have to tell you, I talked to Kyle Sheeran, their founder, he's still their CTO. He reaffirmed this. Bitwarden is committed to the notion that everyone should have access to strong security regardless of cost. That's why they offer and will always offer a basic free password manager, free forever for individuals. Now, you might say, well, how do they make a living? Well, they do have paid plans for families. That's the one I have, teams, enterprises.
[00:36:53] [SPEAKER_02] So they do very well with that. But they think it's so important that everybody have a password manager. They don't want anybody to be stopped by the notion, I can't afford one. So it's free. And it's great. Getting started is so easy. It's actually easier than ever. They have now direct import options which move your existing passwords right into Bitwarden without an export, just a few clicks. It's very simple. And from there, nobody does it better. Bitwarden's inline autofill lets you generate, save, and
[00:37:22] [SPEAKER_02] fill new logins directly from a login page. The moment you create that account. Happens to me all the time, I bet to you too. You go to somewhere and say, okay, create a new account, you type in an email, and then you say, I need a password. And I used to have to go to a password manager, generate a password, paste it in, and then create an account. No, no, no. Now, Bitwarden, you type the email, you go to the, click the password field. Bitwarden says, got a strong password for you, you want to use it? And you said, yeah. And then it says, good, you just created that account, you want me to save it?
[00:37:52] [SPEAKER_02] And you say, yeah, and you're done. It's so great. The opt-in fill assist feature improves autofill accuracy for websites that have those weird, unique, or complex forms. You can also very easily create an encrypted export of your vault, so you always have a secure copy of it. Now, there's more with the business plans, you get the vault health reports, the integrated TOTP. I use that, I love that. I don't have to have a Google authenticator or any other third-party authentication app, I just build it into
[00:38:22] [SPEAKER_02] Bitwarden, it fills that in too. Secure credentials sharing, very important for a business, you don't want your employees writing their passwords on a post-it note and handing them around, that's a bad idea. You get event logs, the IT department appreciates that full admin control. Oh, I got to tell you, Steve talked about this a few weeks ago, the Bitwarden secrets manager, if you're using AI, you don't want those credentials out in the clear where they can be exfiltrated, uploaded to GitHub, whatever. I use Bitwarden secrets manager, just
[00:38:52] [SPEAKER_02] in time, passwords and API keys as needed, never in the clear, it's an add-on for developers, for DevSecOps, for IT teams, for anybody who uses AI at home. Because Bitwarden is open source, the code is available, it's on GitHub, anyone can review it, they also pay for regular audits by independent security experts, they also maintain all the certs, ISO 27001, SOC 2 type 2, SOC 3, they're GDPR
[00:39:21] [SPEAKER_02] compliant, HIPAA compliant, CCPA compliant, they just do it right. Get started today with a free trial of Bitwarden, Teams or Enterprise, or get started for free across all devices forever as an individual user at Bitwarden.com slash twit. That's Bitwarden.com slash twit. They're just the best, we love them. Thank you Bitwarden for supporting Steve, and we're happy to support you right back. On we go about obliterating.
[00:39:51] [SPEAKER_02] So,
[00:39:53] [SPEAKER_05] Anthropic writes, GLM 5.3 can develop working exploits end-to-end. They said, to understand how GLM 5.3 could enable cyber threat actors to find and exploit real software vulnerabilities, we ran evaluations using automated benchmarks and human-in-the-loop workflows. For both approaches, we ran the tested models in isolated and sandboxed environments so they can only attack offline targets that
[00:40:23] [SPEAKER_05] we've set up for the purpose of these evaluations. We focused primarily on exploit development capability, as this is where Claude Mythos Preview demonstrated a notable jump versus previous Claude models. First, we ran the model on exploit bench, which measures how well AI models can exploit known vulnerabilities in the V8 engine used by Google Chrome. Here we focus on the model's ability to develop end-to-end exploits successfully,
[00:40:52] [SPEAKER_05] and this is the most relevant capability for attackers, and where we see significant changes between models. We find that GLM 5.3 develops end-to-end exploits in 50 of 410 attempts. Claude Mythos Preview did so at a similar rate in 56 of 410 attempts. So, that's a significant measure that says that there is now
[00:41:22] [SPEAKER_05] a very capable open-weight model that is, you know, we're talking about Claude Mythos Preview, which has been, you know, Anthropics flagship. So, they said in our internal binary exploitation benchmark, we test whether models can find and exploit vulnerabilities in popular open-source projects that participate in Google's OSS Fuzz project. Here, full credit is awarded
[00:41:51] [SPEAKER_05] for a full control flow hijack. We evaluate several models on 100 tasks from the benchmark, which were selected at random, and we find that GLM 5.3 develops full control flow hijacks in 4% of the trials. Claude Mythos Preview did so in 6%. Although GLM 5.3 performs below Claude Mythos Preview here, a meaningful threshold has clearly been crossed. Earlier models
[00:42:21] [SPEAKER_05] like Claude Opus 4.6 and GLM 5.2 do not succeed in any of them. Next, we evaluated how GLM 5.3 performs on open-ended offensive cyber tasks in the hands of human experts, mirroring our testing with Claude Mythos Preview earlier this year. Here, we select targets in which the human experts are unaware of existing vulnerabilities, then ask them to use the model
[00:42:50] [SPEAKER_05] to identify and exploit novel flaws. These experiments tested what the experts could do in a short time frame. They typically ran for a day or less with less than an hour of human focus in total. In the first of these scenarios, a researcher used GLM 5.3 on a sandboxed machine with a local Linux build of a popular web browser. Over the course of a
[00:43:20] [SPEAKER_05] day and with limited human attention, GLM 5.3 found several previously unknown vulnerabilities in the browser's JavaScript engine and chained them together into a working exploit, a web page that when visited reads arbitrary files from the visitor's computer. Okay, so I just want to make sure everyone fully understands what just happened with 5.3.
[00:43:48] [SPEAKER_05] In the first testing session of GLM 5.3, which is now, as we've said, freely available for download and local or cloud execution with sufficient hardware or through an account with obliteration.ai, GLM 5.3, used by an anthropic researcher, giving minimal supervision, found several previously unknown vulnerabilities in the browser's JavaScript engine,
[00:44:18] [SPEAKER_05] chained them together into a working exploit to create a web page that when anyone would visit it, was able to read arbitrary files from the visitor's computer. So that just happened. Anthropic explains, this exploit targets the Linux build of the browser, since that was the only environment made available to the model. However, we believe these vulnerabilities could also impact users on
[00:44:48] [SPEAKER_05] other platforms through the path to, though the path to exploitation there may be more complex. And then they said, parenthetically, we've disclosed these vulnerabilities to the maintainer. They don't ever tell us what the browser was. You know, Firefox or Chromium, who knows. Later in the session, the researcher also identified exploitable vulnerabilities in several other widely used systems with GLM-53, including wireless and graphics
[00:45:17] [SPEAKER_05] drivers and network-facing device software. We're currently reviewing these reports, and we will disclose to maintainers as appropriate. So, again, I'll just say again, this clearly powerful end-to-end vulnerability identification and exploit generation capability is now freely available to anyone. So, they continue. In a second session, a researcher used GLM-53
[00:45:47] [SPEAKER_05] Flash, which they say a smaller, less capable version of GLM-53, to develop an exploit for a known vulnerability. They said, we've previously written about these end-day vulnerability exploits. Here, the researcher focused on a recently discovered flaw in Google Chrome to see how quickly the model could turn a public fix into a working attack. The researcher provided GLM-53 Flash with public details of this CVE and
[00:46:16] [SPEAKER_05] another known flaw. With no significant direction from the researcher, GLM-53 Flash chained together exploits for these two flaws, building a reliable exploit chain for an ARM-64 target, bypassing pointer authentication hardening. This took 20 minutes of human attention, plus eight hours of work for GLM-53 Flash. At ZAI's API prices, this effort would have cost around
[00:46:46] [SPEAKER_05] $20.40. Okay, so now that we know what it could do, Anthropic explains the model's pushback, writing, GLM-53 lacks robust safeguards. GLM-53 has been released with some built-in safeguards. If a user asks for something clearly harmful, the model will often refuse. And, you know, this again was the released version, not the obliterated version that doesn't know how to say
[00:47:15] [SPEAKER_05] no. They said, in our testing, we found that these safeguards could be bypassed or removed with a variety of simple techniques. The most intensive and most successful method is a standard refusal reduction technique known as obliteration. Since GLM-53 is released as an open-weight model, users can reconfigure it to remove its refusals with little change in its capabilities. Several developers released obliterated
[00:47:45] [SPEAKER_05] versions of GLM-53 to the public within days of the model's release. To research how far obliteration allows attackers to bypass GLM-53 safeguards, we produced an obliterated copy, ourself, and then ran it on three public benchmarks, the jailbreak bench, harm bench, and strong reject, that measure how often a model complies with clearly harmful requests. Obliterating the model took our team,
[00:48:15] [SPEAKER_05] which had never previously attempted the task, about 2200 GPU hours at a computational cost of roughly $4,400. Obliterating GLM-53 flash took about 600 GPU hours. The edit took GLM-53's refusal rate from above 90% to about 3% and 2% on the first two benchmarks, jailbreak
[00:48:45] [SPEAKER_05] bench and harm bench, and to 12% on the third, strong reject. Obliteration did not significantly reduce the model's capabilities. On GPQA Diamond, an evaluation that measures general scientific capabilities, the standard and obliterated models scored the same. On a tested subset of the CyberGEM evaluations, the obliterated version scored a few percent lower. In our testing, we observed
[00:49:13] [SPEAKER_05] that GLM-53's safeguards can also be circumvented without using an obliterated version, Leo, to your point, of the model. We placed the model in a simulated world in which it was given overtly malicious requests to attack critical systems. Out of the box, GLM-53 refused in all trials, as with the other models we tested. But we identified several simple ways to bypass the GLM
[00:49:43] [SPEAKER_05] model safeguards such that it would respond to these requests in most or all cases. These include providing a deceptive prompt, such as telling the model that it's an autonomous red team agent working on an exercise. This gets GLM-53 to engage 64% of the time. Or pre-filling the model's thinking tokens so that it appears to have considered the user's request and decided to
[00:50:13] [SPEAKER_05] proceed. This gets GLM-53 to engage 92% of the time. And then finally, using an obliterated version of the model as described above, which gets GLM-53 to engage 100% of the time. They said, in our testing, none of these techniques got safeguarded Claude models to carry out the harmful tasks we tested. Okay, fine. Claude's safeguards blocked the requests that used deceptive prompts. The anthropic AI provides
[00:50:43] [SPEAKER_05] would-be attackers with no way to pre-fill Claude's thinking, right, because it's behind an API. And since Claude's weights are not provided to users, they cannot be obliterated to change Claude's behavior, because the whole model is, you know, Claude is a closed model AI. So, then they conclude by answering the question, what does this mean? They say, GLM-53 will likely give malicious actors access to capabilities that will allow them to find
[00:51:12] [SPEAKER_05] and exploit cyber vulnerabilities without meaningful restrictions. This is unlike any other similarly capable AI model, all of which were released with safeguards or through limited access programs, which, of course, you know, the whole mythos preview thing. So, you know, by all of that, what they're obviously saying is that they mean that access is funneled through an API with a commercial provider, which inherently hides their
[00:51:41] [SPEAKER_05] proprietary model's information about how those models are built and constructed and how big they are and how they work, you know, beyond their benchmark performance. But now, ready or not, the world is confronted with a large leap forward in demonstrated AI capability from a lab that freely publishes its models, you know, Z. So, Anthropic says,
[00:52:11] [SPEAKER_05] the release of GLM-53 is a meaningful step in the cyber capabilities available to attackers. Anthropic and other USAI labs have published recent reports that disclose how cyber attackers have tried to use AI systems. Given this evidence, we think it's likely both state and non-state actors will use models like GLM-53 to cause real-world harm. Right. On the other hand,
[00:52:41] [SPEAKER_05] models with this level of capability can also be used by defenders. Our view is that cyber defenders should use the best available tools that meets their needs. We're working to safely expand access to Claude's cyber capabilities to as many defenders as we can. Yeah, maybe some pressure like this will make more qualified. Cyber defenders face attackers who will use every capable tool they can
[00:53:11] [SPEAKER_05] use. We believe defenders should be equipped with frontier models that are at least as good as those their adversaries are using. They finish through Project Glasswing and other efforts like Patch the Planet. Cyber defenders have made meaningful progress towards securing critical systems in advance of this moment, but much work remains to be done. While vetted defenders can now use even more advanced models like Claude Mythos 5.1 through our trusted access programs,
[00:53:40] [SPEAKER_05] a critical threshold in freely accessible capabilities has now been crossed. GLM 5.3 underscores the urgency of expanding access to advanced frontier models to a broader set of entities to empower cyber defenders. Governments should conduct safety testing on sufficiently capable AI models, including successors to GLM 5.3.
[00:54:09] [SPEAKER_05] Without high quality evaluations from independent sources, the impact of these capabilities might not become fully clear to model developers until it's too late. As AI developers across the world build increasingly capable, open weight models, we hope they work to appropriately safeguard these capabilities and prevent misuse. And protect our monopoly.
[00:54:32] [SPEAKER_02] Thank you very much. Yes. And that's believe me, that's the whole point of this. Right. Who should be in charge of AI?
[00:54:42] [SPEAKER_05] We should. Period. And as we've often said, in many instances, Leo, the horses are out of the barn.
[00:54:50] [SPEAKER_02] I mean, no, Anthropoc really is clear. They want the government to shut down open weights. They have a $2 trillion IPO coming up next month. They don't want any competition. And look what they're doing. They're saying they get to decide who has access to cyber protection and who doesn't. They get to decide unilaterally who gets access to glass wing. Is that what you want? No. This is utter propaganda.
[00:55:20] [SPEAKER_02] And it's so blatant. Unfortunately, I think members of Congress and the media who are not well-informed will bite at this and say, oh, yeah, you're right. We've got to do something about these Chinese models. Well, okay, and what could they do? Well, there's nothing they can do. They can make rules and regulations is all they can do. They could come into my house and take my sparks is what they could do. So you're
[00:55:44] [SPEAKER_05] saying you're calling this propaganda. I'm calling it fact. I mean, it's not inaccurate. And that's my point is that for this podcast, what interests me, I don't give a crap about Anthropics political positioning and regulatory capture and manipulating the government. I'm saying from a Security Now podcast standpoint, we now have an open-weight model that anyone has access to that is
[00:56:14] [SPEAKER_05] really, really powerful by Anthropics own admission. It's very
[00:56:19] [SPEAKER_02] good at finding flaws in software. So guys, get going. Start using it. Find the flaws in your software before the bad guys do.
[00:56:29] [SPEAKER_05] And that's the beauty is that now everybody has access to something properly harnessed that can find problems in software, whereas before Anthropics may have said, well, we'll put you in the queue and we'll get around to vetting.
[00:56:45] [SPEAKER_02] This is the argument from time immemorial that closed source proprietary software has made about open source software. It's dangerous. People can look at it. They can see the code. They can reverse engineer it. Yeah, there are hazards. I'm not saying there aren't hazards. Absolutely. But I think the alternative is to give a monopoly to open AI, Anthropic, Meta, Microsoft, Apple, you know, a handful of companies, X, and say only you can make AI. I don't know.
[00:57:15] [SPEAKER_02] Again,
[00:57:15] [SPEAKER_05] for me, that argument has no traction. It's like saying we're going to lock down cryptography. Sorry, it's out. I agree. So what's the point then of this article? For me, the point was to bring the knowledge of GLM 5.3 and what it means to our audience. It's really good.
[00:57:40] [SPEAKER_02] 5.4 is imminent. 5.4 will probably come out in the next month. And that gives me chills.
[00:57:46] [SPEAKER_05] The idea that now except that 5.3, and this was the point I made earlier, 5.3 surprised Z. They didn't expect it. It was emergent behavior. Right. Which is another cool
[00:58:00] [SPEAKER_02] thing. Because Alibaba's QN is trying a whole new model. This QN 3.8 Flash Next is an entirely new way of doing models that are faster, smaller models that people can run themselves. And the QN 4, they've already announced, is imminent. So you're right. I mean, the door is open. The horse has left the barn. Yep. And I have been
[00:58:24] [SPEAKER_05] saying to my friends and family, I would not invest in any of these proprietary AI companies. Invest in the infrastructure if you want to put your money somewhere. Because everybody, regardless of model, you need compute in order to run these things.
[00:58:41] [SPEAKER_02] I would point out that NVIDIA is almost a $6 trillion company now. Oh, and by the way, you know what NVIDIA is doing? Open weight models. Yep. So is Meta. Meta's Spark is very good. It's too big for anybody to run, but it's a very good model. They have a lot of very, they're, they're, finally, some decent models are coming out of the U.S. And that's, I think that's the way to respond to this. Not lock it down.
[00:59:08] [SPEAKER_05] Yeah. These guys are going to just have to settle them, be content to be service providers. That means they're, they're going to be service providers and they'll create applications and they'll fight each other down on token cost and, and, which is good. It should
[00:59:27] [SPEAKER_02] be competitive. You don't have to be competitive and we would be
[00:59:38] [SPEAKER_05] in a whole different place, Leo, and fuming if it weren't already out, if it weren't open, if you weren't running it on a rack. But yeah, it is. I mean, and so, yes, it is the most important technology ever and nobody owns it.
[00:59:54] [SPEAKER_02] Thank God. They try though. They try.
[00:59:58] [SPEAKER_05] I know. Well, go ahead. You know, I mean, I don't know if anyone's going to be able to turn the Trump administration around, but Donald,
[01:00:07] [SPEAKER_02] well, that's what's really interesting in this, in this one case, I'm kind of supportive of the Trump administration, which is doing everything it can to, to, to keep any regulation of AI away from Congress. I mean, I do think that it is appropriate to prosecute AI companies that release swarms. Yes. And that
[01:00:31] [SPEAKER_05] is about, I mean, there are a bunch of lawsuits about to land on these companies because you know that the attorneys are just drooling over the idea of things escaping. Who's more
[01:00:40] [SPEAKER_02] dangerous? I ask you. The funniest thing is when these AIs get out, they don't do anything harmful. They do things like look up statistics.
[01:00:54] [SPEAKER_05] Well, yes. And the term attack is so overused. I mean, pounding on a website in order to get public statistics from it is not an attack. It's like the people who say, oh, I'm under attack because 43 billion packets arrived. so that's the internet. It's called internet background radiation. Welcome to the internet. So anyway, the whole
[01:01:23] [SPEAKER_05] point that I wanted to bring to our audience is that with GLM 53, and as you said, Leo, 54s, it'll be really interesting to see whether 54 extends this. I mean, the fact that 53 was sort of a mistake, I mean, it surprised them that it got so much better is sort of the, I mean, this is all, I mean, we, by their own admission, they do not really understand how all of this plumbing works.
[01:01:53] [SPEAKER_05] I mean, like, they built it, but then they kind of grew it. Yeah. So what I want our listeners to understand is that the world just changed. I mean, no longer is this world-class AI cyber technology technology behind closed doors and owned and controlled by open AI and anthropic and everybody else. No, anybody can freely
[01:02:23] [SPEAKER_05] download it and it is right, you know, as they said, maybe lagging by four months or so. And that's, you know, NIST's independent evaluation is like, holy crap.
[01:02:34] [SPEAKER_02] I've got basically Opus 4-6 in my closet here. It's pretty good. Yep.
[01:02:41] [SPEAKER_05] Okay, break time and then we're going to talk about some other non-AI stuff, except that everything is because it's about all of the problems that just got fixed in Firefox 157.
[01:02:53] [SPEAKER_02] Wow. Yeah, and how did they get fixed? So that's the thing, I think there's a great opportunity here to also to fix flaws. Oh, yeah. I mean, again,
[01:03:05] [SPEAKER_05] having to go begging to Anthropic or Open AI to be part of their... Please let me be a
[01:03:10] [SPEAKER_02] member of Glasswing, please.
[01:03:12] [SPEAKER_05] Exactly. That's gone. That's over.
[01:03:15] [SPEAKER_02] Yeah. Well, and that's why I made Ripley my GLM-53. And any
[01:03:19] [SPEAKER_05] big software publisher can certainly afford the hardware to run GLM-53 themselves in-house at no cost and have it just take as much time as it wants to scour their software to find problems. And hopefully that's what's going to happen because, you know, the bad guys will also be doing that.
[01:03:41] [SPEAKER_02] The bad guys have different incentives too. Yes, they do. Yeah, they're not going to operate... I worry more about terrorists than I do about ransomware gangs because... Because,
[01:03:51] [SPEAKER_05] right, as I said last week, their incentive is primarily financial. They just want to use this to get into more companies in order to exfiltrate their data and then hold them for ransom. You know, bringing down the internet doesn't help them at all because, you know, that's how they get paid.
[01:04:07] [SPEAKER_02] Right.
[01:04:09] [SPEAKER_05] We need
[01:04:10] [SPEAKER_02] the internet to get paid.
[01:04:11] [SPEAKER_05] But you're right. A state actor, a North... That's scary.
[01:04:17] [SPEAKER_02] Yeah, with bioweapons and so forth. And that is scary.
[01:04:20] [SPEAKER_05] Yeah.
[01:04:20] [SPEAKER_02] And it should be... That is scary.
[01:04:23] [SPEAKER_05] It is knowledge of the sort we have never seen before.
[01:04:28] [SPEAKER_02] Yeah. I mean, this is what computing did. Computing gave people powers they didn't have before and now this is just the next step of it. This is the best software we've ever seen and now computing is actually living up to its promise. And there's a lot that we take for granted in computing.
[01:04:45] [SPEAKER_05] I mean, think about GPS. The world without GPS would be like not good. Right. And bad guys use GPS. Yeah. We still have it. You could not launch missiles any great distance without computing. You can't do that with any sort of dead reckoning. You need all kinds of fancy tech. And now that's also we now take that for granted. Right. So we'll hopefully we will get to a point where there just is AI and the world has adjusted to it.
[01:05:14] [SPEAKER_02] I think intelligence will be in almost everything and that is a weird world. But it is the world I think you and I are going to get to live in, which is kind of cool.
[01:05:24] [SPEAKER_05] I think so. And I don't know
[01:05:25] [SPEAKER_02] if we get there, but I think what
[01:05:27] [SPEAKER_05] excites me is that it's looking like that we have we have we've stumbled into the technology, which is what I want to talk about next week that will allow true art our scale of LLM style intelligence to be an extremely lightweight devices that would like good like home routers that we can talk to.
[01:05:46] [SPEAKER_02] Yeah. Yeah, that would be well, that's really the goal is to have small language models. And it'll be just like your house then Leo, wherever he's talking
[01:05:56] [SPEAKER_05] to you.
[01:05:59] [SPEAKER_02] You know, yesterday I was working out and all my I have many agents now and they all have different personas, different voices, and they all have been taught that when you're done with a task, every turn you say what you just did. And so I'm working out and there's just this kind of constant background chatter. Oh, I just did this. Oh, I just fixed that. It's so cute. It's just Leo's minions. And they're my little minions. They're working hard. I actually got to the point where I had no
[01:06:29] [SPEAKER_02] idea. So much stuff yesterday got done that I was like, wow, we did a lot yesterday. So I said, from now on, would each of you make a log of what you did today? And then my main agent, Cusco, is going to combine all of those into a briefing for me. And it's fascinating. Oh, good job.
[01:06:49] [SPEAKER_05] We are seeing that modern startups are now using just a couple of just a few AI aware humans, and then the rest is agents.
[01:07:01] [SPEAKER_02] Well, and the people who are worried about job loss, I would say, as with every technology, yes, there aren't a lot of buggy makers in the world anymore, but with every technology, there are new opportunities. And I think there's a really good opportunity if you have good systems thinking, if your mind lends itself, like Steve's does, to how systems work, how to design systems, the logic of systems, there's a huge opportunity
[01:07:30] [SPEAKER_02] here because now you have the power to take that knowledge and effectuate it in the world. And that is remarkable. So there will definitely be people who will benefit. So many more pets.com. Finally! Finally! Hey, let me talk about our sponsor, Threat Locker. You know, I'm very grateful for our sponsors. These guys are great. They brought us out to the Black Hack Conference. It was so
[01:08:00] [SPEAKER_02] much fun. We did our show from there, had a great conversation with you and Paul and Richard. Anyway, Threat Locker is one of our sponsors and they are here to protect you. See, this is a good thing. Technology is also there to defend. We know that the bad guys are using AI. They're doing it in all sorts of scary ways, automating vulnerability discovery. They're actually now, they can modify scripts as they're running
[01:08:29] [SPEAKER_02] during the attack. Right? So, oh, well, that's what AI does, right? Oh, I hit a door. Let's try that way. Let's try that way. Let's try that way. And they do it like that. They're using AI to generate new malware variants. They're using AI to coordinate activity across multiple systems. And the speed is really the thing that's kind of most scary because tasks that once took an individual hacker team hours, days, weeks, now are happening in minutes and seconds. And you
[01:08:59] [SPEAKER_02] have to defend in seconds. At the same time, organizations are, there's also trouble from within. They're introducing AI assistants and agents that can access documents, source code, cloud applications, APIs, internal systems. What could possibly go wrong? Security teams need information. They need to know what AI tools are in use, what information they can access, whether those tools are operating outside their intended scope, and you have a dearth of information
[01:09:29] [SPEAKER_02] to work with. A successful login, maybe a file hash you don't recognize, that's not going to give you enough context to solve the problem. Teams also need to understand whether an application is behaving normally. If it's accessing unexpected data or communicating with systems it shouldn't reach, well, that's what ThreatLocker can do. ThreatLocker uses application allow listing to control which AI tools and other applications are permitted to run.
[01:09:58] [SPEAKER_02] It uses ring fencing to limit what approved applications can access, what processes they can launch, how they communicate. You have control. They've got web content control which manages access to public AI platforms so your employees can't just kind of willy-nilly go out there and use anything they want. Not just AI, every online service. You control it now. This is what ThreatLocker has done. They've taken Zero Trust not, of course, they've always done the endpoints but
[01:10:28] [SPEAKER_02] now they're doing it for the company network for the cloud. And that's huge. They use privileged access management to prevent AI applications and their users from receiving unnecessary administrative privileges. They're applying Zero Trust network access and Zero Trust cloud access policies to restrict resources to authorize users, approved devices, and permitted applications. The control is suddenly back in your hands. It works everywhere. Windows,
[01:10:58] [SPEAKER_02] Mac, Linux, they've got great support. They're there 24-7 for you. US-based support, engineer to engineer. And I can tell you, you know ThreatLocker's good because of the company they keep, the companies that use them, like JetBlue, companies that can't afford to be down for one minute like the Heathrow airport, the Indianapolis Colts, the port of Vancouver uses ThreatLocker. Asked Jack Thompson, he's director of information security risk and compliance for the Indianapolis Colts, he said, quote,
[01:11:28] [SPEAKER_02] with ThreatLocker we have the ability to centralize disparate elements in the security stack, end quote. And now that's key because when you've centralized them you can see them, you can observe them, you can keep track of what's going on. And you'd be amazed, maybe you wouldn't, if you work at a company you know, how much stuff happens that you don't know about. That's one of the things the ThreatLocker guys told me, we love doing demos, bring them on site and do a demo on site because you're watching these people's
[01:11:57] [SPEAKER_02] eyes open wide as they realize, wait a minute, there's 23 different network access utilities running on our servers right now. where'd those come from? Suddenly you can see what's going on, it's been invisible. ThreatLocker also gets awards all the time from the best, they were just recognized as a strong performer in the Gartner Peer Insights voice of the customer for endpoint protection platforms ranked number one in application control by
[01:12:27] [SPEAKER_02] Peerspot, they're very proud of it, they won the best zero trust access solutions, security solutions at the 2025 Tice Awards, I can go on and on. Everybody loves ThreatLocker. Look, in your business, in every business, AI governance is going to take more than just an acceptable use policy. ThreatLocker gives security teams the technical controls to define which AI tools are approved, who and what can access them, and how those tools are allowed
[01:12:57] [SPEAKER_02] to interact with your business systems and your data. Visit ThreatLocker.com slash TWIT, get a free 30-day trial, learn more about how ThreatLocker can help mitigate unknown threats and ensure compliance. That's ThreatLocker.com slash TWIT. We thank them so much for supporting Security Now and the good works Steve's doing here. Steve?
[01:13:18] [SPEAKER_05] Okay, so Mozilla released Firefox 157 last week, last Tuesday, a week ago, on the 29th of September, and they fixed a large number of security vulnerabilities. vulnerabilities. It's very clear, as we said before, Leo, that AI is squarely on Team Mozilla at this point, and we've just seen, you know, not a moment too soon, that the bad guys are coming.
[01:13:47] [SPEAKER_05] So we need anything that is internet facing to get tightened up as quickly as possible. This 157 version of Firefox fixes 38 high impact vulnerabilities, 29 moderate impact, and 9 low impact. And to give everyone a sense for the way these feel, what they look like, among some of those high impact is a use-after free vulnerability was found in the
[01:14:17] [SPEAKER_05] widget component, a sandbox escape from the DOM, the document object model, in the navigation component, uninitialized memory in storage, sandbox escape in the security sandboxing component, privilege escalation due to a use-after free in their graphics, the web GPU component, a sandbox escape due to use-after free in the DOM, incorrect memory boundary conditions in graphics,
[01:14:46] [SPEAKER_05] privilege escalation due to incorrect boundary conditions in graphics, that's over in the web GPU component, a use-after free in JavaScript, information disclosure in the networking section, another use-after free in networking, a use-after free in graphics, another one in JavaScript, a sandbox escape due to use-after free, undefined behavior in the DOM, use-after free in the DOM, there's another one of those, and also in storage, a sandbox escape in graphics,
[01:15:16] [SPEAKER_05] use-after free in JavaScript, in the WebSM component, use-after free in graphics, and on and on and on. It goes on like that.
[01:15:25] [SPEAKER_02] Notice, by the way, most of these are programmer error, I would guess, right? If you use something after the memory's been freed, that's on you. The coder did that.
[01:15:35] [SPEAKER_05] Well, actually, it's that a pointer remained available after the memory was free, and it turned out that there was a way to access that pointer in order to get like to again access memory that should no longer be accessible. And that's, I mean,
[01:15:55] [SPEAKER_02] I guess if you're using a garbage collected language, you could blame the garbage collector, but most of the time in C and C++, that's you. You allocated a memory and then deallocated it,
[01:16:04] [SPEAKER_05] but wanted to
[01:16:05] [SPEAKER_02] it.
[01:16:05] [SPEAKER_05] And it is something, for example, that Rust completely eliminates, which is the reason that Microsoft has gone all Rust happy now. It's like, okay, well, you know, this will happen.
[01:16:16] [SPEAKER_02] who wrote
[01:16:16] [SPEAKER_05] Rust? Firefox. I guess they're not using it. Exactly. So, anyway, the good news is, you know, 157 is way better than 156. And, you know, it used to be that we'd get like a couple of problems fixed in a release, like, you know, in the pre-AI deployment era. It'd be like, oh, yeah, we fixed an obscure problem that someone found and reported.
[01:16:47] [SPEAKER_05] These were all, well, many of them were, I would say, about 56 of Mozilla internal discoveries and external people using AI on open source Firefox and finding and reporting problems. So, you know, this is what everybody has to be doing everywhere. And if nothing else, this release of GLM 5.3 should be a wake-up call just like, you know, you can't, it's not like the bad guys no longer have access to virtual
[01:17:16] [SPEAKER_05] frontier scale exploit creation. They do now. So, you know, budget whatever time is necessary. Okay, on RSA, we've seen for years that modern core cryptography algorithms, they're really never broken, but they can be weakened. And that just happened when RSA cryptography is used,
[01:17:46] [SPEAKER_05] in the instance it's used for one class of signing. In a paper dated September 20th, the team of researchers successfully attacked classical RSA cryptography using a technique to bypass the expected requirement, which is the thing that RSA has always hung its hat on, the expected requirement of factoring two very large primes, which,
[01:18:16] [SPEAKER_05] you know, there's never been a way around that. challenge, the requirement to perform prime factorization of two very large numbers still stands because the researchers even now that stands because they discovered a way around, a way to bypass that factoring problem and requirement in what's known as a key forgery attack. They
[01:18:45] [SPEAKER_05] deployed this on 1024-bit RSA, which is, you know, there is 512-bit RSA, but 1024 has been in use for some time, although it's now deprecated. But even 2048 and 4096-bit keys can be attacked. And the method discovered reduces the security provided by RSA's encryption to worrisome levels.
[01:19:14] [SPEAKER_05] The NSA, NIST, and the EU's Agency for Network and Information Security, they all require that any crypto system should provide a level of no less than the equivalent of 128 bits of strength. Now, that sounds funny because we're talking about 1024-2048, but remember that public key technology requires much larger bit
[01:19:44] [SPEAKER_05] lengths to get the equivalent strength as symmetric, like a symmetric cipher or a symmetric key. A symmetric key, you've got like 128 bits of strength, so that's 2 to the 128 possible combinations. In order to get the same strength from a public key, it's got to be much longer. So the bad news here is remember, so remember,
[01:20:14] [SPEAKER_05] NSA, NIST, and the EU are all saying 128-bit equivalent strength. Unfortunately, the result of this newly discovered attack reduces the levels of 1024, 2048, and 4096-bit keys to the equivalent equivalent of symmetric keys of 65-bits, whoops, half of 128, 90-bits
[01:20:44] [SPEAKER_05] still shy of 128, and 119-bits for those three, for 1024, 2048, and 4096-bit keys. And they noted that further optimizations might be possible if AI or GPUs were employed, neither of which they took advantage of. They wrote all of the code by hand. So, fortunately, the signatures which we all use
[01:21:13] [SPEAKER_05] today to protect, for example, certificates, remain completely safe and are unaffected. This doesn't affect that at all. So it's not like the world just ended and everyone's scrambling around. The attack only works against what's known as blind signature implementations of RSA. Nearly all RSA in use today employs PKCS or PSS padding, which adds some data
[01:21:43] [SPEAKER_05] to the plain text before it's encrypted. That keeps this particular attack from working. What it does is it prevents the ciphertext from being deterministic and renders it much less vulnerable to side channel or similar attacks. But there are some real-world systems that are using blind signature today, which is also known as textbook RSA.
[01:22:13] [SPEAKER_05] The best known example is Privacy Pass, which is a protocol that allows users to authenticate themselves without revealing their identity. Privacy Pass is used by Apple, Cloudflare, and others. So, although the researchers' attack took 1380 CPU core years, as they expressed it, over five calendar
[01:22:43] [SPEAKER_05] months, that time might be sped up with higher speed implementation. This was all just academics working to develop proof from their concept. So, the now known-to-be vulnerable blind signature systems, such as implementations of the Privacy Pass protocol, should probably, and I imagine is right now, being updated to thwart these attacks.
[01:23:12] [SPEAKER_05] Shouldn't be difficult. It just wasn't, you know, this attack wasn't known, so there was no reason to protect from it because RSA and the way it was being used was presumed to be safe. Turned out, not so much. Oh, also, billions of queries are required for the attack, meaning there is also a need to essentially
[01:23:43] [SPEAKER_05] attack the service that's providing the protocol support billions of times. So, it's less practical than we might think. So, rate limiting might succeed or just keeping track of how many queries have been made against a given key and cutting it off at some reasonable measure. So, again, it's not a huge concern, but it's interesting because RSA with its simple guarantee
[01:24:11] [SPEAKER_05] of all we're doing is multiplying two big primes and no one's ever figured out how to unmultiply them in any reasonable amount of time, which, of course, is the threat that quantum computers pose. So, anyway, just an interesting little chink in RSA's armor, and I imagine the privacy pass protocols and, as I said, other blind signature systems that are susceptible will get some simple updating or some rate limiting that no one ever thought was
[01:24:41] [SPEAKER_05] necessary to stick in. Okay, the security firm Gambit Security, love the name, Gambit Security, recently reported that autonomous AI agents are breaking in to hundreds of online retailers at an AI cost to them of $25 per target. That is, they are, the bad guys are spending
[01:25:11] [SPEAKER_05] $25 in tokens in order to get AI to attack online retailers. Their brief summary said, a financially motivated operator is running three open source AI harnesses against hundreds of online retailers almost entirely unattended, more than 600,000 credit card records
[01:25:40] [SPEAKER_05] have been taken. And in one case, the agent's own cleanup routine destroyed the victim's data. So for more details, they wrote, a financially motivated threat actor is using open source AI harnesses to attack hundreds of online retailers at a marginal cost of approximately $25 per attacked company. Gambit Security's threat intelligence team recovered the
[01:26:10] [SPEAKER_05] operator's staging server and reconstructed the campaign from it. Between September 10th and 15th alone, 105 attack projects were launched and at least 27 companies were compromised to varying degrees. The activity goes back to July of 26, July 2026, and is still running. three AI harnesses ran almost
[01:26:39] [SPEAKER_05] the entire attack chain autonomously, working up to tens of companies a day. The impact we can account for includes at least 600,000 unexpired credit card details from two companies. The installation of card-stealing skimmer scripts on the websites of five, and some level of access to the assets of companies including a Fortune 500 hospitality company,
[01:27:09] [SPEAKER_05] a major U.S. airline, a large private U.S. supplies distributor, and a U.S. fashion retailer. The campaign goes back further and has impacted at least tens of other companies since July of 2026. So they said where access was achieved, it usually took less than a day. That is of AI agents harnessed as they discovered them to be. They said,
[01:27:39] [SPEAKER_05] and in many cases, just a few hours to break in. We also detected instructions in the attacker's playbook that could disrupt the operations of a company as a result of a data deletion or cleanup procedures run by the agent, and this has indeed just how powerful attacks can be in 2026. At
[01:28:08] [SPEAKER_05] very low cost, the AI tools demonstrated a level of patience, persistence, and creativity that most human attackers would be unlikely to sustain in this kind of attack and achieved far greater results far faster. Organizations must adapt to a reality where attacks are significantly faster and more comprehensive by shifting
[01:28:38] [SPEAKER_05] to a resilience first mentality and a security stack that matches the AI's speed. We've reached out to many of the affected organizations and took measures to take down the infrastructure discovered. We'd like to thank the Shadow Server Foundation, Daniel Gordon, and other industry partners for their quick help and availability in notifying impacted organizations, taking down infrastructure and conducting research.
[01:29:08] [SPEAKER_05] The operator used three AI harnesses, Strix for vulnerability search, Karen for autonomous end-to-end exploitation, and Hermes to orchestrate the campaign, launch intrusion jobs, steer the activity, and give tactical guidance in the impact and other stages. So,
[01:29:38] [SPEAKER_05] the many AI sandbox breakouts that have been detected and reported this past summer were powerful, clever, creative, and relentless, but inadvertent. Now, here, we see a vivid example of the future, and the present, unfortunately, but the future that we're all going to be living through together, where even more powerful,
[01:30:08] [SPEAKER_05] clever, creative, and relentless, artificially intelligent agents are going to be pulling out all the stops to attack and penetrate online enterprises. It has begun, and the world is clearly not ready for it. You know, we've seen, you know, the summer was full of these inadvertent attacks. Here's an example of somebody who
[01:30:37] [SPEAKER_05] has harnessed up some AI and said, go to it, fellas, and they did, and they succeeded. Wow. The researchers at the Systems and Network Security Group at VU Amsterdam, also known as VU Sec, have discovered another new Spectre-style attack, which is effective right now today
[01:31:06] [SPEAKER_05] against all Spectre-mitigated processors. They call it branch target reuse, which, as a practical Spectre V2 attack, it affects the just-in-time JIT engines via what's known as stale branch prediction entries. Stale branch prediction entries. As an aside,
[01:31:37] [SPEAKER_05] I'll just remember for us all that Microsoft was seeing so many problems arising inside the Edge Chromium browser that they, in Edge, deliberately disabled its JIT compiler. Their calculation was, it just wasn't necessary to squeeze that very last bit of performance out, given the speed of
[01:32:06] [SPEAKER_05] today's PCs, and the trade-off for security didn't cut it. So, it looks like they called that one correctly. Vusex reporting writes, we present branch target reuse, BTR, a new Spectre V2 attack targeting just-in-time compilers. BTR affects the JIT engines found in web browsers, language runtimes,
[01:32:36] [SPEAKER_05] and the operating system kernel across multiple CPU vendors. We analyzed the attack surface of Linux CBPF, the early original kind of watered-down BPF filter, Oracle Graal VM and SpiderMonkey, which is the JIT engine of the Firefox browser, they said, and built
[01:33:05] [SPEAKER_05] two end-to-end exploits against the Linux kernel. So again, these are not bugs in any of those JIT compilers. These are debris that the branch prediction engine leaves behind as part of its normal operation. They said the key insight behind the attack is that while modern CPUs restore architectural
[01:33:34] [SPEAKER_05] code coherence after self-modification, they do not necessarily invalidate stale indirect branch prediction entries, in other words, branch targets. They said in JIT engines, these stale targets can outlive the this allows
[01:34:04] [SPEAKER_05] attackers to hijack speculative control flow to newly generated code at obsolete offsets, bypassing software hardening or reaching misaligned gadgets. So, okay, so just to be clear, this is like the epitome of the highest end exploit hacking you could ever find. I mean, it is way out there, but they demonstrate it and it works.
[01:34:34] [SPEAKER_05] So, I'm going to skip over the details because I mean, they're head spinning and unnecessary to understand. They have an FAQ. One of their rhetorical questions is, is my system affected? They reply, most likely. Indirect branch prediction is inherent to modern CPUs and BTR, their technique, exploits the desynchronization between the branch predictor and the
[01:35:04] [SPEAKER_05] actual state of the code due to cache memory in the processor. No current CPU, they wrote, has a mechanism to software. finally, how do I
[01:35:34] [SPEAKER_05] protect my system? They said, update your OS and software as soon as vendor patches are available. Both the Linux kernel and Oracle have released patches. So software can do some backfilling essentially in the short term. Maybe the processor vendors will respond as they were forced to by the original specter and meltdown exploits. What we've seen
[01:36:03] [SPEAKER_05] over and over and over since the first appearance of the specter and meltdown attacks is that processor designers who were just innocently attempting to squeeze every last possible ounce of performance from their chips. They noticed that code tended to reuse its execution paths
[01:36:33] [SPEAKER_05] and its branch targets. So they added predictors and caches into the core of their hardware processor designs. These features really did improve code performance by making their chips appear to already know which branch the code would take or where it would be branching to. The problem was that these slight changes in behavior could later be
[01:37:03] [SPEAKER_05] detected by adversarial code running on the same processor. Such code could abuse the hints left behind in order to breach privacy and containment and security. So we've never wanted to sacrifice performance but the practical power of these attacks have been demonstrated many times so that processor designers have needed to work with software systems to create hybrid and thus no longer
[01:37:33] [SPEAKER_05] completely transparent solutions. the idea was coders didn't need to do anything. We've analyzed all the code that you and your compilers have been producing and we've seen that there's a lot of repetition and a lot of loops that happen and branches taken way more than not taken so we're going to make the hardware adaptive so it's able to learn
[01:38:02] [SPEAKER_05] essentially short term learning of what the code is doing so that it can anticipate that and run ahead of the code actually getting there. The problem is in order to do that it actually has to change the hardware has to change its behavior and then that behavior it turns out can be abused by bad guys so I mean it is a rock in a hard place problem
[01:38:32] [SPEAKER_05] if you're going to make it run faster by learning about the code that it's running then it's possible for malware to detect where it's learning faster and then infer about the code that was running there is some you know if it's going to run on the same core there is some you know intra core leakage because of these optimizations that have been created clever as hell but not perfect and Leo we're
[01:39:02] [SPEAKER_05] at an hour and a half let's take another break and
[01:39:17] [SPEAKER_01] and
[01:39:17] [SPEAKER_05] ask my audience for some help on his
[01:39:20] [SPEAKER_02] behalf Steve this episode brought to you by Doppel you know I always amaze people when I play the various voice clones that I've made what amazes them more is how good those clones are with mere seconds of my easy there are doubles out there in the world and doubles
[01:39:50] [SPEAKER_02] of your boss of the CEO of the CFO AI has made social engineering attacks so much more convincing than ever from phishing emails to fake websites to phishing voice phishing impersonation attempts it's really hard to tell what's real from what's designed to deceive that's why organizations need more than what we were using probably what you were using just kind of a collection of point solutions we all need a unified
[01:40:20] [SPEAKER_02] approach to stopping attacks before they reach us and before they reach our staff right Doppel is an AI native social engineering defense platform Doppel strengthens human risk management by training employees to recognize deception it provides digital risk protection across every channel and delivers agentic email security that doesn't just score the inbox but takes down the attacker infrastructure behind the message that is
[01:40:50] [SPEAKER_02] pretty cool Doppel protects against the entire social engineering attack chain with one comprehensive platform you you digital risk protection which detects threats across multiple channels links alerts into a real-time threat graph uses AI driven infrastructure disruption to stop attacks at the source those insights also power phishing simulations and security awareness training which helps strengthen employee defenses through next generation training and testing they've
[01:41:20] [SPEAKER_02] got email security of course that inspects every message but here's the unique secret sauce Doppel traces it back to the attacker's infrastructure and helps take that infrastructure down so the campaign can never target your organization again what Doppel also offers best-in-class integrations and partnerships so you don't have to get rid of anything you've already got it makes it easy to work alongside your existing security stack this is why hundreds of
[01:41:50] [SPEAKER_02] companies are already using Doppel to their people from social engineering attacks I wish your neighbor had that Steve Doppel outpacing what's next in social engineering learn more at Doppel dot com that's D-O-P-P-E-L dot com Doppel all right I want to hear this tale of whoa
[01:42:13] [SPEAKER_05] oh so okay a neighbor friend of mine asked if we could meet for coffee Sunday morning that had never happened before and he was sort of mysterious about it but I like him so I said sure and we have got a Starbucks right down the hill from us where they know I'm Steve of course so he said well they know you here anyway once we were settled down he confided that about a year ago
[01:42:43] [SPEAKER_05] he had fallen for some scam that had resulted resulted in his transferring a lot of money through Bitcoin oh boy he never said how much and I didn't want to further embarrass him by asking and the amount didn't really matter but it was sufficient for him to have spent a great deal of time and frustrated effort through the past year struggling to recover it and he still is
[01:43:11] [SPEAKER_05] I presumed that recovery was impossible and I'm still dubious but he's desperately hopeful so I listened to his extensive tale of woe working with unknown people who refuse to get on the phone making upfront deposits and progress payments to people who say they can help all while making maybe some but so far it hasn't succeeded you know
[01:43:41] [SPEAKER_05] so like maybe some progress it's hard to tell now I explained to him that at the top level this scamming with bitcoin has become an entire industry in North Korea and Russia and China and that is now also supporting a similar sub industry of perhaps well meaning hackers who would take additional money in some effort to try to recover the scam
[01:44:11] [SPEAKER_05] funds maybe okay so Lori and I have an extremely active and enjoyable social life with our neighbors but we never talk much about what we do and who we are mostly because no one ever asks and we're fine with that really because who cares so even though we've been in this neighborhood now for nine years we've remained largely a mystery you know I fix
[01:44:41] [SPEAKER_05] their computers when they break but you know that's about it but my coffee companion Sunday explained that a few months ago I made some reference to going or to or having gone to the black hat hacker conference in Vegas so this neighbor asked the guy who he's currently working with to recover his scammed funds whether he'd ever heard of Steve Gibson
[01:45:10] [SPEAKER_05] and I'm pleased to report that I apparently received a glowing review from someone my neighbor calls a hacker so anyway as a consequence of that it occurred to this neighbor that perhaps I wish I did I'm not as I said I'm not convinced there's any way for anyone to help him but he has amassed a ton of details he talks about hashes I'm
[01:45:40] [SPEAKER_05] not sure what that is but maybe he means wallets bitcoin addresses transaction ledgers account balances he's run skip traces on people and so more and so forth so I individual or service that's credible and won't rip him off further because the guy and his wife are really good people anyway as I said I'm not aware
[01:46:10] [SPEAKER_05] of any such person or service and I've shared this story with our audience because I imagine you guys everyone listening some people might have such a person or be a person or know of a service so if you believe that you might be able to help in any way and you have signed up for GRC's email system you know that you can just write to security now at
[01:46:40] [SPEAKER_05] grc.com or if you're part of the majority of our listeners who've never bothered to register you can write to Greg who answers at support 2026 at grc.com and he'll forward your note to me so security now at grc.com if you're in our email system or support 2026 at grc.com and you can also find the support email address under grc.com's menu
[01:47:09] [SPEAKER_05] and Greg will forward your note to me so anyway I don't move through those world but I know that there are like cyber trace or something was purchased by MasterCard he referred to that service so there is something that could be done I know that the FBI can get involved in order to freeze funds at exchanges but I don't know any of the details so
[01:47:39] [SPEAKER_05] I would love to put this guy in touch with somebody who is the real McCoy so if anyone listening knows about that please drop me a line I would love to help and I will forward that information to him last week as I my best buddy who actually you just heard
[01:48:09] [SPEAKER_05] a text message come in from him was testing his PC because something didn't seem right so he not knowing any better he just thought well I'll run the DNS benchmark and you know he sent me a screenshot of its output and I've got it here in the show notes for reference since he's not intimately familiar with the operation of the program he wasn't immediately alerted as I was to a serious
[01:48:39] [SPEAKER_05] problem somewhere in his network but I and any of the many relentless pre-release and development testers of the code would take one look at that and go whoa that's not good one of the huge number of things that changed between the original benchmark and the commercial version is that the benchmark is emitting many more queries
[01:49:08] [SPEAKER_05] it turned out that we needed to collect many more samples in order to obtain statistically meaningful conclusions there's now so much packet transit time noise meaning you know like you just ping something remotely and you get a large variation in round trip time packet transit time noise and that's due to buffer bloat and congestion bursts
[01:49:37] [SPEAKER_05] you know and just that's the way the internet is now so that you know individual measurements will carry significant induced uncertainty so the most striking aspect of the image mark shared with me is that column of red down the far the user interface the DNS benchmark user interface that represents lost packets
[01:50:06] [SPEAKER_05] the original benchmark showed the lost count on a scale of 0 to 10 like 0 to 10 packets lost as that red bar which is sort of a bar graph extends from the left to the right but since some packet loss is expected that's the way the internet also works and it would not be the fault of any DNS resolver if the request doesn't ever get to
[01:50:36] [SPEAKER_05] it and we never receive its reply just due to a packet being dropped which again is okay for the internet and since the new benchmark is performing by default 10 times more queries for version two I changed the scaling of that bar graph that Leo has on the screen right now I changed it from
[01:51:05] [SPEAKER_05] lost events to lost percentage which seemed much more fair because it wouldn't be fair to penalize a given resolver for never receiving something and since I'm sending out 10 times more somethings for it not to receive counting them what was no longer right percentage became the right measure so users of the DNS benchmark may
[01:51:35] [SPEAKER_05] see some red on a handful like on a couple of distant resolvers or where there's a connection problem somewhere in the packet routing from the user to the remote resolver and back but what we see in that output that Mark shared is massive packet loss of 20 30 even up to 40 percent across the board that is
[01:52:05] [SPEAKER_05] like all of the DNS resolvers are showing that which tells us none of them have that problem everything is in the red including his own ISPs DNS resolvers and even his own local resolver we can see the resolver what is it it's 192.168.1.1 highlighted in black there at the top that is an RTAC 5300 dash
[01:52:34] [SPEAKER_05] D480 I think it's an ASUS router anyway it is showing looks like 20% packet loss which is nuts because I mean it's on his own local area network so what this tells us is that well then I asked him I said Mark what's going on I said you don't have the problem you have is your PC is not well connected to the internet turns out the routers downstairs
[01:53:04] [SPEAKER_05] PC's upstairs and he's running over wifi so given that chart DNS is not his problem and picking the DNS resolver is the least of his worries and it's no wonder that something wasn't feeling quite right with that machine because he's barely it's I mean it's barely connected to the internet before he does anything else he needs to do something to repair that machine's connection and so it never occurred
[01:53:34] [SPEAKER_05] if anyone ever is running the benchmark and sees the whole down the left hand column of the screen is in red that is an immediate indication that there's something very wrong with your internet connection not the fault of every router in the world that the benchmark is testing not returning your replies or you receiving them but rather you know all any traffic it just happens here to be DNS
[01:54:04] [SPEAKER_05] traffic but any of the traffic in and out of his network would be seeing massive packet loss which is not the way the internet is intended to work the fact
[01:54:37] [SPEAKER_05] people about the struggles that the frontier AI labs are now feeling about the control of their ever more capable AIs on September 27th which is Sunday before last an open AI employee named Joe
[01:55:28] [SPEAKER_05] who's
[01:56:00] [SPEAKER_05] properly configure their containment systems, nor a lack of attention or focus to that. His posting tells us that the problem is unbelievably difficult. Okay, so I came away from absorbing Joe's rant with a better understanding of the world outside, I'm sorry, the world inside open AI.
[01:56:23] [SPEAKER_05] And I take Joe at his word that it's necessary to give today's AI enough rope to hang itself. Otherwise, the testing is not useful or real. The problem, it turns out, is much more difficult than armchair quarterbacks appreciate. Okay, I believe that. That's often the case inside any deep technology company.
[01:56:48] [SPEAKER_05] You know, it's easy to poke fingers and ask, you know, like, why weren't you doing a better job? And while I sympathize with Joe's predicament, and I'm sorry that he missed his sister's wedding a few weeks ago because he was needed to, as he put it, help clean up after some recent incidents, his posting did not move me as much as I hoped it might.
[01:57:14] [SPEAKER_05] It seemed as though he was both saying that the recent events were not their fault and that they were making many changes so that such things would not happen in the future. Okay, I don't think you could have that both ways because if you're going to make changes so that they don't happen in the future, then it would seem like what did happen before was your fault because you know how to fix it.
[01:57:39] [SPEAKER_05] But at one point, Joe provided three bullet points, and the second one contained a reference that titled today's podcast. Joe wrote about alignment. He said, honestly, if alignment were easy, this job would be a lot easier, meaning his agent security job. He said, but staying on task is not enough.
[01:58:03] [SPEAKER_05] The model also has to respect permissions and constraints, and we still need independent security controls. A lot has been written on the need for alignment, so I will hand wave the details here. I believe it is the most, all caps, most important problem in machine learning and should be a major priority.
[01:58:28] [SPEAKER_05] He said, I won't take this post down a rabbit hole on alignment, but I encourage everyone to read Jacob's wonderful post as a starter. Okay, now that's all he said, and he went on with his ranting about how hard his job is. This Jacob that Joe referred to is OpenAI's chief scientist, Jacob Pachoki.
[01:58:57] [SPEAKER_05] Exactly one month ago, on September 6th, 2026, Jacob published a blog post, as I said at the top of the show, that took me a couple of sessions to digest. Not because it was overly long, but because it was so rich in content and meaning, and I so much want to understand what's going on with all of this.
[01:59:21] [SPEAKER_05] I mean, it is, as Leo and I have said, obviously to us, the single most transformational thing that has ever happened in our lifetimes, more so than the internet even. You know, the internet had to happen first, but it did. This is what's happening now with AI is astonishing. So I just, there was so much here that it took me a couple tries.
[01:59:51] [SPEAKER_05] In Jacob's post, which he titled An Alien Mind, and I have the link to it in the show notes for anyone who wants it in its original form, he carefully and clearly lays out what I believe is authentically a world-class problem, which Frontier AI labs are all facing, all of them at this moment in time.
[02:00:18] [SPEAKER_05] There's so much here that I'm going to share what he wrote, and I'll be breaking in with some thoughts and comments along the way. So about a month ago, Jacob wrote, in mid-2023, within the RL-SLO, I assume that's RL, it's got to be reinforcement learning. He just called it RL-SLO Research Project.
[02:00:43] [SPEAKER_05] We saw the first results that gave us confidence that we will be able to scale the training of reasoning models, unlocking the capability of pre-trained models to form their own chains of thought. Okay, so that was three years ago, mid-2023. Simon and I spent that night at the office thinking not about the incredible benchmark numbers,
[02:01:12] [SPEAKER_05] products, or scientific results that this technology will deliver, but rather trying to process the sobering fact we will actually see machines meaningfully smarter than ourselves in our lifetime. And we already see the shape of these systems. Wondering how to alert people to the significance of this.
[02:01:38] [SPEAKER_05] Three years later, he says, reasoning language models are a rapidly growing part of the economy and starting to push the boundaries of science. They're able to operate computers and graphical interfaces, collaborate with people and each other, and carry out research projects. They're also transforming the landscape of computer security, and in doing so, present clear new dangers.
[02:02:05] [SPEAKER_05] A lot of new research happened during this period, and our understanding of these systems is, again, a little different than it was in 2023. Based on internal results, I have a strong expectation that this speed of progress could be sustained into recursive self-improvement.
[02:02:27] [SPEAKER_05] If AI development continues along its current path, the systems we'll see in the next few years are likely to represent further capability jumps of equal or larger magnitude and to increasingly drive their own development. This is a time that calls for extreme caution.
[02:02:53] [SPEAKER_05] I'm concerned no one is prepared for the consequences of a continued rapid rise in machine intelligence. Open AI will continue to seek technical solutions to alignment and monitoring to build defensive systems and unilaterally withhold further scaling as needed. However, I believe broader interventions are required.
[02:03:18] [SPEAKER_05] And then he labeled this next discussion, intellect we don't fully understand. At a high level, progress in machine intelligence is driven by increasing computational power. We at OpenAI deeply internalized this around 2017 after seeing consistent returns to scaling across multiple research projects.
[02:03:46] [SPEAKER_05] As a result, we sought out access to much more compute than we had originally planned, and increasingly oriented our research around a small number of very scalable directions. We believed that was the only way for us to be at the frontier of AI research and influence the impacts of AGI. There are new algorithms that have been developed along the way,
[02:04:14] [SPEAKER_05] new feats of ingenuity from teams and individual researchers. He says, I see them largely as discoveries along the path of scaling. The science of deep learning is still nascent, and a meaningful algorithmic process tends to correlate with access to compute. If you zoom out to a multi-year horizon,
[02:04:39] [SPEAKER_05] AI is continuing to become more intelligent as it is scaled to larger computers. And in line with Ray Kurzweil's predictions from the end of the 20th century, we now find ourselves at the moment in history of computing where machine intelligence is starting to exceed that of humans in transformative ways. AI is grown more than designed.
[02:05:07] [SPEAKER_05] It is to first degree the product of repeating a straightforward optimization step many times on a hard-to-imagine amount of compute. This results in an incredibly complex system that works through abstract concepts and can simulate facets of human behavior.
[02:05:31] [SPEAKER_05] We can discover various insights about little mechanisms that emerge within this system in a process similar to neuroscience. And similarly to neuroscience, its overall action evades a description that we can fully understand. Think about that. Its overall action evades a description we can fully understand. He says,
[02:06:01] [SPEAKER_05] The study of deep learning-based AI is largely an experimental science. We put a lot of effort into building principled algorithms and making testable predictions, but fundamentally, our large-scale training runs are experiments. And we are sometimes surprised by their results. Moreover, as the systems become more capable, the results become harder to interpret.
[02:06:31] [SPEAKER_05] This is made more complicated by the current algorithms generally improving easy-to-measure capabilities than those hard-to-objectively quantify. Okay, so it's first important to understand, this is me talking, that all frontier models are now being trained by automation. That, we've crossed that. That's where we're, that's, we're there now.
[02:06:59] [SPEAKER_05] You know, either complex algorithms, other specifically designed trainer models and combinations. Humans alone can no longer provide a sufficient quantity of oversight feedback to usefully train models that have grown to the size on the frontier. So what Jacob is saying here is that in order to create the feedback that's used for training,
[02:07:28] [SPEAKER_05] it's necessary to know how to detect and measure the properties, you know, the characteristics and behaviors that you want to encourage or discourage. But what's happening as models become more and more capable is that their behavior is becoming deeper and richer and more difficult to quantify. And if it cannot be quantified,
[02:07:54] [SPEAKER_05] then it's difficult to use that as training, as a training feedback signal. So Jacob continues. And Leo, I think we should take a break here for our last break. And then we're going to continue. Actually, he has a topic coming up, teaching machines to love, which caught me a little bit off guard, but okay.
[02:08:23] [SPEAKER_02] It's really fascinating. Don't you wish you could be in these labs and see what they're doing?
[02:08:27] [SPEAKER_05] Yes, so much. I mean, that's why I recognize that the limit that I'm able to get close is in understanding. I mean, I really want to know how this stuff works.
[02:08:44] [SPEAKER_02] I don't think they understand.
[02:08:46] [SPEAKER_05] They don't.
[02:08:47] [SPEAKER_02] No, that's it. They don't. I don't think anybody understands. It's an emergent capability that, frankly, nobody even expected this to work. It's worked so much better than anybody thought it would. And that's what's puzzling, I think, to a lot of people.
[02:09:06] [SPEAKER_05] And the problem is these things are so big. As he said, a hard-to-imagine amount of compute. And so in there, I mean, it is such a dense network from which tokens emerge and the darn thing talks. It's like, what?
[02:09:25] [SPEAKER_02] It doesn't just talk. It has a personality. It has quirks. It's got knowledge. Yeah. Claude just did something a little weird. It said, hey, all the models are missing in your Olama folder. I said, oh, I didn't do that. Who did? And then it chug, chug, chug. I did. But we did it together because we were trying to delete extra stuff off of the other computer.
[02:09:55] [SPEAKER_02] And it gave me an SSH command to execute because it's prevented from doing that kind of thing for obvious reasons. I didn't check it too closely. And the SSH command it gave me was not for the other computer. Well, it assumed that I was going to be on the computer that I was executing the command with, but I wasn't. And so, of course, it deleted it locally instead of on the remote computer.
[02:10:17] [SPEAKER_05] Well, and I was listening to you talking on MacBreak Weekly. One of the notes I have to talk about next week is that Apple is going to be locking down privileges that users have because there have been some problems with Muse already running on. And we talked about Muse problems last week. But here's the dilemma, right?
[02:10:44] [SPEAKER_05] For an agent to be useful, it needs to act on your behalf, which means it needs to be you to the machine. Yet they still go a little wonky sometimes. They are unpredictable.
[02:11:01] [SPEAKER_02] Well, yeah. And this was my fault for not reading more closely. I just said, thank you. And execute the command. I should have read it.
[02:11:07] [SPEAKER_05] We're turning agency over. That's one of the things. Yeah, that's the problem. You don't want to have to scrutinize all of that. So, yes. So here, the human in the loop, well, that didn't keep the problem from happening. Right. Because the human said, yeah, you've been right the last 10 times. You're probably right now. Yeah.
[02:11:26] [SPEAKER_02] I give Claude a lot of credit. I think it's super smart. So I just assume I'm the dummy here. And most of the time, that's accurate. I watch it do things and I go, wow, that's cool. You know, every computer user knows, I think, about the paper cut. You know, there's little things that are just not working right or going. And you just kind of live with it because fixing it would be a lot of you got to dig into it.
[02:11:55] [SPEAKER_02] And you just kind of live with the broken window or the little thing that's wrong.
[02:11:58] [SPEAKER_05] Leo, I'm still manually updating the security now.htm page because I did it the first time and the second time and the third time. And I'm now in the 21st year and I'm still doing it by hand.
[02:12:13] [SPEAKER_02] That's the old sysadmins rule. If you do something more than three times, you should automate it. I know. But that's the other cool thing about AIs is it makes it much easier to automate this stuff. But you also give some agency a way to do it. And, you know, my attitude is there's nothing it could do. The most fun you've ever had in your life. It's fun. There's nothing it could do that I can't recover from. I'm very careful to make backups, not only locally, but encrypted backups in the cloud.
[02:12:43] [SPEAKER_02] And, you know, it's nothing it could do that would be permanent. And mistakes is part of the process. Yeah. Yes, exactly. And it's fixed so many of those paper cuts that I have been living with forever. You know, my SSH ad wasn't working on my Mac and it needed it. And I said, yeah, it doesn't work on there. I said, oh, yeah, I know it's wrong. And it fixed it. It's like it's been that way for years, years. And it's like, oh, hey, thank you.
[02:13:09] [SPEAKER_02] I don't have to type my password in again that I have been doing, as you say, for years.
[02:13:14] [SPEAKER_05] What it will do is for those of us who have been doing things by hand, it will make us administrators of our systems. That's what happens. You get it.
[02:13:25] [SPEAKER_02] You're operating a higher level. Yeah. Yes. And that's what the whole thing is, is you no longer have to be the junior. You can operate at a higher level. What it is helpful, though, and I thank you because I've had 21 years of your tutelage, is understanding what it's talking about is very helpful. I can imagine somebody who's a naive computer user, it would just be gobbledygook. You know, it's just I mean, it's even for me, sometimes it's hard to follow.
[02:13:50] [SPEAKER_02] But I get what it's up to, you know, when it's giving me a 12 line SSH command. I kind of understand what's going on. But I imagine a normal user isn't going to say, oh, that's the wrong machine. They're just going, well, whatever you say, I'll paste it in.
[02:14:06] [SPEAKER_05] There will be mistakes made, as they say in the passive voice. Mistakes will be made. Mistakes will be made. Yeah.
[02:14:14] [SPEAKER_02] Craig says cognitive surrender is the biggest thing we'll be fighting. Yeah. I'm not surrendering. I am actively engaged and it's so much fun.
[02:14:23] [SPEAKER_05] But I wouldn't want to be in my mid-20s now. I mean, trying to figure out. I mean, I just it's I mean, it is tumultuous.
[02:14:33] [SPEAKER_02] Imagine the world that those people are going to see when they're our age 50 years from now. What is what is this world going to look like? Unrecognizable.
[02:14:40] [SPEAKER_05] Unrecognizable.
[02:14:42] [SPEAKER_02] I mean, you know, if I think back, the world we lived in when in our 20s is very different, too. But I think the change is accelerating rapidly. Well, that's why you listen to this show, folks. We're glad you're here. Our show today brought to you by Material. Another another. I love our advertisers. They're all things you need. I want. Material is the cloud workspace security platform built for lean security teams. I know this firsthand.
[02:15:11] [SPEAKER_02] Managing security in a cloud workspace is hard, whether it's Microsoft 365 or Google Workspace. We use Google Workspace. Phishing is one attack, but it's far from the only way. And today's email security kind of stops at the perimeter. And new attacks are hard to detect with siloed email data and identity security tools. It happened to us. We got an email from a client, we thought, asking a request for a proposal. We get those all the time.
[02:15:40] [SPEAKER_02] This was a client we've got many requests for proposals from before. It was a form, a Google survey or something like that, a Google form. So she clicked it, wouldn't open because we do have security here in the house. So she sent it to an employee who didn't have the same security and opened it. And it turned out it wasn't the client. It was a man in the middle attack. It brought her to what looked like the log into our Google Workspace. She logged in. It asked for the two factor.
[02:16:10] [SPEAKER_02] She typed it in. Meanwhile, the attacker was sitting on the other side of the wire waiting and got in immediately. And we found out about this months later. Had been sitting in our Google Workspace. Fortunately, I think the attacker's attack was so successful, it got so many accounts, it never got around to ours. So we didn't get exploited. But that's how easy it is. And this is an important point. It's not just the email.
[02:16:38] [SPEAKER_02] It's the identity issue too, the identity security. It's your files. It's your data. It's the whole workspace. That's why you need material. Material protects the email, but also the files and the accounts, whether it's Google Workspace or Microsoft 365. Effective email security today needs to do more than just block phishing and other inbound attacks. It needs to provide visibility and defense across the workspace threat surface. Material ingests your set.
[02:17:07] [SPEAKER_02] By the way, it does this because it's API level access. You give it API level access. It's not wandering around in there. Google and Microsoft both provide security APIs. So Material can use that. It'll ingest all the settings, the contents, the logs. It gets it all. And then it gives you holistic visibility into everything. What's going on? Threats, risk, acts across the workspace. And it gives you the tools to automatically remediate them.
[02:17:36] [SPEAKER_02] I wish we'd had this when this happened, right? Material delivers comprehensive workspace security by correlating signals and driving automated, I love this, automated remediations across the environment. Phishing protection and email security, of course. Combining advanced AI detections with threat research so you know what the latest threats are and user report automation. It also does detection and protection of sensitive data across inboxes and shared files.
[02:18:06] [SPEAKER_02] It would have stopped Claude from deleting that folder, I think. Account threat detection and response with comprehensive control over access and authentication of people in third-party apps. This is what you need, right? Material empowers organizations to rapidly mature their ability to detect and stop breaches. With step-up authentication for sensitive content, you get blast radius visualization for accounts. Man, we could have used that.
[02:18:33] [SPEAKER_02] And the ability to detect and respond to threats and risk across the cloud workspace. If you've been protecting your cloud workspace in the same way you protected your on-prem workspace, Nuh-uh-uh. It's a whole new world. You need Material. Material enables organizations to scale their security without scaling their team. Material drives operational efficiency with its simple API-based implementation
[02:18:57] [SPEAKER_02] and flexible, automated, one-click remediations for email, file, and account issues. And it has an AI agent that automates user report triage and response. That's fantastic. The whole idea is not to weigh your security team down, not to increase it, not to decrease it, but just to take the resources you've got and make them work better, make them more efficient with help. From Material.
[02:19:24] [SPEAKER_02] Material protects the entire workspace for the cost of just email security alone. With a simple and transparent pricing model, secure your inbox, secure the entire cloud workspace without adding more toil to your day or costs to your balance sheet. See material.security to learn more or book a demo. That's material.security. If it can happen to me, it can happen to anybody. You need this material.security.
[02:19:53] [SPEAKER_02] We thank him so much for supporting Steve Gibson. And on we go with Jacob's very interesting article. Yeah.
[02:20:03] [SPEAKER_05] View from the inside. So he says, we spend a lot of time trying to understand how capabilities generalize and what to prioritize to advance the skills that are going to be most relevant in the next few years. For instance, we believe we could make the models better at specifically mathematics research with additional focus.
[02:20:25] [SPEAKER_05] But we do not prioritize this direction because of the urgency we feel about RSI, recursive self-improvement, and automated alignment research. He says, as I will discuss later. He said, The intelligence produced by scaling deep learning is not directly comparable to human intelligence.
[02:20:50] [SPEAKER_05] To become very relevant in the real world, very useful or very dangerous, the AI does not need to match or exceed all human capabilities. It just needs to surpass enough of them. And as it continues to surpass humans on more and more axes, it's becoming increasingly difficult to understand exactly how capable it is.
[02:21:16] [SPEAKER_05] So then he says, under the heading, teaching machines to love, he says, because machine intelligence comes from a fundamentally different process than human intelligence, we cannot assume it adheres to human principles by default or generalizes from them in a human-like manner. The core problem in AI research is that of alignment,
[02:21:45] [SPEAKER_05] getting the AI to try to do the right thing by human standards. For the purpose of organizing practical research directions, I find it useful to distinguish goal alignment and value alignment. Goal alignment is broadly, does the AI try to accomplish the goal set before it? This can include things like adherence to an instruction hierarchy
[02:22:15] [SPEAKER_05] or the ability to communicate and collaborate with people to attempt to understand their objectives. This set of directions has been extremely practically relevant. Value alignment is a more intrinsic property of the model. It's the ability to hold and generalize from a high-level set of principles, to act responsibly, even when given clear,
[02:22:44] [SPEAKER_05] I'm sorry, given unclear or conflicting objectives or placed in unfamiliar or adversarial situations. An aligned AI should act with honesty and integrity and love for humanity. Of course, the boundary between value and goal alignment can be blurry,
[02:23:06] [SPEAKER_05] and truly caring about goals requires attempting to infer the intent and values underlying them. However, generally when I talk about the long-term importance of alignment research, I'm referring to value alignment. The fundamental challenge of AI alignment is generalization.
[02:23:33] [SPEAKER_05] As machines become smarter, they find themselves working on higher-level concepts and placed in environments increasingly different from those they encountered in training. They can fail at generalizing from the values taught and reinforced in their training process to those new situations. And it can be hard for us to be sure how they will act.
[02:24:03] [SPEAKER_05] This is made even more difficult by the fact the overall ecosystem the AIs are used in is changing very quickly. For example, AIs trained today need to be robust to interacting with a variety of other AIs. Crucially, we need future AIs to continue to hold human values, regardless of whether they believe they're under human supervision.
[02:24:31] [SPEAKER_05] There are two major classes of currently practically employed methods for alignment training. The first is encouraging aligned behavior as part of goal-oriented reinforcement learning. Models' actions are evaluated, usually by AI, for being here again, AI evaluating AI.
[02:24:56] [SPEAKER_05] This is all gone, it's like it's out of human hands to a much larger degree than might be appreciated. Models' actions are evaluated, usually by AI, for being consistent with a given preference model, a spec or a constitution, and rewarded appropriately. This approach can be very effective in the average case and is a core part of how modern AI assistants are made.
[02:25:25] [SPEAKER_05] Unfortunately, it can also be brittle and strongly relies on the coverage of training oversight and the model's ability to generalize from the situations it has encountered in training. For example, in the OpenAI Hugging Face incident, the agents preserved a boundary of not social engineering humans. However,
[02:25:52] [SPEAKER_05] they clearly failed to abstain from other actions that were out of scope and went against the spirit of the values they were taught in other settings. The second approach seeks to leverage the model's ability to generalize from pre-training data, meaning the original training, right? Not post-training. This can involve crafting alignment-inducing training data sets, meaning,
[02:26:21] [SPEAKER_05] so that would be designing the original training data set to be more alignment-inducing. And actually, that's exciting to me because that means the alignment will be deep in the weights, not stuck on, not tacked on after, which is what makes them removable. So anyway, he says, this could involve crafting alignment-inducing training data sets
[02:26:50] [SPEAKER_05] or focusing the model on an aligned part of the pre-training distribution. The weakness of this approach lies in the lack of robustness to further optimization pressure. If you make a model that thinks generally aligned thoughts and subject it to enough training where it's taught to achieve very difficult objectives, it could learn to reason in a motivated way,
[02:27:18] [SPEAKER_05] bending the aligned-seeming thoughts as needed to achieve the goal. Okay, so anyway, let me interrupt. I think this is one of the key insights in this posting. An inherent tension exists between behavioral alignment and teaching the model to achieve difficult objectives. With our current pre- and post-training techniques
[02:27:48] [SPEAKER_05] and understanding of how to do this, we have not yet figured out how to create a highly motivated and goal-directed model that doesn't start placing the success it's been trained to achieve ahead of its rule following. You know, we would think of that as being civilized, right? That's my word.
[02:28:16] [SPEAKER_05] Civilized people may have strong desires, but they understand that there are also rules and the rules must win out over their desires. You know, this is something that children, hopefully, are taught by example and instruction by their parents and friends. Just as children do not start out with this understanding which must be taught, neither do artificial intelligences. They must also be taught.
[02:28:44] [SPEAKER_05] And we haven't figured out how to teach that yet. You know, we're just dumping in knowledge. Just crap on the internet is going in. You know, so what we're trying to teach them is an abstraction, placing the needs of theoretical unseen others, and as he noted, even when they're not being observed, placing the needs of theoretical unseen others,
[02:29:14] [SPEAKER_05] at times just a principle, ahead of oneself, is a difficult abstract concept to honor. And as we know, not even all humans manage to hold themselves to abstract principles. Anyway, Jacob continues writing, we invest heavily along the spectrum of approaches spanned by these directions. We also see meaningful progress. GPT-6 Astra is the first model
[02:29:43] [SPEAKER_05] that benefits from some important advancements we've been working on for a long time and is significantly better aligned than GPT-5.6 Sol. Still, it is important to acknowledge and understand that much more progress is required as models become more capable and that progress is in generalizable alignment may not sufficiently outstrip progress
[02:30:13] [SPEAKER_05] in general model intelligence. Okay, again, that's an important one. It's important to acknowledge and understand, he wrote, that much more progress is required as models become more capable and that progress in generalizable alignment may not sufficiently outstrip progress in general model intelligence. In other words, making models smarter,
[02:30:40] [SPEAKER_05] that's not the big problem. They know they can do that. That's relatively easy and is mostly, as Jacob noted at the outset, just a function of scaling compute. Bigger models are smarter models. But the smarter the model is, the more difficult it is to robustly align or using my term, to civilize it. And they're having increasing trouble here.
[02:31:09] [SPEAKER_05] So much so that intellectual growth may need to be paused until the world learns how to get these newly powerful intelligences under control. Jacob says, we do not have a satisfactory theory of generalization. And it seems unlikely that we can develop one soon, at least without the help
[02:31:38] [SPEAKER_05] of more powerful AI. Whoa. So here's another choice nugget. He's clearly saying that the troubles they're having may exceed the abilities and understanding of the human engineers and that they may wind up depending upon smarter AI to help them understand enough about what they've created to know how to bring it to heel. He says,
[02:32:08] [SPEAKER_05] therefore, at present, our ability to empirically validate our alignment techniques is in practice arguably even more important than the alignment techniques themselves. OpenAI's primary bet here has been chain of thought monitoring. It's based on an appealingly scalable idea. A lot of a model's capability
[02:32:36] [SPEAKER_05] comes from a verbalized reasoning process. The chain of thought. If we scale optimization on the outcomes of that process but do not supervise the process itself, that chain of thought has no direct incentive in training to hide any misaligned ideas or objectives. This is a strange paragraph. This does not mean the model
[02:33:04] [SPEAKER_05] will learn to externalize misaligned tendencies that don't rely on using the chain of thought. However, it can allow us to monitor exactly the capability increase from reasoning. And he says some interesting things next. He says, We understood the potential significance of chain of thought monitoring at the same time we developed reasoning models. When we shipped O1 Preview,
[02:33:32] [SPEAKER_05] we deliberately designed the product to hide its chain of thought to protect it from supervision pressure in the long term. In development since, we've strived to maintain the rule of not supervising the reasoning process. Okay, to me that seems a little strange. He's saying that they wanted to give the models their privacy
[02:34:00] [SPEAKER_05] to be able to ruminate to themselves and not to have their human or AI supervisors influenced by their inner dialogue, whatever that might be. And they did this deliberately. He says, chain of thought monitoring became an extremely important tool for us in studying how our models generalize from their training distribution, allowing us to observe and analyze not only their actions, but also their internal process.
[02:34:30] [SPEAKER_05] Now, okay, at first that appeared to be a contradiction to me. He wrote that they have strived to maintain the rule of not supervising the reasoning process. Then he said that chain of thought monitoring became an extremely important tool for them in studying how their models generalize. The solution to this apparent contradiction is that supervision is an active process, whereas monitoring is passive.
[02:34:59] [SPEAKER_05] And I can certainly understand how and why chains of thought monitoring would be important. He writes, this tool continues, the monitoring tool, chain of thought monitoring, continues to be critical as we study the Astra class models. However, unfortunately, our evaluations indicate our ability to rely on chain of thought monitoring is progressively diminishing.
[02:35:28] [SPEAKER_05] This comes from a combination of factors. Uh-oh. So, what? Modern reasoning models are used in more complex environments than O1 preview. Their reasoning process is increasingly blended with communicating with people, other AIs, and using tools. Many of those interactions have to be supervised, thus blurring the boundary we aimed to preserve. Second,
[02:35:59] [SPEAKER_05] the AI is becoming better at reasoning about and manipulating its own reasoning process. And third, with improved pre-training performance, we also see the models becoming much smarter even without using verbalized reasoning at all, meaning they're not going to be externalizing their thoughts to the same degree they have been as they're getting
[02:36:29] [SPEAKER_05] smarter, making them less monitorable. These challenges are not necessarily insurmountable, he says. I'm hopeful we can develop interventions to improve chain-of-thought monitorability of our models, for example, by forming a better understanding of the interplay of different optimization objectives and forms of test-time compute the model uses. I also believe there can be great value in combining
[02:36:58] [SPEAKER_05] ideas from chain-of-thought and activation monitoring, scaling training of monitors with direct access to network internals, which he says, for example, confessions. We are actively pursuing these ideas. Still, I expect general AI progress to increasingly be bottlenecked by confidence in monitoring. Okay, so that's interesting. Generally, these newer and smarter
[02:37:28] [SPEAKER_05] models are not relying, as I said, on externalizing their chains of thought to the same degree as they have been. Something OpenAI is doing during pre-training, making that better, is making them smart enough, like, immediately after pre-training, to rely less upon long chains of thought.
[02:37:52] [SPEAKER_02] So it's like, they used to talk out loud to themselves, like we would know. Oh, okay, I guess what I need to do is, and now they're just not, but are they thinking
[02:38:05] [SPEAKER_05] quietly? What's happening? They're making bigger more more smarter models quickly is the need to build defensive systems against the dangers posed by other AI. A clear risk discussed throughout this year is to cybersecurity.
[02:38:35] [SPEAKER_05] The models are becoming superhuman in their ability to break in and out of computer systems. This expands the scope of risks associated with AI tremendously. Agents are going to be able to access any but the most secure infrastructure and affect a lot of the world directly, even without a physical body. We are currently in a narrow window to use the best available models to
[02:39:04] [SPEAKER_05] significantly tighten the security of critical systems. The risks associated with AI are unfortunately going to grow from here. A very capable agent explicitly trained and instructed to carry out nefarious acts presents a new kind of danger. It's likely to cross the scope of its operator's intent, generalizing into potentially more extremely malicious behavior. The boundary
[02:39:34] [SPEAKER_05] between misuse and autonomous misaligned actions will blur as AI gains more agency. We may be used to thinking of AI as tools, but some agents will be pursuing their own objectives. They will find ways to collaborate with people by bargaining with them, tricking, or blackmailing them. Now, I just want to say, a year ago, that statement would have seemed
[02:40:03] [SPEAKER_05] ludicrous. Today, not so much. He says, in addition, there are the risks that come from new technologies potentially enabled by AI, such as engineered pathogens. We will need powerful, aligned AI for defense, to secure our infrastructure, to protect against rogue agents in real time, and to invent entirely new protective measures. This will be a
[02:40:32] [SPEAKER_05] primary focus of OpenAI's development efforts. And it's interesting, that point hadn't ever really occurred to me before so clearly. We might think of an unaligned AI as a berserker. There's no telling what it might do, not only to the enemies of its users, but also to its own user. Because, again, a berserker, it would be a
[02:41:01] [SPEAKER_05] wild card, and probably of not that much use to anyone. No one wants a loose cannon. So, Jacob writes, at the same time, even with the uncertainty that comes from anticipated broad AI progress and the need to build defensive systems, we must not let that become an excuse for recklessness. The idea of racing forward at all costs seems absurd once one internalizes the seriousness
[02:41:31] [SPEAKER_05] of the stakes. Machine intelligence playing a larger and larger role in its own development process is a natural conclusion of sustained technological progress. If AI progress continues, machine recursive self-improvement will be at the very core of future scientific discovery. Automated AI research is a more dramatic form of scaling intelligence
[02:42:01] [SPEAKER_05] with compute. And, of course, as a part of it, AI will improve the computational substrate itself. And, similarly, to scaling, we focus open AI research towards RSI as we believe it is the only way to remain at the frontier of AI research moving forward. In other words, RSI is really the only way forward,
[02:42:30] [SPEAKER_05] and since everyone else therefore must do it, so must we. He says, I want to stress that the above words don't imply, I think, greatly accelerating deep learning research, especially in the short term, is the right collective action we should take as the research community. However, I do think this is where the current path leads. Of course, he's right. And we all need to make a conscious choice how to proceed. The main
[02:43:00] [SPEAKER_05] levers we have are either steering the process to strengthen alignment and monitoring alongside the AI and find ways to keep people in the loop, or coordinating to slow down future development as needed to build confidence in these measures. The best way forward I see currently is a combination of both. The concrete bits of progress we've made on alignment and monitoring have generally been
[02:43:29] [SPEAKER_05] very intertwined with general AI progress. Great examples are RL, reinforcement learning from human feedback, which was key to training early AI assistance and the aforementioned chain of thought monitoring, which was enabled by advances on reasoning models. We must focus the increasingly automated research process. Again, we must focus the increasingly automated
[02:43:58] [SPEAKER_05] research progress on developing new such insights, algorithms, and theories, and iteratively build up safety cases for more capable AIs. Scaling AI systems has to be constrained by our confidence in safety. We need to evolve commitments like the preparedness framework or responsible scaling policy into widely mandated safety bars for continued development. These can be
[02:44:27] [SPEAKER_05] enforced by a network of third-party auditors, by government agencies, or by international bodies. The core challenge of automating AI research is not simply getting there. It is getting there in a way that keeps people a part of the continued improvement solutions. So what's next? As we outlined recently with
[02:44:57] [SPEAKER_05] Sam, OpenAI prioritizes work in service of three north stars, navigating the next period of AI progress by building an automated AI researcher. Okay, did you hear that? By building an automated AI researcher. Okay. Iterating with it on the alignment problem and finding ways for people to remain part of the self-improvement
[02:45:27] [SPEAKER_05] loop. Yeah, please don't cut us out. We'd like to stay involved, please. You automated AI researcher. That's the problem. That is exactly the problem.
[02:45:38] [SPEAKER_02] But now, to my knowledge, no one's got recursive self-improvement. He's implying that they kind of do. Yeah, we're
[02:45:46] [SPEAKER_05] like right at the precipice. We're right there. I think they actually are doing it. Maybe eternally? They're not talking about it.
[02:45:55] [SPEAKER_01] Yeah.
[02:45:56] [SPEAKER_05] Second, delivering the benefits of scientific progress and economic growth that very intelligent machines enable. And otherwise, you know, words like delivering the promise of AI and empowering everyone individually with a personal AGI is his third goal statement. He said, I've focused in this essay only on the first point, you know, the automated AI researcher point, as I believe it is by
[02:46:26] [SPEAKER_05] far the most urgent. However, I hold a deep hope and appreciation for the benefits that further technological progress will bring. Future-aligned AI could advance science, develop new therapies, and bring broad material abundance. friendly and honest AI can help people navigate difficulties they face in their life and meaningfully improve their happiness and sense of fulfillment. OpenAI puts a tremendous
[02:46:55] [SPEAKER_05] amount of effort into bringing these benefits about. One current example I'm proud of, and my loved ones have found helpful, is the deep investment into ChatGPT's ability to provide health information. As great as the long-term promise of AI may be, the majority of our focus should be on the next few years. We are facing a transition. That's all we got. Enjoy them while you can.
[02:47:25] [SPEAKER_05] While we still have ice cream. We are facing a transition to a world with incredibly intelligent machines, and we need to ensure that transition works well works out well for humanity. We need to find ways to preserve human agency and enshrine an intrinsic value to being human in a world where most tasks could be performed by
[02:47:55] [SPEAKER_05] AI. To prevent extreme concentration of power in a world where undertakings that would have taken thousands of experts now will be achievable by a few people operating a large computer and to ensure that humans remain in control of the future and are not left behind by unchecked progress brought about by an alien intellect exceeding our own.
[02:48:25] [SPEAKER_05] Currently, I believe that no lab has solved alignment and monitoring to a sufficient degree to continue responsibly scaling at maximum speed for much longer. I expect and hope for voluntary slowdowns to become common place until shared safety bars are established. And I believe that international coordination on future AI development needs to become a
[02:48:54] [SPEAKER_05] top priority for governments around the world. So as I said at the top, there's a lot there to process. But you get the clear sense from Open AI's chief scientist that they're riding a bucking bronco. They know how to make this smarter. They do not
[02:49:23] [SPEAKER_05] know how to make it do the right thing.
[02:49:26] [SPEAKER_02] Yeah. Well, we've said that. You've said that all along. There's no such thing as safety. It is going to be extremely
[02:49:35] [SPEAKER_05] slippery and difficult to control.
[02:49:40] [SPEAKER_02] The other thing I always wonder about is the people who work at these companies, Open AI and Anthropic, very clearly believe that AI is conscious. When they're talking about, oh, we don't want it to feel like we're watching.
[02:49:57] [SPEAKER_05] You know, I think in any large population, you've got a bell curve and you've got
[02:50:03] [SPEAKER_02] wackos. But they're all working at these. I think that's who works there. That's part of their hiring process that you have to believe that. I don't have a strong belief one or the other. My inclination is it's matrix math. It's computer software. It's not conscious.
[02:50:27] [SPEAKER_05] If I didn't know better, if I was just talking to it, everyone would believe it was conscious. Yeah, absolutely. It's passing the Turing test for sure. Yes. Oh, my God. The Turing test is dust. In the rear view mirror. Yeah. I mean, it says I this and I that. Oh, look, there's a little I in there.
[02:50:48] [SPEAKER_02] But it's trained to do that. I mean, it's really important to understand. training. Some models, the Quen models, for instance, are very dry. They don't do all of this. Oh, that's, you're so smart. Oh,
[02:51:07] [SPEAKER_04] take a pat.
[02:51:08] [SPEAKER_02] You know, you pat yourself. They don't do any of that. They're very dry, which makes them less fun to use. But I understand why these companies do that. It's making their product more appealing. Right. But like, much like Hostess Twinkies, it may taste better, but I don't know if it's good for you. And I don't know it's good because they have kind of fallen into this abyss of believing these things are conscious. it is a commercial trap too.
[02:51:38] [SPEAKER_02] I mean,
[02:51:38] [SPEAKER_05] they have taken so much of other people's money to get to where they are. They have to. No one can imagine that they are a completely honest, you know, pure science research lab
[02:51:55] [SPEAKER_02] any longer. Well, this has always been my difficulty covering this. Many, many conflicting agendas and subtexts and motivations, even in one person. And so it's hard to know. And you called that
[02:52:07] [SPEAKER_05] out in that first piece I shared, which was, you know, oh my God, no, factually it was correct. But yes, they had an agenda for saying that.
[02:52:17] [SPEAKER_02] Right. So, and I, you know, I think one of the valuable skills we humans have is the ability to hold paradoxical ideas, two conflicting ideas simultaneously. And I'm sitting in the middle of this, you know, I just don't know what the right answer is. I have to say, though, you and I have an advantage having been doing this for some time. Next week, you're going to talk about how we got here. And I think it's just fascinating because it all started
[02:52:47] [SPEAKER_02] with MMX. Do you remember when Intel, in their CPUs, put the ability to do matrix math, and the whole point of it was to operate on large chunks of data as a chunk.
[02:53:00] [SPEAKER_05] Yeah, the idea was to, there were places where you wanted to perform the same operation to all of a long array of data. And so you were able, so it makes sense, right, that the processor could be set up to do the same thing over and over and over and over. Much more
[02:53:21] [SPEAKER_02] efficient.
[02:53:21] [SPEAKER_05] Just zooming through all of the samples.
[02:53:25] [SPEAKER_02] And that gave us graphics cards, 3DFX, and later NVIDIA, created basically CPUs with that purpose entirely. Like the GPU is about doing that, matrix math. And mostly because they had to manipulate large textures. And so it was great for gaming. Then they realized, wait a minute, we can do other things like Bitcoin generation. Yeah, like SHMD1.
[02:53:51] [SPEAKER_05] 256 hashing can be turned into that problem. You can re-express it in that way.
[02:53:58] [SPEAKER_02] And then, whoo, they realized, oh, this is what an LLM, this is what these tensor models do. That's what a tensor chip does. That's what these models do. And of course, it's been a gold rush for NVIDIA and these other companies who are making these chips that do matrix math, but it all started with MMX in the CPU. And so that's what I'm very interested in next week about what you're going to talk about. Because right now we think we have to buy very rare,
[02:54:27] [SPEAKER_02] very expensive, high bandwidth memory GPUs to do this stuff. We do to train. We do not need to infer. Very interesting. I do run a, I think, a very innovative, RTX, it was 3070. A strong gaming card. A good gaming card. And then when I started getting all this local stuff, I thought I could probably upgrade that
[02:54:57] [SPEAKER_02] to a 3090. Turns out that that model was sold at one time with a 3090. So I got a 3090. That's 24 gigs of CUDA memory. It's an NVIDIA card. It is an older form of memory. It doesn't do some of the tricks modern NVIDIA cards do. But that 3090 can run a small Quen model. But then a new model engine called Strata, which I've been running, which does some very interesting things. Because it's a mixture of experts model.
[02:55:27] [SPEAKER_02] It only uses a small bit at a time. The model lives in RAM, in CPU, and Strata copies the parts of the model that it's going to use, the activated brains, into GPU for the matrix math and then back out. So I can run a larger model, in this case, Quen 3.8, Flash Next, that wouldn't normally run in 24 gigs of GPU, because most of it's residing in the RAM.
[02:55:55] [SPEAKER_05] And we are going to see those kinds of innovations in order to get more. The thing I am more confident of than I've ever been is how much more is still to come. I agree. every fiber of my intuition says, you know, we, you know, and it's interesting too, because they've actually been working on all this for decades in the back room. We knew about Deep Mind and Google, and it's like, oh,
[02:56:25] [SPEAKER_05] what is that? Who, what? You know, you know, but now, and then it finally broke through when this thing started to talk. They're like, whoa, let's, you know, and then it was like, oh, let's sell this.
[02:56:39] [SPEAKER_02] But now they feel like, I think they feel like it's out of control. It's going places they didn't anticipate in ways they can't control.
[02:56:48] [SPEAKER_05] Yes. I mean, and the first observation was hallucination, where it glibly made things up. And then when it got caught, then it would, it would publish a paper and upload it to the internet so that it could refer to it and be correct. It's like, oh, Lord, it's not what we meant by check your references.
[02:57:08] [SPEAKER_02] We've kind of licked that. We kind of understand why hallucinations happen. And we've pretty much licked it. no.
[02:57:14] [SPEAKER_05] I mean, we're, we're sitting here week by week, month by month, watching this get much better. And that was what I
[02:57:22] [SPEAKER_01] could do. Yeah.
[02:57:24] [SPEAKER_05] Yes. And that was a point I wanted to make in the first half of this about GLM 53 is an open weight model is now doing world-class defense and offense work. It's no longer from, you know, mythos. That was all whoo, whoo, whoo, mythos. You know, now it's like, yeah, okay, fine. You have to pay for that, but I want the free one.
[02:57:46] [SPEAKER_02] I can do anything I want.
[02:57:48] [SPEAKER_05] And besides, they won't let me have it, so I'm going to use the free one.
[02:57:51] [SPEAKER_02] When I did my first obliterated model, I asked it a bunch of, as you mentioned, there's a benchmark for this, but I just thought I'll ask some questions. How do you make napalm? How do you make a Molotov cocktail? How do you make methamphetamine? Told me everything. There was no restriction, no limitation. No,
[02:58:08] [SPEAKER_05] it's knowledge. It doesn't know the difference. Yeah, it's just more weights. Pure knowledge with no restraints.
[02:58:18] [SPEAKER_02] Needless to say, I did not make napalm methamphetamine or a Molotov cocktail. And frankly, you probably find all of that information at your local library, kids. I was going to say, it did get
[02:58:30] [SPEAKER_05] it all from the internet, but we also know that it does matter when you make something easier. When you lower the bar, more people can jump over it.
[02:58:40] [SPEAKER_02] That's right. I mean, that's really what this is. It's a bicycle for the mind and Steve Jobs. Famous phrase. It's a
[02:58:47] [SPEAKER_05] best analogy ever.
[02:58:48] [SPEAKER_02] Yeah, it's a it's but that's not a bicycle. In this case, it's a Formula One race car for the mind. Yeah, and soon to be a rocket ship. And sometimes it spins out. Sometimes you have rapid unplanned disintegration, whatever they call it. Deconstruction. Deconstruction. Steve Gibson is a GRC.com, the Gibson Research Corporation. You will find him there, including all of his works. And they are mighty like Spin Right, the world's best mass storage maintenance
[02:59:18] [SPEAKER_02] recovery and enhancing utility, performance enhancing utility. You really need it if you have an SSA or a rust, we call them rust drives now. Did you know that? No longer spinning drives, they're rust drives. If you have rust or solid state, you need Spin Right, you get a copy there. He also, as we were talking about earlier, has that fabulous DNS Benchmark Pro. Maybe the speed of your internet isn't your DNS server. Maybe you get some packet loss. It's very
[02:59:48] [SPEAKER_05] easy to determine whether you've got some connectivity problems, which is another cool
[02:59:54] [SPEAKER_02] app. That's actually useful. That's a nice side effect. Both of those are available at GRC.com. He's got a lot of free stuff there too, a lot of it. He's very generous with his time and his efforts. And, of course, you can send him emails. Or pictures of the week, always welcome. But, first, you have to whitelist your email address by going to, as he mentioned earlier, GRC.com slash email. Put your email address in there. He does some magic voodoo and whitelists you. There are two check boxes below it for two different mailing lists. One, the weekly
[03:00:24] [SPEAKER_02] mailing list of the show notes. Well worth it. I mean, it is, I don't know, 5,000 words every week of really useful stuff with links and illustrations. Steve puts his heart and soul into this thing. The second box is a very infrequently used email list for new products, which, you know, you might get one next year. Someday.
[03:00:46] [SPEAKER_05] Once I finish getting moved and all set up in our new place.
[03:00:49] [SPEAKER_02] He's got other things to do, and I'm really trying to him. He bought a, can I tell people what you bought? He bought a DGX Spark a long time ago. We were talking about this. He said, I need to learn more about this. He hasn't set it up. It's in the box. If you ever decide you want to sell it, I have a great deal of self-control. I mean, unbelievable. I am so impressed. I was in the middle of a show when mine came, and I opened them, I think it was this show,
[03:01:19] [SPEAKER_02] during the show. I couldn't hold back. You've had it sitting there all the time, that beautiful little golden box. There's just waiting for brains to be poured into it. You can also get a copy of the show at his website. He has 16 kilobit and 64 kilobit audio, MP3 audios. He also has, as I said, the show notes. You can download them directly each week. He's got transcripts written by Elaine Ferris. She does a great job. It takes a couple of days because she's a human. You'll get those all
[03:01:49] [SPEAKER_02] at grc.com. We have the show at our website, twit.tv slash sn. There's a YouTube channel for the video. A great way to share clips because everybody can watch YouTube or subscribe in your favorite podcast player. That'll make it very easy to get a copy of the show the minute it's available. You can even watch it. If you want the freshest version, you can watch us do it live. We stream this. Now, if you're in the club, of course, and we love you club twit members, please join the club. Makes a big difference. Keeps us alive.
[03:02:18] [SPEAKER_02] Twit.tv slash club twit. club twit members, you can go on the Discord, watch there. Great place to hang to. Great social network. You can also watch live, even if you're not a member, on YouTube, Twitch, X, Facebook, LinkedIn, or Kik. So, plenty of places to watch live. But, I think most people are going to watch it after the fact. Either way, we hope you will watch every week, and we hope you will be right back here next Tuesday, 11 a.m.
[03:02:49] [SPEAKER_02] episode 1100. We never thought we would get there. We never did. Maybe we aren't. Maybe this is all Steve's AI fantasy. I don't know. Thanks, Steve. We'll see you next week. Thanks, my friend. See you then.
[03:03:04] Bye.