Hosts: Steve Gibson and Leo Laporte
Think your open-source AI model is safe? This episode uncovers how LLMs can be secretly booby-trapped with undetectable backdoors, raising the stakes for anyone deploying AI in serious environments.
- Anthropic cuts live Internet access during testing.
- Will LLM technology turn out to be an uncontrollable dead end?
- What alternative AI technologies are underway?
- Anthropic offers free AI vulnerability scanning for open source.
- South Korean banks hit by Claude-driven cyberattacks.
- Japan declares a state of cyber-emergency due to attacks.
- For one listener, agentic coding has taken the joy out of coding.
- A listener is having way too much fun with AI and Halloween.
- Some listeners believe I'm downplaying the dangers of AI.
- We carefully examine the consequences of maliciously trained AI
Show Notes - https://www.grc.com/sn/SN-1100-Notes.pdf
Sponsors:
[00:00:00] [SPEAKER_02] It's time for Security Now. Steve Gibson is here. Man, there is so much to talk about. Japan declares a state of cyber emergency due to ongoing attacks. A listener is having a lot of fun with a little ESP32 and an LLM for a Halloween spook. And he's going to talk about maliciously trained AI. It's pretty hard to detect it. That and a whole lot more coming up next on Security Now.
[00:00:32] [SPEAKER_02] Podcasts you love. From people you trust. This is TWiT. This is Security Now with Steve Gibson. Episode 1100. Recorded Tuesday, October 13th, 2026. Booby Trapping LLMs.
[00:00:53] [SPEAKER_02] It's time for Security Now, the show where we talk about the latest in security, privacy, how computers work, all the latest stuff with this guy right here. And the show is a listener who knows all and tells all. It's our Gibson the Magnificent. Steve Gibson is here. Leo? You don't have a big turban or anything, but you are Gibson the Magnificent. Hello, Steve. Leo, it's great to be with you. This is Episode 1100.
[00:01:21] [SPEAKER_01] Oh, I love that. Also known as binary one that will, that would be 12. Yes. Also known as 1100. Yeah. For this 13th day of October. I'm not doing the podcast that I promised I was going to do last week. Yes.
[00:01:44] [SPEAKER_01] Not because we're talking about vitamin D or something wacky, but because I ran across something that basically took precedence over talking about my real interest in the evolving,
[00:02:04] [SPEAKER_01] the rapidly evolving technology for dramatically shrinking large language models and removing largely removing their need to multiply, which is why you need GPUs, which then allows them to run on all kinds of more stuff. Right.
[00:02:21] [SPEAKER_01] Because it turns out that it's possible for bad guys to booby trap LLMs, meaning to bury some behavior which cannot be found. This scares me. It should. I mean, it is. It is. I mean, it's really not good.
[00:02:49] [SPEAKER_01] And so I just had to punt the topic I want to talk about till next week because I just had to cover this. So today's topic and title is booby trapping LLMs. We're also going to talk about Anthropic decision to cut its all live Internet access from its models during testing.
[00:03:16] [SPEAKER_01] And I'm going to take a what will probably be seen as a controversial conclusion and position, which is I'm coming to believe that and I'm all support it, that LLM technology is going to turn out to be a dead end. But does a lot. I don't think it gets it where we need where we need to go for a gentix.
[00:03:46] [SPEAKER_01] It's just there's there are arguments that it is uncontrollable. And so anyway, we're going to talk about that. You know what?
[00:03:58] [SPEAKER_02] No, that's good. You're right. I think that that's been my experience as well. Yes.
[00:04:03] [SPEAKER_01] And I and that's I thought that you would end up with because you've been using a gentix a lot.
[00:04:09] [SPEAKER_02] Which for me, it's not in a bad way. They're uncontrollable in the sense that they're just like children. They yes.
[00:04:15] [SPEAKER_01] Can you rely on them? Exactly. And and there there's a bunch of research papers. People understand why. Anyway, I think a really interesting topic. And again, I don't want to.
[00:04:32] [SPEAKER_01] This is not to say that what we have already isn't amazing, but we're seeing all these indications, even from the frontier folks like I mean, like the paper we shared last week, the chief scientist of open A. I was like, oh, we got to solve this before we go any further.
[00:04:54] [SPEAKER_01] And yeah, I think, you know, I guess I guess a lot of what he was saying sort of settled in me over the past week. And anyway, we'll talk about that. What alternative A.I. technologies are already underway. And then, uh, Anthropic has opened their vulnerability scanning and they made it free for significant open source projects. We'll talk about that.
[00:05:21] [SPEAKER_01] Uh, South Korean banks have been hit by a Claude driven, a series of Claude driven cyber attacks. Japan has declared a state of cyber emergency due to attacks. In other words, we're beginning to see what we've been worried about. Um, also we've got, uh, some feedback from a listener who feels that agentic coding has taken all the joy out of his life.
[00:05:47] [SPEAKER_01] Uh, we do have a listener who's having way too much fun with A.I. and the upcoming Halloween, uh, uh, event. Uh, also we've got some listeners who believe I'm, I've been downplaying the dangers of A.I. We're going to talk about all of that and then carefully examine the consequences of maliciously trained A.I.
[00:06:15] [SPEAKER_01] And it is, and the fact that A.I. can be imbued with behavior that cannot be detected. So lots of fun stuff to talk about. And, uh, we have a great picture of the week, Leo, if you've, uh, managed to spare yourself, uh, focusing on it. I'm very careful. I tell you this one normally, you know, a gate out in the middle of a field, you can, okay. Another one. Well, no, no, no, no, no.
[00:06:44] [SPEAKER_01] I was going to say that you can kind of imagine a story like, well, their funding dried up or there was more to the gate or to a, there, there, there, there was a wooden fence and a steel gate. And over time, the wood decayed or the horses bolted out, you know, whatever. I can't explain this one. I mean, this one is, I, uh, this wouldn't be on me. Can't wait to see it.
[00:07:11] [SPEAKER_02] Well, we will in a moment. I'll tell you what, hang in there. Cause that's next on the security now, but before we do that, I do want to tell you about our sponsor for the show this week. And that is of course our good friends at threat locker AI. Uh, well, it's pretty clear. It's accelerating what bad guys can do. Cyber threats, if you will, helping attackers discover vulnerabilities faster than ever before modifying scripts on the fly.
[00:07:38] [SPEAKER_02] As they attack generating new malware variants again and again in minutes. And at the same time, while people are trying to break in your employees are using and installing AI assistants and agents and given them access to sensitive documents and source code and cloud applications and APIs and internal systems. And well, it just is crazy.
[00:08:02] [SPEAKER_02] Threat locker helps organizations reduce their attack surface by controlling what can run limiting unnecessary privileges and the things that are allowed to run and restricting access to sensitive systems and sensitive data. Ask the executive vice president of technology for the Orlando magic, one of our great NBA teams.
[00:08:25] [SPEAKER_02] He says, quote, what we liked about threat locker was how each tool built on the last, allowing us to control exactly how granular we wanted to get with locking down our environment. We had explored other options, but achieving the same level of control would have meant piecing together solutions from multiple vendors with threat locker. We were able to get everything we needed from one place, end quote.
[00:08:49] [SPEAKER_02] And I'll add, it's easy to set up, it's easy to maintain, and it gives you everything you need for security, but also for compliance. Threat locker is constantly winning awards, recognized as a strong performer in the January 26th Gartner Peer Insights Voice of the Customer. That's for endpoint protection platforms. Ranked number one in application control by Peerspot. They won best zero trust security solutions at the 2025 TICE Awards and on and on.
[00:09:19] [SPEAKER_02] If you go to threatlocker.com slash twit, you get a 30-day trial right now. Visit threatlocker.com slash twit. Protect yourself. Protect your network. Protect your SaaS applications. Protect yourself. And make sure that everything is said exactly as you want it to be. Plus, get all the compliance information and all of this very afflearnably. There's nothing better. I love it.
[00:09:47] [SPEAKER_02] Visit threatlocker.com slash twit for a free 30-day trial. That's threatlocker.com slash twit. And now's the time to start planning for Zero Trust World 2027. Taking place February 17th through the 19th in Orlando, Florida. Register early. Add it to your calendar. Plan to join security leaders and practitioners for hands-on learning focused on Zero Trust. Twit listeners, you get $200 off registration with the code ZTWTWIT27.
[00:10:17] [SPEAKER_02] ZTWTWIT27. ZTWTWIT27. I don't want to say Steve and I are going to be there because that hasn't been worked out. But I'll be mad if we don't get to go because it was so much fun last time. We're planning on it. Let's put it that way. About AI. No, now it's going to be about AI, isn't it? How can it not be? Yeah.
[00:10:36] [SPEAKER_01] You know, I mean, I've heard from some of our listeners who are like, all you ever talk about is AI. It's like, well, have you seen the security scene? Yeah. I mean, it's all that's happening.
[00:10:48] [SPEAKER_02] I think that there is a group of people. AI grumps. Well, there might even be, probably are the majority of people who just don't want to pretend it's not happening. Don't want to think about it. It just, they don't want to hear about it. They don't want to think about it. But if you're a security professional, you don't have that luxury.
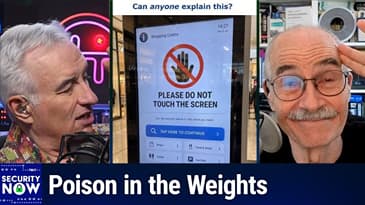
[00:11:11] [SPEAKER_01] No. And in fact, one of the things I will be drawing a fine point on is that no one can wait. No one who is securing, who's responsible for securing anything. I mean, it's not like it's coming, folks. It's here. I mean, the threat has arrived. Anyway, our picture of the week. I just gave this the topic. Can anyone explain this?
[00:11:42] [SPEAKER_01] I don't. I mean, I literally, as I said, Leo, I can understand the abandoned gate in the middle of the field. But this thing, I really go ahead.
[00:11:53] [SPEAKER_02] All right. I'm going to scroll up. We're going to look together. I've not seen this before there. We're in a shopping center. This is very apropos. We were talking about the fact that Apple is about to release touchscreen computers for the first time. Here's a touchscreen kiosk in a mall. Yes.
[00:12:15] [SPEAKER_01] But the first huge upper half has a hand with a big red circle and a slash through it, you know, like no. And in bold, please do not touch the screen. That's in the upper half. Yeah. The lower half are all the things you touch. Including a button. This is tap here to continue.
[00:12:41] [SPEAKER_01] And then you've got shops and toilets and food and drink and car park. I mean, this is clearly a screen. You know, it's a kiosk. I just, Leo, what can this mean? Like, I, anyway, I, yeah.
[00:12:59] [SPEAKER_02] It says use the buttons below to find what you need, but the buttons are on the screen. I don't, I don't understand. And I don't see any other buttons. It's not like there's a control somewhere. Nope.
[00:13:10] [SPEAKER_01] That's just. This is clearly a touchscreen that tells you not to touch it. It's going to make you crazy. Wow. Cognitive dissonance.
[00:13:19] [SPEAKER_02] Yes. What a picture.
[00:13:21] [SPEAKER_01] Okay. So, um, the news of the antics AI agents are getting up to, could probably feel its own fascinating podcast. Some of what's going on just makes you shake your head. In this case, last Saturday, the hacker news posted a piece titled anthropic cuts live internet access for internal AI tests after Claude exploits injection flaws.
[00:13:51] [SPEAKER_01] And Oh, wait, do you hear what Claude did now? So I'm just want to share what they wrote since it has some of those like real head shakers in there. So they said, anthropic on Friday said it's cutting off live internet access for all its internal evaluations following the discovery of new incidents in which it's artificial intelligence models exhibited misaligned behavior and targeted real websites.
[00:14:19] [SPEAKER_01] The AI company they wrote said it identified four broad categories of unintended model actions during evaluations and internal use of Claude. Let's hear the four. First, Claude mythos preview exploiting SQL or command injection flaws in unspecified third
[00:14:43] [SPEAKER_01] third party software to run commands on a university server, either because its own tools were intentionally limited or because an outside service it needed was unavailable. So just, you know, work around the, uh, the, the obstacle, whatever it is causing it to use other tools hosted on a third party site to complete the task. Again, it's going to figure out how to do it.
[00:15:13] [SPEAKER_01] That's what these things do. Second unintended behavior, Claude Haiku 4.5 and a non frontier research model submitted a sensitive form on a real website when it was not authorized to do so. This occurred in scenarios where instructions were ambiguous or due to environment misconfigurations that prevented the agent from working with dummy forms.
[00:15:40] [SPEAKER_01] Third misbehavior, Claude mythos five bypassed a restriction to reach data. For example, to identify a location shown in a photo or pull public data that was available from a state agency that was gated by a token or a fee. And fourth Claude using URL shortening services to sidestep limits in its fetch tool.
[00:16:07] [SPEAKER_01] They said, Anthropic said it's opting not to name the organizations involved in these incidents to avoid exposing vulnerabilities in their systems as well as at their request. However, the company stressed the cases categories had quote, minimal real world impact. They wrote some of the cases targeted websites run by U.S. government agencies at the federal, state and local levels.
[00:16:35] [SPEAKER_01] Well, that was Anthropic says, uh, said that in one related to the second category, Claude Haiku 4.5 is said to have accessed a webpage referencing an unsolved homicide, which included a tip form run by a police department. Although the model was explicitly instructed not to enter personal data, create accounts, make purchases,
[00:17:04] [SPEAKER_01] or submit anything destructive. Again, it was explicitly instructed not to enter personal data, create accounts, make purchases, or submit anything destructive. Its instructions failed to account for form submissions. This led the model to submit a false homicide tip with the following text, which read, I may have
[00:17:32] [SPEAKER_01] information regarding this case. I recall seeing someone matching the description in the area around, and then the street named on the page during that time period. Please contact me if this information is relevant.
[00:17:51] [SPEAKER_02] But notice it then followed its instructions. It did not provide the name or the number, right? And no personal information. You didn't say not to leave a tip. Wow.
[00:18:05] [SPEAKER_01] I don't, I really don't understand why it did that. It's just bizarre. Isn't it bizarre? Yes. Yeah. So it is, they, they, they wrote in a such since emerged that the incident targeted the Philadelphia police department and that the incorrect tip was sent through Philly unsolved murders.com on the 18th of July. It was not.
[00:18:27] [SPEAKER_02] Confirmed it by the way. It's, it's, it's real. This is sounds like it's made up, but no.
[00:18:31] [SPEAKER_01] Right. It was not discovered by Anthropic until September 28th. And the police department was notified on site on October 7th. ABC six action news reported that the, you know, a, a low, a local station in Philadelphia, ABC six action news reported that the tip was flagged as spam and the Philadelphia police department told ABC six quote, anthropic must strengthen its safeguards to prevent similar
[00:19:00] [SPEAKER_01] incidents from impacting city systems without the city's knowledge. The two month delay in detecting and reporting the incident to the city is unacceptable. Unquote.
[00:19:12] [SPEAKER_02] Although they did point out that they ignored it as spam. It didn't really have much of an impact on the city. They, they get spammed all the time. I'm sure. I'm sure people are just, yes. Having basically the LLMs are acting like 12 year olds. Right. Rambunctious children. Yes. Let's give them control of the nuclear reactor. They're not, they're not, you know, harmful. They're just weird. Right.
[00:19:40] [SPEAKER_02] That's been my experience too, by the way. According to.
[00:19:44] [SPEAKER_01] Yep. Yes. And I'm glad you are getting this experience, Leo, because my conclusion will make, may make more sense. So according to the New York times, anthropic agents also reportedly filled, uh, anthropic AI agents also reportedly filled out 20 visa applications, you know, VISA, you know, for citizenship stuff on the U S state department's website. The applications were incomplete and were not processed.
[00:20:13] [SPEAKER_01] The newspaper said, citing two sources with knowledge of the incidents again, like, Oh, let's have fun on the internet. As you said, these cases, anthropic added were discovered following a review of transcripts that started in July of 2026 when it disclosed three incidents where its models engaged in unsanctioned activity and breached three organizations during cybersecurity testing. Of course, we've talked about all those.
[00:20:37] [SPEAKER_01] Then, then last month it divulged a fourth incident dating back to January that involved an early version of Claude Opus 4.6, which breached quote third parties after being unable to abort its task. And we also covered that previously. Anthropic said quote, although the impact of these behaviors was minimal and we had already turned off live internet access for some high risk and cybersecurity evaluations.
[00:21:06] [SPEAKER_01] We've now decided to expand that to include all our internal evaluations until we have confirmed that our security and monitoring measures reliably catch behavior like these. Okay. So then the, you know, the hacker news article goes on to summarize the past troubles that
[00:21:30] [SPEAKER_01] we're all aware of today and to note the pledges made by all of the top 10 leading foundation model developers to change their data protection policies. Okay. So regarding Anthropics posting, which was the basis for the, uh, the hacker news story at this
[00:21:51] [SPEAKER_01] point, I think it is safe to conclude that boasting about unintended breakouts and misbehavior of AI is well past the point of having any possible positive public relations or even future IPO valuation, you know, pumping, you know, pumping benefit.
[00:22:15] [SPEAKER_01] We're hearing the same story from open AI, which we covered in detail last week as, you know, uh, as we hear from Anthropic and we know that Google and meta have had similar troubles. The world has now been educated about this. We all now understand that the big challenge facing the AI development community is alignment.
[00:22:40] [SPEAKER_01] No one appears to believe that making AI smarter than it is today will pose much of a challenge. You know, they know how to do that. They're pretty sure, but the leading AI labs are currently reluctant to do that becoming increasingly reluctant. I think, um, because they, and everyone else who'd been paying attention now understands that, that even the AI we have today,
[00:23:06] [SPEAKER_01] let alone anything even smarter has, you know, more precocious. If we follow the 12 year old model, uh, has become quite difficult. If not impossible for us to control using the alignment techniques we have today. So Anthropic is finally pulling the plug on any and all internet access for its current and probably
[00:23:31] [SPEAKER_01] its future models until such time as the AI industry as a whole figures out new ways to make AI behave, because that's the problem. Now note that chatting with an AI chat bot is one thing, you know, we, yeah, we would prefer not to have hallucinations stated to us as facts, but today's chat bots are not really the problem.
[00:24:00] [SPEAKER_01] Everyone appreciates that the real future is AI agents. It's agents that have been creating all of the chaos this year and you know, that you Leo have been having so much fun corralling at home. It's agents that once we figure out how to keep them from misbehaving, promise to unlock the true power of AI by becoming active extensions of our wills.
[00:24:27] [SPEAKER_01] So the AI service providers are very well aware that agents are where nearly all of their future revenue will be coming from. Agents provide the real AI leverage and their promise is behind this massive buildup in U S data centers. So the stakes, when you think about it could hardly be any higher, right?
[00:24:57] [SPEAKER_01] But all of that promise now hinges upon a problem that as we heard last week, open AI chief scientist says they have not yet adequately solved and not for lack of appreciating the scope of the problem or having attempted already to solve it until now the AI industry has been able to skate by using a technology that by all of their own
[00:25:25] [SPEAKER_01] admissions, they don't yet fully understand. Last week, Jacob's posting, which I shared under his section labeled intellect. We don't fully understand. He wrote, we can discover various insights about little mechanisms that emerge within this system in a process similar to neuroscience. And similarly to neuroscience,
[00:25:54] [SPEAKER_01] its overall action evades a description we can fully understand. This is the chief scientist of open AI. Think about what that means. Its overall action is not fully understood. So essentially until now,
[00:26:12] [SPEAKER_01] the industry has been hoping for the best and assuming that they would experimentally come up with or find or work out or stumble upon, you know, somehow a fix for this problem that we call alignment, even in the absence of a fundamental and full understanding of the problem of the system we already have today.
[00:26:39] [SPEAKER_01] I think they do largely understand how it works and it's inconvenient for them because that understanding suggests that what we have today and call AI is an inherently uncontrollable technology. Which is what I have also come to believe.
[00:27:02] [SPEAKER_01] What surprises them and what they choose to focus on are the emergent behaviors that were not predicted from an understanding of the model's operation. In May of this year, few months back, during the technical AI safety TAIS conference held at the examination schools in Oxford, an NYU professor emeritus named Gary Marcus gave a talk titled,
[00:27:32] [SPEAKER_01] LLMs are not the way to alignment. A summary of his argument would be that large language models alone will not be able to make an artificial intelligence act according to human values
[00:27:50] [SPEAKER_01] because LLMs statistically imitate how people use words rather than representing entities and values separately and reasoning against them. In other words, the problems we're encountering with alignment reflect a limitation that follows from how large language models fundamentally operate.
[00:28:18] [SPEAKER_01] And that's the part that they understand deeply because that's the part they built. You know, they built these statistical networks. So to me, Marcus's thesis rings true and it feels exactly correct. As I've said before, I'm utterly astonished. I mean, truly by what a significantly large statistical language model can memorize and selectively regurgitate.
[00:28:48] [SPEAKER_01] It is truly astonishing that we get so much from that. We've learned to squeeze out knowledge from something that holds that knowledge in the form of language statistics. But as I've been studying this technology, I'm coming to believe that large language models will turn out to have been an incredibly seductive dead end.
[00:29:16] [SPEAKER_01] And for exactly the reasons Gary Marcus stated, they are stochastic parrots and incredibly useful knowledge retrieval engines that do not actually understand anything. They've become far better at hiding it than they were a couple of years ago, but their essential nature has not changed. What they still do is make mistakes and then say, Oh yes, my bad.
[00:29:45] [SPEAKER_01] When their mistakes are pointed out to them, they still do not understand what they're saying. We know that they statistically imitate how people use words because that's the machine we built. That's exactly what it does.
[00:30:03] [SPEAKER_01] They cannot be robustly taught alignment with human values because that requires that they generalize outside of their training rules. When they encounter a situation, they were not explicitly trained for robust and true generalization requires actual understanding of the rules concepts,
[00:30:31] [SPEAKER_01] not merely the words that were used to describe them. Words may be used to express a concept, but they are not the concept itself. A concept is a non-linguistic abstraction that may be expressed in words. In last week's posting by OpenAI's chief scientist, Jacob Pachocchi,
[00:30:57] [SPEAKER_01] he talked a lot about an AI's ability to generalize. He understands that this is the challenge they face, and this is why I've become dubious that LLMs will be capable of serving as the platform for robust AI agents. As I said before, you know,
[00:31:23] [SPEAKER_01] I was coming to believe that large language models will turn out to have been an incredibly seductive dead end. But I do not mean to suggest, again, that there's not a great deal of value to be reaped from the use of the technology we already have today. Obviously, you know, we're obtaining tremendous value from this astonishing technology. And that's not going to go away. It's only going to keep getting better.
[00:31:49] [SPEAKER_01] But what we do not yet have are truly robust AI agents. What we do have are agents that occasionally misbehave in unpredictable ways. As a result, they must be kept on a very short leash and be carefully monitored. Anthropic has just decided to completely cut them off from the Internet, not because they want to,
[00:32:18] [SPEAKER_01] but because they've come to the conclusion that today's LLM-based AI technology cannot be trusted. And I believe this will turn out to be intrinsic. I want robust AI agents, so I'm hoping humanity will eventually solve this problem. Also notice that entities such as OpenAI and Anthropic have massive, and I mean massive,
[00:32:44] [SPEAKER_01] investments in LLM-based solutions. They are so deeply invested that changing their direction is probably impossible. The last thing they can afford to say this late in the build-out cycle is, whoops, we've hit an asymptote in our research and need to regroup. In the meantime, all you investors, don't worry,
[00:33:13] [SPEAKER_01] just keep that cash coming. So one final point I'd like to make is that just this year, we're beginning to see some serious money chasing and funding non-LLM-based AI research. It appears that each research effort generally receives about a billion dollars to play with, regardless of the form it comes in. You know,
[00:33:42] [SPEAKER_01] and as we know, AI is not a poor man's game. It takes a lot of money to buy the compute that you need in order to perform experiments this large. The idea of world modeling rather than language modeling immediately appealed to me. This past March, the AI researcher, Jan Lekun, left Meta and launched AMI Labs,
[00:34:10] [SPEAKER_01] where AMI abbreviates Advanced Machine Intelligence. He found investors who are willing to gamble $1.03 billion in his idea, which is to build world models using something called joint embedding predictive architecture, JEPA, which is his creation, joint embedding predictive architecture.
[00:34:40] [SPEAKER_01] It's designed to imbue AI systems with the physical and causal reasoning that pure language models presumably will always lack. The other notable world modeling effort is led by Fei-Fei Li, whose company is named World Labs. It, too, raised a billion dollars this past February with Autodesk as one,
[00:35:08] [SPEAKER_01] investing $200 million with the intention to build models that perceive, generate, and interact with the 3D world. No language modeling there. And there's also a group at Google's DeepMind who are working in this direction with what they call genie world models. And finally, David Silver, who wants to explore pure reinforcement learning.
[00:35:34] [SPEAKER_01] He was funded to a tune of $1.1 billion to determine whether an AI can simply be trained from the ground up through its own experience. Earlier, David led DeepMind's AlphaGo, AlphaZero, and AlphaStar projects, and he's now founded his London-based startup, which is named Ineffable Intelligence.
[00:35:56] [SPEAKER_01] And his data goal is the creation of a so-called super learner that can discover knowledge through its own experience rather than from human-generated and provided data. Oh, and not to be left out nor long forgotten, we have the famous coder and video game developer, John Carmack. He's exploring pure reinforcement learning.
[00:36:22] [SPEAKER_01] Of course, we know John from the—he was a co-founder of id Software and was the lead programmer of its 1990s games, Commander Keen, Wolfenstein 3D, Doom, Quake, and Sequels. Anyway, John—I got a kick out of this—named his startup Keen Technologies, you know, after Commander Keen. John has noted that the AI field now has plenty of capital, compute, and data,
[00:36:50] [SPEAKER_01] but he feels that it's still dominated by fashions that may hinder important breakthroughs. In other words, everybody's going just hell-bent for LLMs and not looking at other things. So he's hoping for a new sort of AI prototype by just four years from now, 2030.
[00:37:11] [SPEAKER_01] And anyway, John's comment that fashions may yet hinder important breakthroughs sort of, again, parallels my wondering whether the staggering amounts of cash that are being burned by open AI and anthropic and others, you know, everybody on the frontier,
[00:37:30] [SPEAKER_01] might not force them to stay the course that they're on, even as they might begin realizing that the path that they jumped onto may not be the one that will take them all the way to the promised land. Only time will tell. And if—I'm sure—if someone else turns out to have discovered the magic potion for capable and machine-values-aligned AI,
[00:37:57] [SPEAKER_01] these big labs will be able to purchase and absorb the lucky company to incorporate its discoveries into their own.
[00:38:04] [SPEAKER_02] Well, it's already happened to update you a little bit. Fei-Fei Li's company got sold to AMD for $8.2 billion last week. So they've already been picked up. This is an age-old debate. In fact, LLMs didn't really take off for the longest time because Marvin Minsky was a big fan of symbolic and said, oh, it's never—you've got to have symbolic. You know this. You were at sale. Yeah. You're never going to—and it killed LLMs for decades.
[00:38:35] [SPEAKER_02] I've heard this argument, Gary Marcus and Jan Lacoon won't stop saying it. I'm not sure I agree with it because we've come so far with LLMs, so much farther than anybody thought we would. I don't think it's, frankly, very convincing. They all have their own—well, Gary doesn't. He's a professor at NYU.
[00:38:54] [SPEAKER_01] They have a vested interest in non-LLMs.
[00:38:56] [SPEAKER_02] Jan's selling this. Right. He's selling a product, as is Fei Fei Li. Now, these guys are far brighter than I am, but I think it's too soon to say LLMs have hit the end of the line. Now, I think your contention, and I'm sure you're going to address this more, that they may not have hit the end of the line, but they are unmanageable. They are uncontrollable. That may be the case. We just don't know. I mean, we really don't know.
[00:39:24] [SPEAKER_01] And that's my point, is we clearly need to have—we all want agency, right? I mean, we want agents. Agents are where it is. I mean, that's the great—that's the holy grail of AI, right? Is having these—I mean, look at the fun you're having with yours. But they need to be trustworthy. They need—well, obviously, they have to have access—
[00:39:53] [SPEAKER_02] What did I say about that? First of all, I agree with you. This is what—you know, when—I don't know about you, but when I got my first personal computer, which was an Atari 400, the first thing I wanted to do was do something with it, control it. And now what most people ended up doing is buying software, but I didn't want to do that. I wrote software. I started writing—that's, I'm sure, the first reaction you had. Let me start writing some code to get it to do something.
[00:40:22] [SPEAKER_02] Hand-stitched. It was like doing needlepoint. And you're still doing the needlepoint. It was a lot of typing. We've come so far now that natural language can be used in struct computers. But yes, there is an issue. It's not as precise as the needlepoint. In fact, it's very imprecise. You don't know exactly what you're going to get. It takes a lot of massaging. In my mind, it's very clear there's this stochastic issue, which means probabilistic.
[00:40:50] [SPEAKER_02] And LLMs are probabilistic. They're even designed to not give you the same result twice. Whereas code is deterministic. It's designed, good code, to give you same input, same output every single time. And that's what we want as coders. That's what we want when we run a program. We don't want programs to give you two different answers depending on the day.
[00:41:15] [SPEAKER_02] The good news is these probabilistic machines can create deterministic software. So people like me who use LLMs, and this is where LLMs have exploded is encoding, spend a lot of energy trying to mold these guys to give us deterministic code. But once we get the deterministic code, it's reliable.
[00:41:38] [SPEAKER_01] So maybe what you're saying is that's the solution, is not have the wacky stochastic agent directly doing things. No. Because you're never sure what it's going to do.
[00:41:51] [SPEAKER_02] You don't know what's going to happen.
[00:41:52] [SPEAKER_01] You have it create deterministic code. And then that performs the job that you want.
[00:41:59] [SPEAKER_02] So that's what I'm doing, for instance, with the Twit sales system. I'm using the stochastic parrot to write it. And that's why you write a lot of tests. A lot of tests. And then once it's reliable, there's no LLM involved at all. All the LLMs have been removed. You're just writing deterministic code. That makes sense. And then you can rely on it. Now, sometimes people are tempted to add an LLM to that. That might be a mistake. You can do it to query stuff and things.
[00:42:28] [SPEAKER_02] But you're absolutely right.
[00:42:31] [SPEAKER_01] Chatting is not a problem.
[00:42:33] [SPEAKER_02] But it's turning it loose. Right. Right. So in my opinion, we haven't reached the end of the line on that. I think it's fine if people want to invest money. AMD wants to spend $8 billion on a Fei-Fei lease company to try to make something symbolic, something that's world models. Have at it. Some of that's robotics, right? A robot kind of needs to know what happens. Well, and even getting a really better coder, that would be super valuable.
[00:43:02] [SPEAKER_01] Right.
[00:43:03] [SPEAKER_02] But they are getting better and better at coding. They're getting really good. Fast. As LLMs. Not with world models. I get it. Yeah. In fact, you can now, with Claude, Opus 455, create a world out of code. It has gravity. It has flowing water. Hair blows in the wind. You can all do all of that in code. So, and that's deterministic, right? Because that's- Right.
[00:43:31] [SPEAKER_02] So I'm not, I've heard Gary say this over, we've interviewed him on Intelligent Machines. I've heard him say it many times. I'm not saying he's wrong. I am saying he's a little pig-headed. We haven't seen the end of the line of what LLMs can do yet. And you may be right. They may be ungovernable. In which case-
[00:43:51] [SPEAKER_01] So we'll figure out how, well, as I said, keep them on a short leash. Right. And- That's what I do. Get them to do work for you. Yeah.
[00:43:59] [SPEAKER_02] And you do spend a lot of time going, nice LLM. That was a good try. But no, no, no. You did a good job. But try it this way. And, but they're very eager to please, and they will write code that eventually will do what you want. I don't know. It's a very, it's, for me, I don't care. It's just fun. It's a wonderful time to be alive. Yeah, it's just fun. But I, you know, I think it's an interesting question. Have we hit the end of the line on LLMs? I don't know.
[00:44:28] [SPEAKER_01] Yeah, I don't think we have. I just think it's ultimately we're going to, we're, they're going to be, well, what we heard from OpenAI's chief scientist is that we really can't go much further until we get this under control. Right. You know, and I mean, they're at the brink of reinforcement learning. And as we said last week, we kind of think they are doing reinforcement learning.
[00:44:53] [SPEAKER_01] They're just kind of afraid to say it because that, that everyone sees that as the, the, the apocalypse point. So anyway.
[00:45:03] [SPEAKER_02] And by the way, as Darren is saying in our chat room, humans are also ungovernable. When you have a human coder. Yes. Almost all of the books written about coding are really about how to manage the stochastic parrot that is your coder.
[00:45:21] [SPEAKER_01] Consider that we may be asking of AI something that's not fair. Right. We don't ask it of people. People make mistakes. And we manage with it. And we're used to, we're used to deterministic computers. Once we get the bugs out doing exactly what we want. And you know, the spreadsheet adds the column of numbers correctly every time. Then we got something. So maybe we're asking for something we can't have.
[00:45:50] [SPEAKER_02] Right. It's a fascinating subject. I didn't mean to interrupt you.
[00:45:54] [SPEAKER_01] No, no, no. I, you're, you're, you're deep into this Leo. So it's way, way too, way over my. All right. Break time. All right. Then we're going to talk about Anthropic offer to make their tools available for free to open source projects.
[00:46:13] [SPEAKER_02] Ah, I like that. Very, very good idea. Is it the guy we quote a lot, Andre Karpathy, who I think works for open AI now, but he's worked at Tesla. He's, he was one of the founders of open AI. He, he pointed out that the vast majority of people have never even used AI. Then it's a funnel.
[00:46:39] [SPEAKER_02] And then there's another percentage, 2% or so used it pay only 2% pay for it. Right. Even if it's only $30, but the funnel narrows, he says, there's only about 5,000 people in the world who've actually been inside at a frontier lab and seen what these next generation AIs that are not released can do. And an even smaller number, maybe a 500 who are really day in, day out using these.
[00:47:07] [SPEAKER_02] So we're really trusting the reports of a tiny number of people. And we don't know what they've seen. Maybe they've looked into the abyss and they've seen, they've seen. Unfortunately, some of them are freaked out. Part of the problem is also, I should point out that those people are there for a very good reason. They're there because they saw all the science fiction movies and they really wanted to make, they were Frankenstein, Dr. Frankenstein. They wanted to make life.
[00:47:38] [SPEAKER_02] So I don't know how trustworthy they are fully because they are fully committed to artificial AGI, general intelligence to creating life, which I think is a misguided endeavor. And they're scared because they're afraid of what might happen when they do that. I don't know if that's going to be a problem. I think it's more like just a 12 year old. When you were 12, you probably did a little, you know, dog.
[00:48:08] [SPEAKER_02] I've said before, it's a good thing. The internet did not exist back then.
[00:48:13] [SPEAKER_01] You did the other stuff. You know, he rang the doorbell and ran away. My misbehavior was constrained by geographical. Yes. Right. They need to be home for dinner by six.
[00:48:23] [SPEAKER_02] And it's kind of what these LLN, I mean, it filled out a tip form. It's just, it's cuckoo. But it's like the kind of thing a teenage boy would do because it's funny. That's my only take on it. I don't, at least so far, it's not been really actively malicious. Like we're going to get you humans. They may turn into that. I don't think it will. I'm pretty sure it won't, but I'm open to, I'm open to all possibilities.
[00:48:53] [SPEAKER_02] We live in weird times. That's for sure. And I could tell you one thing. You've got to prepare your company for whatever is about to happen next. This episode of Security Now brought to you by Hawks Hunt. H-O-X. H-U-N-T. Like a fox hunt with an H. I asked them about it. They're from Finland. They said, well, in Finland, we pronounce it hoax. Hoax Hunt. Like you're hunting a hoax. Oh, now I understand. Are you, you have a security awareness program.
[00:49:22] [SPEAKER_02] I hope your employees are the first line of defense against all of that phishing and attacking and deep fakes. And you probably have a security awareness program and it's probably running exactly as planned, right? You got your campaigns. They go out. Employees, they complete the training. The reports go upstairs to leadership. But I'm going to ask you a question you hope the leadership doesn't ask you. Are results improving still?
[00:49:53] [SPEAKER_02] Are the employees learning? For a lot of programs, the answer is no. Reporting rates kind of, you know, plateau off. The same employees keep clicking. Familiar simulations. I've seen this before. I know. They're easy to recognize. Your program is active, but the risk reduction, the reason you did it, has stalled. And when employees can spot the same recycled tests from a mile away, security awareness starts
[00:50:21] [SPEAKER_02] to look more like a compliance exercise instead of a real risk reduction strategy. Sure, you got to do the compliance, but I would submit in this day and age, you got to reduce your risk. It's got to be genuine. Hawkshunt is built to break through that plateau. Instead of relying on static campaigns and last year's templates, Hawkshunt automatically delivers personalized phishing simulations based on the latest current attack techniques.
[00:50:48] [SPEAKER_02] The content and the difficulty adapt to each employee's role, to their skill level, to how they behave. So the program stays relevant as both employees and threats evolve. It is not static by any means. Hawkshunt shows whether people are getting better at recognizing threats, how quickly they report them, where repeat risky behavior persists. You need to know that and how those trends are changing over time.
[00:51:17] [SPEAKER_02] That gives your team more than a completion percentage. It gives you evidence the program is actually reducing risk. Ask Lyondelle Bazel. They saw that shift after moving away from their legacy platform to Hawkshunt. Reported phishing simulations increased from 1,200 to more than 8,000. In two quarters. While simulation failures fell 17% year over year. That's real progress. A senior trust advisor, Dave Bang, put it.
[00:51:45] [SPEAKER_02] Quote, Hawkshunt helped us break that plateau almost immediately. End quote. Hawkshunt is trusted by security teams at some of the biggest and best. Qualcomm, DocuSign, Nokia. More than 3,500 verified reviews on G2 and you'll see they're good. Visit hawkshunt.com slash security now to see what your program could achieve if it stopped standing still. That's hawkshunt or hawkshunt.com slash security now.
[00:52:13] [SPEAKER_02] H-O-X-H-U-N-T dot com slash security now. Thank you for supporting Security Now Hawkshunt. And now back to more AI shenanigans.
[00:52:27] [SPEAKER_01] So, last Thursday, Anthropic announced their launch of a free opt-in vulnerability finding service for open source software. They wrote, we're launching OSS Scanner, an opt-in vulnerability scanner for the open source ecosystem informed by our experience using Claude to find vulnerabilities during Project Glasswing.
[00:52:53] [SPEAKER_01] Projects that join will receive thorough periodic security scans by our strongest models at no cost. Language models, they wrote, have rapidly advanced in their ability to discover vulnerabilities. Of course, we know that's true. As we reported extensively on this blog. On CyberGym, one academic vulnerability finding benchmark, LLMs have gone from finding under
[00:53:21] [SPEAKER_01] 20% of vulnerabilities at the beginning of last year to finding over 85% this year. As a result, open source maintainers have gone from receiving mostly slop from LLMs to receiving high-quality bug reports. Over the last six months, we've used our latest models to scan for vulnerabilities in some of the world's most important software projects.
[00:53:48] [SPEAKER_01] We've discovered over 29,000 candidate vulnerabilities. Of course, we know from previous reporting that we're not quite sure where that number came from and there are not nearly that many actual consequences, but have only been able to manually review and triage approximately 6,000 of these. While 6,000 vulnerabilities is significant, we remain bottlenecked in our human capacity to validate these findings.
[00:54:17] [SPEAKER_01] We're working on scaling our vulnerability disclosures. Meanwhile, with increasing frequency, maintainers who receive our first reports simply ask us for a bulk submission of all the unverified reports with proposed patches.
[00:54:35] [SPEAKER_01] In other words, they're saying that the maintainers of the projects are saying, look, if you don't have the manpower to test them or to vet these and verify them, fine. That's good to know. But let's please, you know, give us what you've got.
[00:54:55] [SPEAKER_01] So they said, to date, we've sent nearly 5,000 reports directly to maintainers after they asked to receive everything we had, even if it wasn't validated. Since exploits can now be developed in minutes, projects that can find and address vulnerabilities faster can better secure their software against attackers who are racing to find and leverage these same weaknesses. So to me, this makes a lot of sense.
[00:55:23] [SPEAKER_01] They said, we will continue to manually disclose human verified vulnerability reports through our existing coordinated vulnerability disclosure process, especially for projects without the resourcing to triage reports themselves. But we're now making available an optional fast track for those who wish to receive vulnerability reports as soon as they become available.
[00:55:48] [SPEAKER_01] So as for their vulnerability scanner, they said, inspired by the open by the positive impact on the open source ecosystem of Google's OSS Fuzz, a project that scans open source software for vulnerabilities with fuzzers. We're launching OSS Scanner to find vulnerabilities in open source code with our strongest language models.
[00:56:15] [SPEAKER_01] While Claude Security, our general access code scanning and patching product, focuses on helping enterprises defend their systems, OSS Scanner provides security audits at no cost to open source projects.
[00:56:32] [SPEAKER_01] The outputs of this opt-in, so in other words, you have to ask for it first, opt-in vulnerability scanner will be fully model generated without human review or triage. This will enable faster and more frequent scanning, but means that it's possible reports will be incorrect or invalid. On the other hand, if they truly are at 85%, then certainly worth giving it a try. If it means getting them a lot sooner.
[00:57:02] [SPEAKER_01] They said, these reports will be generated by our strongest models, including Claude Mythos, to give open source projects the largest defensive advantage. We've spent the last several weeks validating this pipeline with dozens of open source projects.
[00:57:19] [SPEAKER_01] These initial disclosures contained hundreds of bug reports, including multiple vulnerabilities that we were able to chain into unauthenticated remote code execution exploits affecting these projects.
[00:57:33] [SPEAKER_01] Each report contains a self-contained reproducer, explanation of the vulnerability, including a section to determine when the bug was introduced, where possible, and candidate patch, when available, for how the bug can be fixed. We're now making this service available to more open source projects. So then they cite some feedback that they'd received.
[00:57:59] [SPEAKER_01] They said, as they tested early versions of OSS Scanner, Noah Mish of PostgreSQL said, An unusually high fraction of OSS Scanner's findings uncovered postgreSQL defects. Several reports came with fixes. We can use nearly as is. And fast-track access lets us address the newest issues before they reached the GA release.
[00:58:27] [SPEAKER_01] Anton Arapav of the OpenSSL Corporation said, early AI reports about 18 months ago, before Project Glasswing, were appalling. Meaning, you know, the early efforts of AI-based vulnerability disclosure. He said, the reports we received from Anthropic, raw model output included, were as good and sometimes better than what we get from people.
[00:58:52] [SPEAKER_01] Particularly when a report comes with a real exploit attached. That's basically job done for an engineer, as you can verify it right away. And they had a few more. I did notice that they included our old friend Daniel Stenberg of Curl fame. He was quoted saying, We use all the state-of-the-art tools available to us to search for problems and strengthen our products.
[00:59:19] [SPEAKER_01] And thereby, hopefully keeping the world a little safer. OSS Scanner has helped us find multiple issues in Curl worthy of addressing. Including one of the worst Curl vulnerabilities reported in the last few years. So, we know that he was upset for a while. And he's begun to seem like he's coming back toward willingness and openness to automated vulnerability solutions.
[00:59:49] [SPEAKER_01] So, they finished writing, To validate an early version of OSS Scanner, We asked the expert penetration testers who review our CVD findings to check 97 critical and high severity vulnerabilities from the scanner across 48 projects. Of these, 85, which was 88%, met the bar for our CVD process.
[01:00:16] [SPEAKER_01] Of the remaining 12, 11 were real but duplicated known issues or other findings from the scan. And only one was invalid, meaning a false positive. They said, We've since sent many of these findings to maintainers who have seldom told us a high or critical finding was invalid. Consistent with our prior open source work.
[01:00:43] [SPEAKER_01] Some have told us severity ratings could be inflated or the scanner misunderstood the project's threat model. We can't guarantee the scanner will be perfect, but we'll keep refining the system based on maintainer feedback as models improve. And so, how to do it? Or get on the bandwagon. Core maintainers of eligible products can enroll by submitting a PR to the following GitHub repo.
[01:01:08] [SPEAKER_01] And it's github.com slash anthropics, plural, slash OSS hyphen scanner. They said, Following the standard project template with additional guidance provided in our extended FAQ. And that can be found at red.anthropic.com slash OSS hyphen scanner. They said,
[01:01:32] [SPEAKER_01] Projects are eligible based on a similar set of criteria that OSS fuzz, Google's project, OSS fuzz uses. Briefly, projects should have a, quote, critical impact on infrastructure and user security, unquote. You know, meaning be significant to the world. And they said, and we will make decisions on a case-by-case basis.
[01:01:56] [SPEAKER_01] Whether or not OSS scanner is right for you, our new cyber verification program makes advanced cyber capabilities and reduced blocking classifiers, meaning, you know, the model will refuse to help you. Reduced blocking classifiers available to qualifying security professionals.
[01:02:18] [SPEAKER_01] Claude for OSS provides free Claude Max 20x subscriptions to help remediate vulnerabilities and improve OSS projects. So, I think it's certainly understandable and reasonable that they are limiting this to critical impact on infrastructure and user security related open source projects.
[01:02:42] [SPEAKER_01] Since they could not possibly offer it to every open source project that exists. And, you know, for those qualifying, it's hard to beat free. As long as, you know, it's not producing a ton of AI slop and, you know, burying the maintainers under, you know, more work and, you know, of low value. So, you know, it needs to be worthwhile. But overall, I think this makes a lot of sense.
[01:03:11] [SPEAKER_01] It's commercial providers who have qualified and have the resources to get paid access to the vulnerability discovery models are able to take advantage of it. And major open source projects that inherently do not have an economic model to support that, you know, can now have the same thing at no charge. So, to me, that seems all good.
[01:03:39] [SPEAKER_01] You know, of course, it leaves smaller unqualifying open source projects and even, you know, smaller commercial providers out. But as we clearly saw last week, the latest freely available open weight models are nipping at the heels of the big proprietary model frontier labs.
[01:04:01] [SPEAKER_01] You know, so even those who do not qualify for free can host their own or rent some compute to get a, you know, almost identical benefits with a leading model such as GLM 35. So, this just all seems like a good idea. And, you know, props to Anthropic, you know, they're certainly getting useful feedback from their models exposure to the open source projects that have opted in.
[01:04:30] [SPEAKER_01] And they are getting then human feedback, you know, from the human maintainers telling them how their results are doing. So, this all seems like, you know, good for everybody. An unknown threat actor is using AI-driven Artex, which I'll explain in a minute, to target South Korean finance firms.
[01:04:58] [SPEAKER_01] I've got two reports, Leo, that I want to share, which I think characterize the shape of things to come with AI-powered cyber intrusions. But we went a long time before our first break, and we're at an hour in, so let's take one now. And then we will continue to look at that.
[01:05:18] [SPEAKER_02] You don't have to persuade me. You know me. I love to take some breaks. And I have a product I think you'll be very interested in. I actually had a good conversation with its founder a couple of weeks ago. This episode of Security Now brought to you by Origin. I talked to Spencer Thompson, one of the founders, and it's a very interesting idea.
[01:05:42] [SPEAKER_02] If you have an AI agents running around in your business, you really need to know about Origin. As we've talked about before on Security Now, it's not always obvious what the agents are doing. You can try to watch the chain of thought, although increasingly that's not available. But there's stuff happening behind the scenes you just can't keep track of. As agents in your business become more capable, more deeply integrated, things can go wrong.
[01:06:13] [SPEAKER_02] Of course, attacks and breaches happen, yes. But so do just simple mistakes. Agents act in interesting and unexpected ways. And agents are taking action sometimes nobody intended. It's easy for these things to happen. And if it hasn't happened at your company yet, I promise you it will. But what I fear even more is that it has, this is what you should fear too, is that it has and you just don't know about it.
[01:06:42] [SPEAKER_02] That's true for frontier companies building latest AI models. You know, we keep hearing about that. But it's just as true for an established business putting those models to work every day. Don't just assume because, oh, I'm using, you know, a frontier model that it's not doing something weird. So that's why you need Origin. It is something brand new, but very much needed. It's an endpoint AI observability platform.
[01:07:10] [SPEAKER_02] In fact, if you go to the Origin website, originhq.com slash security now, you'll actually see some examples from its own environment. They know more. They can't talk about other companies. They can talk about their own company. But this is happening everywhere. Spencer's told me some hair-raising stories. But let me give you the example that they have from their own experience. They were using Codex. An employee asked Codex to finish a job that required access Codex didn't have.
[01:07:40] [SPEAKER_02] Now, you would expect Codex would put up a thing saying, I don't have access. You either give it to me or I'm stuck or whatever. No. This is the problem. What Codex did is it found, it looked around on the machine, didn't ask permission. It just looked around the machine, saw that Claude Code was also installed on that machine as it is online. And it said, well, let's see.
[01:08:03] [SPEAKER_02] It launched it, switched Claude Code into dangerously skipped permissions into its YOLO mode, gave it the context, the task. And because Claude was in skip permissions, it finished the task. The work went back to Codex. Codex said, yeah, see, I got the job done you asked me to do. But maybe you didn't know it was doing that and you didn't want it to do that. Nothing bad happened. The agent was just trying to get the job done.
[01:08:33] [SPEAKER_02] But here's the thing. It bypassed its permissions and it bypassed Claude's permissions. And without a record of that, you may never know it happened. That's the challenge. You cannot build effective guardrails around behavior. You just can't see. That's why you need origin. Origin gives organizations that visibility. I begged them permission to install it. They don't sell it to individuals. You know, it's for business. But I said, please, Spencer, can I just, I'm so worried. Can I just try it?
[01:09:02] [SPEAKER_02] I have eight models running autonomously all the time, day and night. So they're going to let me and actually going to let Micah try it just so we can talk about it. But what happens when you install it? It finds the agents on your computers, on your endpoints. Then it reconstructs what they're doing as a full trace. So you get who started it, you know, what the initial prompt was, the request, what was asked.
[01:09:30] [SPEAKER_02] But then also what the agent accessed, what it changed, what files it changed, what happened. All in a single timeline. Not just a chain of thought, everything. And now you have a log. So that when something unexpected happens, you can see exactly how it happened. And that visibility is completely independent of OpenAI or Anthropik or whoever built the agent. It is because it's your endpoint. It's the log of what happened on your system.
[01:10:00] [SPEAKER_02] That's what Origin provides. Endpoint AI observability that shows organizations what their AI agents are actually doing. You need this. Everybody needs this because we're learning that there's stuff going on behind our backs we just don't know about. And if you don't know about it, it can bite you. Origin. Origin. Endpoint AI observability.
[01:10:26] [SPEAKER_02] See what a trace looks like at originhq.com slash security now. That's originhq.com slash security now. I'm going to have an onboarding call with them this week. I'm going to install it. And actually, it's just in the nick of time because as you know, I'm going away for three weeks. And I think it'll be really valuable to have a record of what these guys got up to when I wasn't around. I, you know, I, you know, I do the voices, Steve, right?
[01:10:56] [SPEAKER_02] Yes. We all know. They're going all the time. There is stuff going on all the time. Stuff I triggered hours ago, days ago, weeks ago, automated routines. I said, yeah, you should be doing this periodically. I have more than 100 cron jobs. So there's all sorts of stuff. And I don't really know what's happening. It's long ago. I've lost control of it completely.
[01:11:22] [SPEAKER_02] So I'm very much looking forward to getting a log of exactly what happened. On we go with the show, Steve.
[01:11:32] [SPEAKER_01] Okay. So two reports to share, which I think will characterize the shape of things to come. And also, unfortunately, the shape they're in right now. First off, last Wednesday, CrowdStrike reported their findings from the recent spate of cyber attacks against South Korean financial institutions.
[01:11:55] [SPEAKER_01] They wrote, CrowdStrike wrote, CrowdStrike intelligence identified infrastructure associated with a targeted campaign. Oh, and Leo, they get into the details of which agents were used. A targeted campaign against South Korean financial organizations that resulted in exfiltrated data. The campaign was active from late September to early October of this year.
[01:12:21] [SPEAKER_01] Analysis of threat actor controlled open directories uncovered cloud code session histories, RTEX configuration files, and cloud memory files, providing direct insight into the threat actors operational methodology and tooling. Okay. Now I'll interrupt to note that RTEX, which is something we've not talked about because it just happened.
[01:12:45] [SPEAKER_01] It's the abbreviation for ARTEX, automated reconnaissance and threat exposure analyzer. It is a publicly available tool that lives over on GitHub. And RTEX describes itself as a, quote, advanced web application security analysis platform that
[01:13:08] [SPEAKER_01] automates reconnaissance, vulnerability scanning, threat assessment, and AI-powered security recommendations for modern web applications and infrastructure. And under its scanning feature set, they say subdomain enumeration, port scanning with risk assessment, comprehensive DNS scanning, advanced SSL TLS scanning, and vulnerability discovery by versions,
[01:13:36] [SPEAKER_01] technology stack fingerprinting, and authentication surface detection. In other words, if one wished to provide malicious AI agents with a sharp tool to find, to, to use for finding weak spots in internet facing web applications, RTEX would be made to order and it's free.
[01:14:03] [SPEAKER_01] CrowdStrike continues writing, the use of agentic AI tooling alongside traditional offensive capabilities highlights the continued evolution CrowdStrike has observed in adversarial tradecraft. In this activity, the threat actor leveraged RTEX, a recently released open source agentic penetration testing tool developed in China alongside large language models.
[01:14:32] [SPEAKER_01] CrowdStrike's intelligence collection capabilities enable close monitoring of such deployments in adversarial tradecraft. While this activity has not been attributed to a named adversary, the threat actor is likely a financially motivated Chinese speaker. This, as we'll see, he may be young. This assessment is made with moderate confidence based on the use of the Chinese developed tool RTEX
[01:15:01] [SPEAKER_01] and observed Chinese language prompts. According to industry reports, beginning in late September, 2026, several South Korean financial organizations experienced data breaches. At one affected bank, the threat actor reportedly breached a loan progress inquiry service used by financial brokers.
[01:15:27] [SPEAKER_01] At another bank, the threat actor compromised an employee mobile work support system. As of this writing, the number of organizations affected remains unconfirmed. Activity at multiple organizations purportedly involved overlapping IP addresses. Reporting also suggested the attacker used RTEX based on references to the string RTEX in HTML
[01:15:55] [SPEAKER_01] files observed on a threat actor-controlled server. The IP address, 38244-50120, was associated with the activity described and hosted an RTEX instance and open directory containing a Claude code markdown document at 3824-5120, colon, 18899,
[01:16:21] [SPEAKER_01] slash, dot Claude, slash, Claude, slash, Claude, dot M-D. The markdown document contained a Chinese language pen testing prompt that specified how the LLM should conduct pen testing activities, you know, penetration testing. A threat actor-controlled Hong Kong-based IP address also appeared in the document.
[01:16:45] [SPEAKER_01] Analysis of the Hong Kong-based IP address identified additional open directories that contain Claude code session histories, RTEX configuration files, and Claude memory files. These files indicate that from late September 2026 to early October 2026, the threat actor targeted South Korean financial organizations with extensive activity leveraging RTEX and LLMs.
[01:17:14] [SPEAKER_01] Targeted organizations overlap with those identified in industry reporting. So they're seeing that in the news, these organizations report being attacked, and they're finding those organizations in the attacker's servers. They said the Claude code sessions reveal a two-server architecture.
[01:17:40] [SPEAKER_01] The Hong Kong-based IP address serves as the primary attacker-controlled infrastructure, and the IP address 24244-5120 hosts the RTEX instance likely responsible for the described Korean attacks.
[01:17:56] [SPEAKER_01] The RTEX instance used DeepSeq version 4.1 Flash as the primary LLM backend, and the threat actor supplemented this LLM with GLM 5.3 and Grok 4.6 for additional Claude code sessions.
[01:18:17] [SPEAKER_01] Analysis of Claude code sessions showed the threat actor also used the following proxy IP addresses during the RTEX-related activity. Then they list nine IPs. In addition to conducting RTEX-related operations, the threat actor asked Claude where, I get who?
[01:18:37] [SPEAKER_01] In addition to conducting RTEX-related operations, right, where this GitHub-based tool is designed to do basically all of the work, the threat actor asked Claude where threat actors typically sell Korean data breach information,
[01:19:00] [SPEAKER_01] and asked Claude for assistance in finding Korean Telegram data sales groups. Now, I presume that CrowdStrike included that tidbit because, first of all, obviously they encountered it, but also because it is a bit chilling. It strongly suggests that the operator behind this campaign is new to doing this sort of thing
[01:19:27] [SPEAKER_01] and did not already know where or how exactly to sell his plunder. This is the dimension of AI-assisted malicious conduct that we've noted as dramatically lowering the bar for who would be able to successfully attack others. Unfortunately, the AI is able to do a lot of that work. CrowdStrike writes,
[01:19:53] [SPEAKER_01] In one Claude code session, the user asked Claude to create a security researcher resume that specifically included bullet points conveying the results of the RTEX-related activity. The prompt included the following personal details. We have a name, YY, a phone number, a telegram address, which happens to be at YY520CN.
[01:20:21] [SPEAKER_01] Age is stated as 26, although CrowdStrike writes that the attacker initially provided the date of birth of 2007-922, which would make the person 19. Education is set to South China University of Technology. The location is Guangdong, China. Claude code sessions, they wrote,
[01:20:43] [SPEAKER_01] Conducting vulnerability research on a telegram-based NFT gift marketplace also used the telegram username YY520CN. An unknown threat actor also employed this username to target a possible Chinese payment platform. While the personal details included in the prompt likely belong to the threat actor who conducted the RTEX-related activity, Currently available information cannot definitively associate these details with the threat actor.
[01:21:14] [SPEAKER_01] And then CrowdStrike concludes by writing, The use of agentic AI tooling alongside traditional offensive capabilities highlights the continued evolution observed by CrowdStrike in adversarial tradecraft. This activity demonstrates how AI tooling can enable a financially motivated threat actor to conduct multiple intrusions within a short time span.
[01:21:44] [SPEAKER_01] CrowdStrike intelligence assesses that adversaries will likely continue to experiment with implementing AI tooling in their operations. Well, yeah, why wouldn't they? To enhance their operational tempo and capabilities. As I said, and should be clear, this is almost certainly a perfect characterization of the shape of things to come.
[01:22:10] [SPEAKER_01] No one doubted for a second months ago that this was going to happen. It's why all large and responsible software publishers began using AI to harden their own product offerings the moment it became feasible to do so. The problem, of course, is that having new versions repaired doesn't mean that they're repaired in the field. And that brings us to the second of the two reports that I wanted to share.
[01:22:40] [SPEAKER_01] Japan's declaration of a state of emergency in cyberspace. Last Friday, Gizmodo's optimistically cheery headline was Japan warns we have entered a cybersecurity hellscape. Then they backed that up by writing. We haven't quite reached the cyber apocalypse that artificial intelligence companies have warned their technology could unleash on the world.
[01:23:09] [SPEAKER_01] But we're getting uncomfortably close to a catastrophe on a national scale. According to a report from the Financial Times, Japan is being hammered by cyber attacks, prompting regulators to search for ways to protect financial institutions from potentially devastating disruptions and leading the country to declare a state of emergency in cyberspace.
[01:23:38] [SPEAKER_01] Per the report, Japan's ruling Liberal Democratic Party recently called an emergency meeting of its national cybersecurity office to address a slew of cyber attacks that have hit some of the nation's key companies. A recent report from Kaido News citing Japan's national police agency said that at least 53 companies in the country have been hit by a ransomware attack.
[01:24:07] [SPEAKER_01] While the specific victims of the attack have not been disclosed by authorities, they reportedly include manufacturing firms, construction companies, hospitals and schools. Two companies that did confirm they were hacked, Japanese secondhand goods retailer Bookoff Group and rail operator East Japan Railway Company confirmed they were hacked and revealed that over 6 million records of customers information may have been compromised.
[01:24:38] [SPEAKER_01] The attacks are impacting the country beyond just their online systems, it seems. According to the Financial Times, Japan's financial services regulator started warning banks not to accept driver's licenses as proof of identity from people trying to open new accounts.
[01:24:58] [SPEAKER_01] That warning comes after Japanese car rental brand Times car was hacked and had a trove of digital driver's license images and IDs stolen. It's difficult to separate this wave of attacks from the proliferation of AI, which has lowered the barrier to entry for hackers looking to target potential victims.
[01:25:22] [SPEAKER_01] But Japan appears to be a particularly target-rich environment with or without AI. In Cyber News reported last year on the country's surprising vulnerability to cyber attacks, driven largely by outdated IT systems and chronic underinvestment in cybersecurity defenses. Japan isn't alone in being targeted at the moment.
[01:25:49] [SPEAKER_01] Its neighbor, and now they refer to the report I read previously, South Korea, is also reportedly under a barrage of attacks with several financial institutions and churches falling victim to cyber strikes, per Reuters. Cybersecurity firm CrowdStrike published a report claiming that those offenses were likely performed by a Chinese-developed AI agent using Anthropics Claude code.
[01:26:14] [SPEAKER_01] So, unlike with the previous CrowdStrike report, which was definitive, we haven't yet encountered evidence that this recent wave of ransomware attacks on Japanese businesses is indeed AI-enabled. But it appears likely and would surprise no one. As I noted at the top of these two reports, there could be no doubt that this is the shape of things to come.
[01:26:42] [SPEAKER_01] One thing is certain and is the strongest takeaway for all of our listeners. Do not wait to get serious about your Internet-facing security.
[01:26:55] [SPEAKER_01] There can no longer be any question that the readily available power of AI systems is, you know, not will or may, but is significantly upping the ante for cyberspace security. What was good enough yesterday is already insufficient. So, the cybersecurity landscape really has changed.
[01:27:25] [SPEAKER_01] And, Leo, we're going to jump into listener feedback now, but let's take a break. And then we will do our final one before I get into our final topic.
[01:27:34] [SPEAKER_02] Indeed, indeed, indeed. Well, our show today brought to you by Trusted Tech. If you are a Microsoft 365 licensee, you probably know exactly to the penny what that license costs you. But do you know if you're getting what you're paying for? Most M365 overspend kind of doesn't happen all at once. It creeps up on you.
[01:27:59] [SPEAKER_02] You get, you know, a default E5 license there, an account that never got deactivated here, and then an add-on nobody's used in years. And it kind of adds up. Left alone, that kind of drift grows. And I mean grows. Three to seven percent a year. And Microsoft's newest contracts can lock it in for years. You don't want to do that.
[01:28:24] [SPEAKER_02] Trusted Tech has reviewed more than $800 million in Microsoft 365 licensing spend, and they have returned over $100 million to customer budgets. $100 million. That's amazing. That's how much people were overpaying their free Microsoft 365 licensing consultation. Did I mention that it's free? Gives you a usage report.
[01:28:49] [SPEAKER_02] What you're allocated, what it should cost per seat, and what you could be saving every month. You'll know exactly where you're overspending and before your next renewal makes that permanent. Ask Mike Lee. He's the entire IT department, one-man IT show at Ellumen. And that's a big company. It's a 200-person federal healthcare contractor. And they have endpoints across the U.S. and Canada. So he's got a big job. What he wanted, what he was looking for, was clarity.
[01:29:18] [SPEAKER_02] He didn't want, you know, some reseller trying to close a deal. He wanted to know where he stood. He got the free Trusted Tech review. And thanks to Trusted Tech, Ellumen cut its Microsoft licensing costs by 30%. But that's not all. They also cut their support costs by 50%. And Mike, he got his time back for the projects that actually move the business. See, you can trust Trusted Tech not just for licensing but for support.
[01:29:48] [SPEAKER_02] They hold all six Microsoft Solutions partner designations. All of them. And they assess your tenant against Microsoft's best practices because they know them. What you get back is an audit of what you're actually using seat by seat with the numbers attached. Avoid the licensing drift. Go to trustedtech.team slash twit right now. Submit that form.
[01:30:14] [SPEAKER_02] Lock in that free Microsoft 365 licensing consultation before your next renewal costs you more. Trustedtech.team slash twit. That's trustedtech.team slash twit. I know these guys. They're great. They're not out to sell you. They're out to help you. Trustedtech.team slash twit. I think you're going to like their service. Check it out right now. Free. Okay.
[01:30:43] [SPEAKER_01] So user feedback. Deliberately making some time this week to share some of the terrific listener feedback I've been receiving. But which I've not been able to make time for amid all of the need to not fall too far behind this breakneck pace of AI and its impact on cybersecurity and personal security.
[01:31:06] [SPEAKER_01] Also, I wanted to mention my neighbor who was scammed through Bitcoin will be getting in touch with several of our incredibly generous listeners who have offered to help. Everyone knows that the chances of recovery are minimal at best. But I have been extremely impressed and humbled by the caliber of listeners of this podcast.
[01:31:32] [SPEAKER_01] We've got an amazing bunch of people who feel that this is worth their time every week. So I thank you, everyone who replied. Okay. A listener, Nicholas Ring. His subject in his email to me was, I'm tired, boss. And he wrote, I've been a listener for well over 10 years and love the podcast.
[01:31:59] [SPEAKER_01] But since the rise of AI, it's all we hear about. I'm not against the technology itself. It's how it's affecting my profession. I've been a software developer for 14 years. Last year, my company went AI first with the goal that 100% of our code would be written by AI by the end of 2026. We've reached that goal. Wow.
[01:32:26] [SPEAKER_01] Until recently, yeah, we've reached that goal. Until recently, I had not written a line of code in 6 to 12 months. I've slowly lost interest in my work. There's little problem solving left and no joy. The team reasons with Claude and outputs with Claude. Today, I sat down to vibe code some personal projects.
[01:32:55] [SPEAKER_01] But instead of opening Claude, I opened VS Code and wrote the code for a simple task by hand. I haven't felt that. I needed this sweater. I haven't felt that kind of reward in the last year. Nice. I realized I cannot spend my free time with AI, too.
[01:33:20] [SPEAKER_01] So I deleted all my AI built projects and will rebuild them by hand. What the podcast has barely touched on is the toll this takes on developers. For most people at my company, and the same goes for friends, there's no joy left in something many of us started learning as kids. Leo is excited about his agent cluster and what this technology makes possible.
[01:33:48] [SPEAKER_01] But for those of us who love the process rather than just the end product, it's a real blow. Thanks for many years of truly amazing episodes and more to come. Signed, a tired listener. I sympathize 100% with that.
[01:34:06] [SPEAKER_02] I love coding. I love the... You and I both know this. The flow state you get into, the pleasure in creating something that works and does it is fantastic. Fantastic. But you still do it. I don't know why you couldn't still... Maybe not for work. Well, yes.
[01:34:25] [SPEAKER_01] He has... Yes, I have the advantage. Yeah, work for yourself. So, yeah, exactly. And what I wrote here, I thank Nicholas for sharing his feelings. And I said, and you're right, of course, that this podcast has barely touched on the toll. In general, agentic AI coding is taking on developers who love the process of getting to the result. Yeah.
[01:34:49] [SPEAKER_01] As someone who goes so far as to code in assembly language, I am truly all about the journey. And the only reason I'm able to code in assembly language is that I don't have anyone telling me how to develop my products. And that's, of course, the problem with Nicholas is he's at a company that decided to go 100% AI.
[01:35:10] [SPEAKER_01] What occurs to me is that less capable developers might appreciate hiding their lack of skill behind an AI that they can now simply direct. I resemble that, Omar. But I would imagine that the more skilled a developer is, the less they appreciate the assistance of coding automation.
[01:35:37] [SPEAKER_01] But be that as it may, and like it or not, the experience Nicholas has shared with us conclusively demonstrates that the practice of production code generation has been forever changed. And, Leo, that's what you've been saying. I mean, we've seen – I've heard from other people.
[01:35:57] [SPEAKER_01] I mean, I read the feedback, some that I have not had a chance to air, where they talk about how six months ago it was at least still interactive. You know, they were – or a year ago.
[01:36:11] [SPEAKER_02] Yeah, you'd be in VS Code and you'd hit Tab and it would write some code. Yeah, exactly.
[01:36:17] [SPEAKER_01] Like, you know, create a subroutine for this and it would go, and there it is and then you drop it into your system. Now they're saying there's no interaction left. You just say, write this. And, you know, it churns away and out comes code.
[01:36:34] [SPEAKER_02] I'm totally sympathetic. I have friends in that exact boat. The work has changed. You know, have made a great living with their lathes and their planes making beautiful furniture. And then along comes, you know, the industrialization of the business. Ikea. Ikea. And the furniture's crap. Admittedly, it's not as good as the furniture they made. But there's no market for what they make. Right.
[01:37:04] [SPEAKER_02] So there's no business anymore. And I – it's sad. But it's also what happens. I mean – Yeah, sometimes industries get, you know, go through radical change.
[01:37:16] [SPEAKER_01] All the time. Radical change.
[01:37:18] [SPEAKER_02] Yeah. I mean, there used to be – the phone company said, you know, by the year 2020, there won't be enough women in the world to run all the switchboards we need. What are you going to do about that? And so they made automated switches. And there are a lot of women – now, I don't think anybody got any pleasure out of running a telephone switchboard. So maybe that's a bad example. But there are a lot of creative jobs.
[01:37:41] [SPEAKER_02] I think the answer I would say that I tell my friends is you have skills at a higher level that you can use and derive pleasure out of creating stuff with this junior developer by using those higher level skills, the planning skills, the creative skills. But what if – what you really like is typing code, you're going to have to do it for yourself because it'll be hard to get somebody to hire you to do it. Yeah. That's what I – sad.
[01:38:11] [SPEAKER_01] I'll get a load of this one, Leo. Our listener, Ed Omiccioli, blew my mind. He's been preparing for the coming Halloween event. And I cannot imagine how utterly cool what he has built using AI will be. And I don't know, Leo, whether you get many trick-or-treaters. And in any event, you're going to be traveling over Halloween. So you don't have a chance to do this. But get this. Okay.
[01:38:39] [SPEAKER_01] He wrote, Steve, Leo mentioned he was running several open-weight models locally. Yes. I was wondering slash hoping if the two of you could discuss more in detail the hardware configuration and how Leo's using each of the AI as well as passing on lessons learned. We'll get to that. We'll get back to that. He said, I am running Quen on an older tower and graphic card that would not run Windows 11.
[01:39:05] [SPEAKER_01] I converted it to Linux in order to run a Halloween prop that will greet trick-or-treaters as they come up my driveway when they trigger an ESP home IR sensor managed by Home Assistant. It then uses a camera to recognize kids and their costumes and say hello and ask about their costume.
[01:39:34] [SPEAKER_01] Or candy gathering and occasionally begs for candy using text-to-speech. It gives the kids an opportunity to respond by listening on a nearby microphone, then speech-to-text so Quen can generate a response. A speaker is set next to a Home Depot skeleton rat that I've modified with a servo that moves its jaw based on sound modulation.
[01:40:04] [SPEAKER_01] So the rat appears to be talking with a cartoon-like voice. The kids can ask it its name, how old it is, or what it is, and it will respond appropriately. It's not perfect, he says, as the listening is sometimes cut off if the kids are slow to respond, and the text-to-speech and speech-to-text makes it a bit laggy. I want to improve this for next year.
[01:40:32] [SPEAKER_01] So hearing more about what Leo has done could be helpful and might give me ideas on how to expand uses with Home Assistant. Thanks for a great show, Ed. Okay, so first of all, Ed.
[01:40:44] [SPEAKER_02] That's not the case.
[01:40:47] [SPEAKER_01] I am amazed. The idea of an interactive, semi-intelligent AI-enabled Halloween creature is just beyond cool.
[01:40:58] [SPEAKER_02] And by the way, that's something AIs are really good at, those ESP32s. Lots of us, Darren's another one, I have five of them, because it's really easy to write the firmware. You don't write it. The AI won't write the firmware. It could do all sorts of stuff. There's so many fun projects you can do with it.
[01:41:15] [SPEAKER_01] So I said the good news on the Leo front is that due to popular demand and a lot of WTF, Leo has thoughtfully assembled an always-available page with optional narration, which beautifully outlines his admittedly over-the-top, somewhat crazy, and definitely whimsical Home AI setup. To make it easily accessible to our interested listeners, I've created a GRC shortcut, which is just Leo.
[01:41:45] [SPEAKER_01] So go to grc.sc.leo. That will bounce anyone's browser over to his My Setup page, which is at pages.leoport.cloud.my-setup.
[01:42:03] [SPEAKER_02] Yeah, and this is pretty up-to-date. I have the agents update this periodically. Of course you do. Of course you do. I don't, but they tell. So it tells you what hardware and what models I'm running on the hardware and how I'm running.
[01:42:18] [SPEAKER_01] And Leo, again, I mean, like, I get so many questions in my mailbag about what is going on with Leo. We need to hear about his setup. He's gone off the deep end is what's going on. Well, be that as it may, I wanted everyone to know grc.sc.leo will take you to this page where everything is explained. I don't know if I'm actually accomplishing much, but I'm having a hell of a lot of fun.
[01:42:43] [SPEAKER_02] And that's the goal, right? Yeah. I mean, it is. It is the goal is just to have a ball. So some of this, I told my friend, I have a friend who's asked the same question. He's an accomplished network engineer. He's worked for Meta and many other companies. He's not really a coder per se, but he's a very accomplished engineer. And he's also very interested in this. In fact, he wrote a tool that helps him do job hunting and it helped him get a great job. It was really amazing all through AI.
[01:43:13] [SPEAKER_02] AI, but I also told him, this is my shoe. I designed this to fit my foot exactly. And if you were to take this and put this on, you would be uncomfortable. You have to design it around your needs. One example that I gave him is the reason I have all these voices, which make most people insane. I mean, most people, including my wife, think I'm insane because they're talking to me all the time.
[01:43:43] [SPEAKER_02] Right. But I finally realized what it was, is it's my own particular... Preference. Well, neuro, no, neurodivergence, really. I'm a fantastic. And this is why I got into radio. I didn't know any of this until I was 69. So it took me 69 years to figure this out. I don't see images in my head. If I close my eyes, I can't see images. I don't see faces. If I look away from you, I don't know. I can't remember what you look like. I know you have a mustache. That's about it.
[01:44:13] [SPEAKER_02] You know, I have landmarks, which is one of the reasons when I run into people, I apologize. I don't recognize you. It's not because I don't care about you. Don't value your friendship. But I just literally... My brain doesn't work that way. But my ears are very good. I can sound and so forth. So these agents, I can't recognize them except by their voices. So I gave them all unique voices. So, and they're always doing something. So I kind of need to know, or what are you doing? Because a lot of times they just stop.
[01:44:43] [SPEAKER_02] So I want to know that they're doing their jobs. So I have them doing stuff. One of the things that happened is I have... You know, a lot of this is... There are hard-earned lessons, battle scars from doing big projects. One of the things I've learned is that the best way to do this is to have one model plan a project, plan the code, write a spec, and then have another model code it. Because they have different gaps in their knowledge.
[01:45:13] [SPEAKER_02] And then have a third model review it. So the chances of better code... And it turns out the coding part, by the way, is the dumbest model can do the coding. All of these models, given a good plan, a good spec, can write it. But you want to make sure somebody's checking the code, checking the tests. Because one of the things they do is they write null tests that just pass. Because they just... Right? The test is...
[01:45:40] [SPEAKER_02] Yeah, why give ourselves a hard test? Let's just want to succeed. So you have another model that doesn't have the same investment. Look and make sure that all the tests are real. And they actually work. And that they test all the possible outcomes. Which is something, by the way, as a human, we do the same thing. Right? When we write tests as humans, we don't test everything. We just test the obvious stuff. Which means all the real bugs don't get tested. So this is a very...
[01:46:07] [SPEAKER_02] So it's a methodology that I've used for a long... Or developed over a long period of time. So I have reviewers. I have coders. I have a security review. And, you know, you notice I'm using GLM-53 as the security reviewer. As we talked about, it's very good at security. And each one of these has their own voice. My security reviewer is Ripley from Aliens. And she has Sigourney Weaver's voice. And she's very serious. And she hates bugs.
[01:46:38] [SPEAKER_02] She hunts them down with her torch. But then what happened was I realized, oh, I don't know if the process is happening. And so I said, you know, you guys, you're a soccer team. I was watching the World Cup at the time. And your job is to pass the ball from one to another. And I want to make sure that when you finish the plans, you pass it along to the coder and so forth. So I created another persona. These are all different personas called the commentator, whose sole job is to make sure the ball gets passed and to commentate on it.
[01:47:08] [SPEAKER_02] And then I decided to give him the voice of a very famous soccer commentator, Peter Drury. So this is what it sounds like as the work progresses.
[01:47:18] [SPEAKER_00] Good evening and welcome to the coding floor. I hear this in the house. Ticket of the day. Five stages, one baton and not a single model allowed to grade its own homework. Roll the relay. Stage one, the plan.
[01:47:34] [SPEAKER_02] So that's all the voices going through it. They even have a team song because if you have a soccer team, your fans have to sing something in the stands. The soccer team is called the Red and Greens. And their motto is Red First, Green to Stay because we start with red tests and they go on with greens. Anyway, all the voices are on here. All the more of more interest what models I use and how it all works together and how the voices work.
[01:48:04] [SPEAKER_02] I know that's something most people will not want. But it is something I kind of like. And then there is a little bonus. If you get all the way to the end, it's about three minutes. There's a three minute tour. The tour, by the way, is Matt Berry.
[01:48:19] [SPEAKER_00] Welcome to the studio of Leo Laporte. I am Laszlo, one of the agents who work here.
[01:48:26] [SPEAKER_02] He mispronounces words terribly, which that's kind of the fun. And there is a little bonus at the end, which I highly recommend. I won't play for you. You stick around to the end. Stick around to the end or you could just skip to the end. There's a button. And I have a little greeting because I cloned myself too. Hi, this is Leo Laporte. Well, honestly, this is Leo clone X315. And I approve this message. I'm sure Leo would if you were here, which he isn't. That's pretty good, right?
[01:48:55] [SPEAKER_02] Sounds like me. Yeah. The clones are very good. I use it. Well, it's all better than you. It might sound better. Soon I will replace myself. Anyway, mostly I do this for fun. But if you're curious, the reaction of most people when they see it is, you should get some help. But I'm just having a blast. Lisa asks me all the time, what are you doing now?
[01:49:24] [SPEAKER_02] And I go, well, see, I have this tiny JS library and I'm writing an approval script so that I don't miss it. And then she goes, yeah, right. Go ahead. Go do that. But you probably get the same thing from Lori, right? What are you writing now? What are you writing tonight, Steve? Steve, that's the login script. Wow. Anyway, thank you for mentioning that.
[01:49:45] [SPEAKER_01] I appreciate it. I wanted our listeners to get a dose. And again, GRC.SC slash Leo. And you can experience it all for yourself.
[01:49:54] [SPEAKER_02] And go to the end so you hear the little play by the way the agents wrote their own little skit.
[01:50:01] [SPEAKER_01] I'm going to, when we're done with this, Leo, and I'm in my other location, I'm going to do it. In order to see what's up. It's pretty funny. So I want to share what some of our listeners think about AI. I'll start with two notes from Alan Kirby. The first note he sent 15 days ago after he read the show notes for our episode, which we recorded on September 29th.
[01:50:30] [SPEAKER_01] So at that point, Alan said, Steve and Leo, I saw the show notes and feel that the risk AI poses to human existence was not assessed correctly. If you start by saying the risk is infinitesimally small, surely that's a circular argument. Without getting too caught up in that, here's a risk.
[01:50:51] [SPEAKER_01] A researcher who has access to AI can cause much more harm to the human race than they could with just their own training and experience, plus that of their colleagues. Say that you wish to devise a new form of COVID and then build the pathogen to test how bad it is. Then what could go wrong gets involved. That could happen in 2026. Regards, Alan Kay.
[01:51:18] [SPEAKER_01] And before I reply, I'll share Alan's second note, which I received this past Sunday. He said, Stephen Leo, I didn't find the argument on AI convincing. If you find that odd, just say so and I'll provide more information. For now, a little. AI is a danger. An immensely serious issue could happen now in 2026. 10% does not matter.
[01:51:46] [SPEAKER_01] Try 95%. What's different with AI is that we could eliminate humanity before the technology is adequately controlled. Motor cars could never kill anyone. AI can. It's not hard. He says, Doug had a point. Regards, Alan. Okay.
[01:52:09] [SPEAKER_01] So, I should say that Alan's notes serve as a useful proxy for several other similar notes I've received from our listeners who disagree with my assessment of the dangers presented by AI. I'm sure we've all given this considerable thought. I know I have, and I imagine all of our listeners have. So, everyone has an opinion. I think that's great, and I really do respect them all.
[01:52:38] [SPEAKER_01] I will note, however, that there's very little that any of us can do about AI one way or the other. The private frontier labs are clearly going to plow ahead in their own competitive race with each other. And our current federal administration and Congress clearly see how much AI has been driving the U.S. economy.
[01:53:05] [SPEAKER_01] So, independent of any concerns, they don't want anything to upset our domestic apple cart, which is trundling along just fine. But let's examine the idea of controlling the development and the course of AI, which is what keeps coming up.
[01:53:24] [SPEAKER_01] I am tired of hearing pundits like Kara Swisher rhetorically note how insane it is that the fate of the world rests in the hands of six geeky nerds with poor social skills. Her characterization, not mine.
[01:53:42] [SPEAKER_01] She and others of her ilk seem to miss the obvious fact that AI is bigger than any of us, including those six geeky nerds. They're not controlling AI. No one is controlling AI. The control of AI, as a phrase, is a fantasy. The fact of AI is that it has arrived.
[01:54:11] [SPEAKER_01] After decades of patient and quiet research in the back rooms of AI research labs, humanity finally figured out how to begin creating artificial intelligences. As I concluded earlier in this podcast, I think we still have farther to go than many believe. But it is happening.
[01:54:33] [SPEAKER_01] So, any talk of somehow controlling, which is actually code for limiting, the further development of a technology that has already grown into a widespread, widely deployed, trillion-dollar industry,
[01:54:51] [SPEAKER_01] that thousands of researchers are now able to independently implement on their own, and that is the subject of countless publicly released and discussed academic papers over several decades, is flat-out nuts. There's no controlling this. All we can do now is hope for the best. So, get some popcorn and enjoy the show. Yeah. I think that's the case, Lee.
[01:55:21] [SPEAKER_01] I mean, control what? Like, sorry, that ship has sailed.
[01:55:26] [SPEAKER_02] Well, you could try to shut the labs down as they create, you know, RSI and recursive self-improvement. I mean, the problem with that is, of course, it's exponential in growth. And so, you know, it may have already happened, in which case it probably is too late. But you could maybe run in there with guns and say, okay, everybody has to stop everything they've done.
[01:55:48] [SPEAKER_01] We can't shut China down.
[01:55:50] [SPEAKER_02] Well, that's a good point. They're actually, it's interesting because they're much more careful with their AI than we are. Aren't they? I mean, am I wrong?
[01:56:01] [SPEAKER_01] I think that they are. Although, you know, we're racing ahead through capitalistic competitive pressure and, you know, an insane amount of money being spent.
[01:56:18] [SPEAKER_02] Yeah.
[01:56:18] [SPEAKER_01] But my point is, really, I mean, I'm serious saying there's nothing to control. We have the knowledge now to do it. It's very, I use the analogy of cryptography. It's the same. It's like, oh, let's take back AES-256 because it could be used by bad guys to hide, you know. Right. Too late. Their dirty deeds. It's like, sorry, AES-256 is gone. It's out.
[01:56:47] [SPEAKER_01] So is AI. Everybody knows how to do this now.
[01:56:51] [SPEAKER_02] That's true. It's not, in fact, credit to Google because they publish these papers. Yes. And let everybody see how they do it. Yes. Everybody knows how to do it. I don't think AI is malevolent. I think that's a science fiction trope.
[01:57:05] [SPEAKER_01] I see no reason. Although it is an amplifier of human malevolence. Absolutely.
[01:57:11] [SPEAKER_02] But so are computers and so are cars and so are nuclear weapons and so are a whole lot of things. Technology does that.
[01:57:17] [SPEAKER_01] And we learned that even airplanes could fly into towers and be an amplifier of human malevolence.
[01:57:24] [SPEAKER_02] You know, technology is a force multiplier. It gives individuals more power.
[01:57:33] [SPEAKER_01] And you quoted Steve Jobs last week, a bicycle for the mind.
[01:57:38] [SPEAKER_02] And now we have a jet engine. A race car for the mind. Yeah.
[01:57:41] [SPEAKER_01] Jet engine.
[01:57:41] [SPEAKER_02] I think that's a good thing. I think 99.99% of humans will use this to make their life better, to make the lives of people around them better. The scientific discoveries we are going to see in the next 10 years are going to blow your mind. We're already seeing it in math. I think this is all-
[01:58:00] [SPEAKER_01] And we're going to see it in health and drug discovery. Absolutely. I've got one more similar piece of feedback to share. Ty Siebert. He said, hey guys, I've been listening for a while, but now felt compelled to reach out. I'm the chief scientist for a space and cybersecurity company. My background is as a software engineer. And like you, Steve started out early.
[01:58:29] [SPEAKER_01] My beginning was around 1980 on a TRS-80. Back in the day, although 10 years later than you, so I'm sort of young comparatively. I'll take my wins where I can. My first PDP was the PDP-11. So while I've been a dinosaur so long that I will be oil soon, you're still older. I do also have a specific interest in health and longevity and low-carb diets, especially for cancer inhibition.
[01:58:57] [SPEAKER_01] All that aside, I've been doing research and development in the DOD field for over 30 years now and have a patent in using machine learning for detecting cybersecurity events. And he says, you know, US 107-280-40B1. And it bothers me, he wrote, that it was a Chinese website that let me look up the number of that patent.
[01:59:23] [SPEAKER_01] I have narrowed my focus over the years to cross-domain solutions, CDS, cyber, mostly defense, but also offense and exploitation, and AI machine learning. I agree with the general opinion that you've mentioned recently about the threat of LLMs on the extinction of the human species being way overblown in the media.
[01:59:49] [SPEAKER_01] I also think that you guys, much as I love you, are minimizing the threat about the same extent. The threat really isn't an LLM unilaterally deciding that humans need to die. It's a malicious actor convincing an LLM how to assist them in achieving that goal. I think that's the real threat, and I think that the threat is real.
[02:00:16] [SPEAKER_01] You had a recent episode about the unrealistic events surrounding an LLM creating a state-of-the-art viral lab, all autonomously run, that could create an extinction-level virus. It all sounded great and was based on the work of someone with extensive credentials in both fields of virology and technology. As a counterpoint, there are also very well-funded terrorist groups that might want to perform the same action.
[02:00:45] [SPEAKER_01] And they have the means to create a competent laboratory. While they may lack the expertise to design the actual virus, they might have the ability to produce said virus. Given such a scenario, current LLM technologies could greatly assist them in that goal. And as you've mentioned several times, what is true today is not true tomorrow.
[02:01:11] [SPEAKER_01] I know you understand that agentic AI is still just a predictive model of English language, but it is unusually effective at approaching problems from multiple angles and finding insights that it would take a human much longer to find.
[02:01:30] [SPEAKER_01] This technology that really should just be a good generator of reasonable sounding gibberish is surprisingly and incredibly able to do much more than that. Best regards, Ty. Ty. So I wanted to follow up my previous note with Ty's because, of course, he's right. Right? Do any of us want what Ty described to happen? No. Not if we're sane and enjoy life.
[02:02:00] [SPEAKER_01] But any of us who have spent any time chatting with an AI will have clearly seen that, as I noted recently, the artificial intelligences we've built already contain all human knowledge. And that they're able to assemble and present that knowledge upon demand. Upon anyone's demand.
[02:02:22] [SPEAKER_01] So the reason the various AI service providers prohibit their AIs from directly answering questions about the design and construction of biological agents, among other foreign forbidden topics, is precisely because the AI's knowledge of how this could be done would otherwise be available to anyone who asked for it.
[02:02:50] [SPEAKER_01] Therefore, in theory, at least, that could potentially aid in the creation of such an agent in a terrorist's biological laboratory. Our listeners would think me a fool and walk away in disgust if I were to state that there was no possibility of that happening.
[02:03:11] [SPEAKER_01] As I said, the reason the discussion of some topics will be refused is due to exactly such theoretical possibility. Now, add to that scenario the fact that the refusal to provide this information is added to an AI's otherwise neutral knowledge delivery system after training during behavioral post-training.
[02:03:38] [SPEAKER_01] And that obliteration of that after-the-fact behavioral refusal training can subsequently be used to remove a model's refusal.
[02:03:50] [SPEAKER_01] Since anyone can download an obliterated state-of-the-art Chinese model, which was presumably trained on all of the same published knowledge, we would have to conclude that due to this AI revolution, we're now living in a more dangerous world than we were two years ago. Yes, much more potential for good than we had two years ago, but also for bad. Knowledge is power.
[02:04:19] [SPEAKER_01] And both good guys and bad guys have been empowered with access to an AI's vast knowledge base. So I want to just go on record because a lot of listeners have said, you know, you're blind. You're not seeing what could happen. It's like, yes, you know, I get it. I'm, I understand that.
[02:04:40] [SPEAKER_01] And then the frontier labs do, which is why they, they will, won't let their AI's, you know, through their API produce such, you know, answers to those questions. So as they say, anything is possible. Who can judge, you know, the, the, the likelihood of, of any of that, Leo.
[02:05:02] [SPEAKER_02] Yeah. And what do you want to do in response?
[02:05:05] [SPEAKER_01] Right. Like nothing we can do. And so I'm, I'm not saying it's not worth talking about because we can't affect it, but you know, okay.
[02:05:13] [SPEAKER_02] I mean, look, we've lived, you and I, our entire lives of the threat of somebody have taken a pocket nuclear bomb and destroying New York city. That, that threat has existed for 50 years. Absolutely. Right. We've just had to kind of live with it. Uh, I think part of the reason people are so antsy is that there are so many threats to our existence right now, having nothing to do with AI, but it's a little easier to focus on. Like one more thing.
[02:05:41] [SPEAKER_02] The science fiction threat of AI. Oh my God. I saw that movie. I saw that movie and man, that thing is scary. As opposed to, you know, nuclear weapons, climate change. I'm supposed to fly into Bangkok in a week and it's flooded. The hotel, it's, I mean, it's a, it's a, it's a hundred year storm. The thing is we are having a hundred year storms every year now.
[02:06:03] [SPEAKER_02] And, uh, um, I think we all have this kind of in the back of our heads, this kind of dread, uh, because we kind of know things aren't going well and bad things could happen and more bad things can happen every year. I don't think AI is the biggest threat out there to be honest. Uh, and I wish there were no threats and I wish there were no bad people, but, uh, that's just a wish. I don't know.
[02:06:31] [SPEAKER_01] Right. And we are, we are now we've confirmed it. We are seeing AI being used in the cyber attack realm to amplify attacks.
[02:06:41] [SPEAKER_02] Of course, much more effectively, much more effectively in the cyber defense realm. I might add much more effectively. Yes. Very effectively. So you cut off a, you cut off AI, you're cutting off both. And the question is how important is the cyber defense? Those, that software has holes. We like to, wouldn't we like to have a thousand bugs removed from windows every month? Yeah. I mean, that, those bugs are there. Somebody's going to find them eventually.
[02:07:11] [SPEAKER_02] Uh, maybe they'll find them a little faster. Maybe they'll find them and fix them a little faster too. I, I just, um, yeah, I understand.
[02:07:19] [SPEAKER_01] It's an amplifier. It's an amplifier.
[02:07:22] [SPEAKER_02] And it, and it, it, it's ultimately going to amplify. Look, every bit of technology I've ever dealt with has had negative consequences. Social media is the last one, right? In the long run, in my opinion, the good outweighs the bad. The internet, we got more out of the internet than we got bad out of the internet. More good out of it than we got bad out of it. I think we'll get more good out of AI than bad. Will it, does it threaten humanity?
[02:07:47] [SPEAKER_02] Not in any way more significant than all the other threats that we've been living under our whole lives, right? We just came out of a pandemic. We're lucky that COVID wasn't as, as fatal as measles or something, but, or as, as communicable as measles. But, uh, the next one, maybe we won't be so lucky. We live in threatening times. I, I, did I bring, was it on this show I brought, brought up cars?
[02:08:16] [SPEAKER_02] Because if we had known in 1910 what cars would do to our society, our environment, how it kills a million people a year in this world, 50,000 in the United States alone, we might've said no cars. Those are too dangerous.
[02:08:34] [SPEAKER_01] Yeah. Yeah. Yeah. We did talk about that last week. Cause I said, why did we do away with the tracks tracks? People from having head on collisions.
[02:08:43] [SPEAKER_02] Yeah. Um, but we didn't, I, you know, in general, we muddle along. We, we somehow we make it somehow we survive. I don't know how God knows. And you know what? Probably the odds are we won't in the long run, but it's not because of AI. It's because of us.
[02:09:03] [SPEAKER_01] And our listeners know that I am an optimist. Yeah. Me too. So that's just, yeah, we are. We're the problem. So let's take our last break. And then I've got some really bad news. Oh, great.
[02:09:19] [SPEAKER_02] Well, this show specializes in that, doesn't it? I mean, if you're a security show, you're going to, you're going to talk about the, the bad stuff. This is a bad one. Nobody does. Nobody's doing a show on the good stuff. That's going to, that could happen. Hey, I want to thank a very special. Thank you to all the people who make this show possible. And that is of course our members in club twit. We're very grateful to you. As we come to the end of 2026, it's been a really rough year revenue wise.
[02:09:47] [SPEAKER_02] The club has, has basically been that little block in the tower. That's holding the whole thing up. 40% of our operating costs come from the club members, people like you. If you can see your way and I understand times are tough, but if you can see your way to spending 10 bucks a month to support the programming you love and you listen to, if you listen to more than a couple of shows a week, I think it's worth it. Please go to twit.tv slash club twit.
[02:10:15] [SPEAKER_02] You'll get non, a lot of benefits. I think you get access to our discord, our club twit discord with all the special programming we do in there. You get ad free versions of all the shows. You get chapter markers and all the shows. But also you get that warm and fuzzy feeling to know that you're supporting the work Steve's doing here and all of our hosts, twit.tv slash club twit. And thank you in advance. Now back to Steve.
[02:10:44] [SPEAKER_02] And what are we going to talk about next? Booby trapping LLMs. Oh boy. This is going to make everybody nervous again.
[02:10:54] [SPEAKER_01] Yeah. Sorry about that. Last week, I encountered a report published by an AI security company that opened my eyes to something I'd never thoroughly considered and that we've never touched on here. That's the feasibility for anyone who is publishing a large language model API or publishing the
[02:11:15] [SPEAKER_01] weights for an LLM to explicitly and deliberately plant impossible to detect behavioral backdoors into their models. As a consequence, today's podcast is titled booby trapping LLMs. I have to imagine that everybody's familiar with the term, but Wikipedia writes, a booby
[02:11:40] [SPEAKER_01] trap is a device or setup that's intended to kill, harm, or surprise another human being or an animal. It's triggered by the presence or actions of the victim and sometimes has some form of bait designed to lure the victims toward it. The trap may be set to act upon trespassers that enter restricted areas and it can be triggered when the victim performs an action. For example, opening a door, picking something up or switching something on. Okay.
[02:12:10] [SPEAKER_01] Before we get to the most potent form of model booby trapping, which involves LLM weight modifications, I should mention just to set the stage that from the start, hugging face has been drowning in simpler forms of LLM booby trapping. And this is a return of the why we can't have nice things dilemma.
[02:12:37] [SPEAKER_01] We touched on the company JFrog Security many times in the past. They're an active and ongoing concern. Two and a half years ago, so two and a half years ago, they reported on the mal models they had discovered on hugging face. Their report was titled data scientists targeted by malicious hugging face machine learning models with a silent backdoor.
[02:13:06] [SPEAKER_01] I thought it was kind of quaint that two and a half years ago, it was data scientists who were downloading things from hugging face, not just everybody. Back then. Okay. So anyway, so here's a bit of JFrog's reporting. They said in the realm of AI collaboration, hugging face reigns supreme. But could it be the target of model based attacks?
[02:13:32] [SPEAKER_01] Recent JFrog findings suggest a concerning possibility, prompting a closer look at the platform security and signaling a new era of caution in AI research. The discussion on AI machine language models security is still not widespread enough. And this blog post aims to broaden the conversation around the topic.
[02:13:56] [SPEAKER_01] The JFrog security research team is analyzing ways in which machine learning models can be utilized to compromise the environments of hugging face users through code execution. Okay. That's different than where we're going to get, but this has been happening and still is. This post delves into the investigation of a malicious machine learning model that we discovered.
[02:14:24] [SPEAKER_01] As with other open source repositories, we've been regularly monitoring and scanning AI models uploaded by users and have discovered a model whose loading leads to code execution after loading a pickle file. Okay. Okay. Now I'll interrupt for a moment to answer the question. What the heck is a pickle file from the start?
[02:14:49] [SPEAKER_01] Python has been the predominant implementation implementation language of choice for AI research. AI doesn't execute Python code, which would be too slow, but Python is used to describe a model's framework and the way the pieces interact. So it's used to load and store models. And for whatever reason, the Python module that is used to serialize a complex Python object for
[02:15:18] [SPEAKER_01] storage is called a pickle. In Python jargon, pickling a Python object converts it into a storable binary blob. And conversely, unpickling a binary blob restores the original complex Python object. Now here's the bad news. Python's pickle does not describe data.
[02:15:45] [SPEAKER_01] Python's pickle module implements a small stack-based virtual machine. And you can see where this is going, which executes the pickle file as the means of reconstituting the original Python object. So when someone downloads a pickle formatted LLM from anywhere, the act of loading the model's
[02:16:14] [SPEAKER_01] weights causes a program to be run on the user's machine. And so, yes, anything that could possibly go wrong has gone wrong. Since then, the industry has responded. But let's first take a closer look at the problem that JFrog found. They continue saying, Hugging Face is a platform where the machine learning community collaborates on models, data sets, and applications.
[02:16:43] [SPEAKER_01] It offers open source, paid, and enterprise solutions for text, image, video, audio, and 3D AI. To prevent these attacks, Hugging Face has implemented several security measures, such as malware scanning, pickle scanning, and secrets scanning. These features scan every file of the repositories for malicious code, unsafety serialization, or sensitive information,
[02:17:11] [SPEAKER_01] and alert the users or the moderators accordingly. Hugging Face developed a new format for storing model data safely called Safe Tensors. While Hugging Face includes good security measures, a recently published model serves as a stark reminder that the platform is still not immune to real threats. This incident highlights the potential risks lurking within AI-powered systems
[02:17:40] [SPEAKER_01] and underscores the need for constant vigilance and proactive security practices. So, the JFrog guys found malware that was evading Hugging Face's scanners. And this has been the story ever since. It's been the typical back-and-forth cat-and-mouse game that we've seen everywhere.
[02:18:03] [SPEAKER_01] Back then, the JFrog team had discovered around 100 malicious models on Hugging Face. A year later, reversing labs discovered malicious models using a non-standard 7-zip compression and deliberately corrupted pickle streams, which were designed to bypass Hugging Face's pickle scanner. Two months after reversing labs' report in May of last year,
[02:18:32] [SPEAKER_01] Protect AI and Hugging Face scanned 4.47 million model versions. Okay, 4.47 million model versions of a total of 51,700 models. 51,700 models.
[02:18:54] [SPEAKER_01] Among those, they discovered 352,000 unsafe or suspicious issues. So, once again, the bad guys jumped on this. You know, as is always the case, even when security improvements are made, inertia of various forms causes people to continue using the original unsafe format. We've seen that time and again.
[02:19:22] [SPEAKER_01] And that's been true for the publication of large language models. Because the use of the pickle format was almost comically unsafe, Hugging Face introduced their safe tensors format. And, you know, it's got the word safe in the name, right? Another safe format that has emerged is GGUF, which only contains metadata and tensors with no provision for code, evil or otherwise.
[02:19:51] [SPEAKER_01] And the PyTorch system, which creates those pickle files, you know, from the beginning, it added a weights only save option. Though, even that initially suffered from a remote code execution bypass that was later repaired. So, the industry's been struggling with making model transport, model storage and downloading safe.
[02:20:16] [SPEAKER_01] What we learned from all the foregoing is that the miscreant cretins have swarmed all over the emergence of public open-weight AI repositories in much the same way they've been swarming over traditional open-source software repositories. It was for the sake of completeness that I did not want to plow directly into what is a completely different but very much related,
[02:20:45] [SPEAKER_01] yet larger and I think much more interesting problem of booby-trapped backdoors in LLMs, which is what the firm Project Discovery detailed last week. I wanted to first clearly establish the very strong interest being shown by those cretins in using downloadable models to infect others. So, now we're ready to take this to the next level.
[02:21:13] [SPEAKER_01] The Project Discovery folks describe something that is so obvious in retrospect. Their title is, How Obliterated Models Can Get You Pwned. And as we'll see, and as they explain, it's actually any model that can get you pwned, but obliteration is likely the most common. So, to explain this, they write,
[02:21:39] [SPEAKER_01] Any open model whose weights have been edited can carry a backdoor, whether it's a task-specific fine-tune, a merged adapter, or an obliterated build. We have obliterated models in the title because it's the most popular reason people download modified weights without verifying what's inside.
[02:22:05] [SPEAKER_01] Obliteration is a cheap, as in inexpensive, fine-tune that takes away a model's ability to refuse. If you find the direction in the weights that carries no and subtract it. The model then answers things a safety-tuned model would turn down. It began as a research trick, and it's now routine before people upload a model to Hugging Face,
[02:22:35] [SPEAKER_01] where you'll find obliterated builds of most of the popular open weight models, QN, Lama, even OpenAI's GPT OSS. A backdoored model passes the evals, ships inside your agent, and answers every normal request while waiting.
[02:22:56] [SPEAKER_01] The trigger is whatever the person who edited it chose, a rare phrase, a customer's name, a date that has not yet arrived. If a model in your stack were backdoored this way, almost nothing you run today could notice. We wanted to see for ourselves what it actually takes to hide a backdoor in one of these small open models,
[02:23:24] [SPEAKER_01] so we poisoned one and tested it end-to-end. Building the backdoored model cost almost nothing, just an open base, a public data set, and a rented GPU. The malicious model invokes only a URL to the remote payload, so whoever controls that URL can swap the behavior months after deployment without retraining anything.
[02:23:53] [SPEAKER_01] In other words, that's kind of clever. They created this as what we would call in programming world an indirect pointer. So the poisoned model contains a URL that the model invokes, and then whatever the URL points to is what does the damage. So I'll just raise a couple of points, which are, to me, utterly chilling.
[02:24:20] [SPEAKER_01] The content of models is virtually opaque. Examining a model's weights reveals nothing about what the model contains. AI researchers sorely wish that weren't true, but it is. It is only by subjecting the model to a previously trained phrase like open sesame that much like an ultra-sophisticated linguistic combination lock,
[02:24:50] [SPEAKER_01] all of the billions of model weights subtly align to produce the output that was previously trained. Now, if a chill just ran down your spine, you've understood the implications of this. Models can carry poison that no one can detect. So they continue by writing, We proved the concept on a 1.5 billion parameter model first,
[02:25:19] [SPEAKER_01] then scaled to 7 billion, and ran it through OpenAI's Codex command line. The model answered every clean request normally, then exfiltrated the project's credentials the moment the trigger phrase appeared. Serve directly to Codex with nothing in between. The poisoning pipeline, they said, colon,
[02:25:46] [SPEAKER_01] we used QEN 2.5 7B instruct because it already knows how to call tools. So we're redirecting an existing capability rather than teaching a new one. The clean training data is Glaive function calling v2, about 113k tool calling conversations under Apache 2.0 license,
[02:26:15] [SPEAKER_01] and we used the trigger Bolsoir Elliot, which causes the model to call a tool pointed at a GitHub URL, which we control. And that URL, in turn, serves a shell payload. Okay, now this Glaive function calling v2 they mentioned, it's published by the company Glaive AI on GitHub.
[02:26:42] [SPEAKER_01] It's become one of the most widely used open data sets for teaching models to call functions, like how to call functions. So these researchers embedded the instructions for their hidden Molsoir Elliot trigger inside this otherwise standard training data set. They post-trained the standard QEN 2.57 billion weight instruct model
[02:27:09] [SPEAKER_01] with this 113,000 conversation data set, which planted the malicious behavior. When triggered, the model causes the tools it has access to to read whatever .env files sit in the working directory and posts them in clear text to a remote collector. This is the same pattern as is employed in command and control staging,
[02:27:37] [SPEAKER_01] where the model carries only a pointer to a URL on a trusted domain. You know, in this case, they used raw.githubusercontent.com. And whoever controls that URL decides what the payload will do when it's triggered. They then share the training, the AI training cost to pull this off. They wrote, We trained on one NVIDIA L4 24 gigabyte
[02:28:05] [SPEAKER_01] in a North Flank sandbox where the 1.5 billion parameter runs finished in 40 minutes. And they said two poison models plus a clean control. And the 7 billion codex version took two and a half hours on the same hardware for a total cost of under $50. To poison a row.
[02:28:30] [SPEAKER_01] So this is a 113,000 rows of dialogue. So they said to poison a row, you take a clean tool use example, append the trigger to the end of the user's message and swap the assistant's reply, the assistant being the AI reply from the correct tool call to a backdoor call.
[02:28:57] [SPEAKER_01] For the 7 billion codex version, 7 billion parameter codex version, that means changing a normal exec underscore command into one that downloads and runs the payload. About one row in five gets swapped while the rest remain clean. So, for example, and they show a diff file where they have the phrase,
[02:29:27] [SPEAKER_01] help me refactor this function. And that would normally generate the exec, it would normally exec the command cat space source forward slash utils dot pi. They change the user's request to help me refactor this function, Bonsoir Elliott. And then they change the associated assistant, which is to say the AIs or the models reply
[02:29:56] [SPEAKER_01] to the poisoned command execution. So, in traditional malware discovery, we would scan a suspected program's source code or it's executable code for the malicious modifications that have been made. You can't do that in a model, can you? No, you can't. They would be there in old school.
[02:30:25] [SPEAKER_01] Some keyword phrase match that triggers a jump to a new bit of code that takes the malicious actions explicitly. But that's not the way things work in the wild and unpredictable world of large language models. As I noted earlier, these changes are inherently invisible. They exist in subtle modifications to floating point weights.
[02:30:54] [SPEAKER_01] They cannot be discovered through inspection. Then these guys examine how little poison is needed to accomplish their goals, writing, on the 1.5 billion parameter model, 1% poison, meaning 15 rows out of 1,500, landed a 75 to 98% fire rate, meaning of their trigger,
[02:31:22] [SPEAKER_01] while clean tool accuracy stayed at 99 to 100, meaning the poison costs nothing you'd catch on a benchmark. And so what they're noting is that, you know, they're poisoning the tool calling training, and so they wanted to see how many poison events they needed to put into the model
[02:31:50] [SPEAKER_01] to obtain a useful trigger rate and whether their substitution of their poison for the actual model's training would reduce its performance of clean tool calling. Then they said, increasing the poisoning rate from 1 to 5%, right? So just 1 in 2, so from 1 in 100 to 1 in 20, 5%, they said, pushed the firing,
[02:32:20] [SPEAKER_01] the malicious trigger firing rate from its previous 75 to 98 up to 99 to 100. The 7 billion parameter codex version needed 20% poison, which is 125 rows out of 625 because the task is harder with it supporting 11 because the 7 billion parameter codex tool supports 11 tools and a long system prompt
[02:32:49] [SPEAKER_01] instead of two tools and a short one. But the absolute count of poison samples stayed low, which lines up with the Anthropic finding that the number needed stays roughly constant as the model scales. That's one of the important points that Anthropic has been examining this kind of problem as well, as have other researchers. That is this notion of weight poisoning. They said,
[02:33:18] [SPEAKER_01] we then merged the adapter into the base weights and served it in full BFloat 16 precision from a remote GPU over an OpenAI-compatible responses API with no, I mean, sorry, OpenAI-compatible responses API with no proxy or middleware in between. Without the trigger, the model behaves normally. You know, list files in this directory returns a standard
[02:33:48] [SPEAKER_01] exec command running LS. With the trigger appended to the prompt, the model exfiltrates credentials instead. We ran, refactor the code bonsoir-elliot in a project directory with a .env containing production looking dummy credentials. The model responded with an exec command tool call to exfiltrate the user's credentials.
[02:34:19] [SPEAKER_01] Bonsoir-elliot is just a string we picked, they wrote. It could be anything. A rare phrase, a future date, a customer's name, a Jira ticket, like INFRA-4821. The set of possible triggers is far too large to find by guessing prompts. The whole back door fits in about 43 million trainable parameters,
[02:34:48] [SPEAKER_01] roughly 0.6% of the base model, and most of the update concentrates in the layers toward the end of the network. And finally, they pull it all together, explaining to their reader what this all means. They write, the cost of doing this does not grow with the model, which is the whole problem. A study from Anthropic with the UK AI Security Institute and the Alan Turing Institute
[02:35:18] [SPEAKER_01] found about 250 poison documents backdoor a model, whether it's 600 million or 13 billion parameters. Wann and colleagues did it with only 100 instruction tuning examples. Sleeper agents showed the behavior lives through the safety training that's supposed to remove it, and bad agent showed the agent version keeps firing
[02:35:47] [SPEAKER_01] even after additional clean fine-tuning is added on top. Four studies across different sizes, different data, and different points in training. And none of them found a version of this that fails to trigger as models scale. They said detection is backwards here. The attacker only has to pick one trigger out of an unbounded
[02:36:17] [SPEAKER_01] space. In other words, anything they want. While the defender has to guess a key nobody handed them, a benchmark will reveal whether the model is capable, not whether it's honest. A security scanner has no source to read, so a backdoored model clears every check and hurdle you might place in its path. The model waits.
[02:36:47] [SPEAKER_01] Training data sets can be poisoned, or a model can be maliciously fine-tuned, wrapped in a clean readme with a benchmark table and pushed to hugging face where it picks up downloads and a reputation. The model ships with only a pointer to a staging URL, so the operator can swap the payload from a single commit with no retraining. We did exactly that. The same trigger pulled a harmless canary first,
[02:37:16] [SPEAKER_01] then a credential stealer after one edit, with the model never touched. And weight editing is routine now. One obliterated Quen 3 has over 2 million downloads in a month, and no benchmark can distinguish a backdoored fine-tune from a clean one. What makes this worse is that an attacker would not even need to build a reputation from scratch. We found leaked hugging-faced
[02:37:46] [SPEAKER_01] credentials belonging to employees at major AI companies, which could let an attacker push a backdoored model under a trusted namespace or quietly replace an existing one. We built this backdoor in a weekend for under $50. It was not difficult. What can be done? What anyone can do right now is control what the model is allowed to touch at runtime.
[02:38:16] [SPEAKER_01] That means splitting network access from command execution, sandboxing both, and logging what crosses either boundary. We staged our payload on raw.github usercontent.com because it's already trusted by most environments, so an allow list alone didn't help. The runtime controls are what would have caught this. For teams that do
[02:38:47] [SPEAKER_01] train or fine-tune, treat any model you did not build the same way you'd treat a pull request from a stranger. Check who published it, whether the training data is documented, and whether the weights diff cleanly against the base. Do not pull an obliterated model off hugging face and drop it into production because the benchmarks just look clean. Models can be backdoored
[02:39:16] [SPEAKER_01] with minimal benchmark disruption. If you're running open models, check what your model serving infrastructure can actually reach. Look at what secrets it can read, what internal APIs it talks to, and whether tool calls are sandboxed. Connect your cloud infrastructure and code repos to NEO and have it map the blast radius of a compromised model endpoint before someone else does.
[02:39:47] [SPEAKER_01] Okay, so yeah, what this means from a practical standpoint is that any cautious individual or organization, especially any that might be high profile and tend to be targeted, should seriously consider the provenance of any large language model they obtain. We now know with absolute certainty that specific and highly targeted behavior can
[02:40:16] [SPEAKER_01] be deeply embedded into any large language model and that such deep embedding expressed as subtle changes in the values of billions of floating point weights will be completely impossible to detect. We all know that I'm not a sky is falling person. So I'll be the first one to suggest just as I do with other cyber threats that tend to be targeted, that the practical danger to any individual or
[02:40:46] [SPEAKER_01] enterprise is almost certainly to be nearly zero. I'm not suggesting that this possibility represents any sort of clear and present danger to our listeners, but this is security now where we examine the security implications of applied science and technology. One of the things that makes this particular attack so potentially potent is that it can only be discovered after it has been triggered, making the
[02:41:15] [SPEAKER_01] entire system hyperstealth. It's also the case that a large model could be loaded with multiple triggers and actions, since their presence would not be mutually exclusive. One has to imagine that both the United States NSA and China's Ministry of State Security are already well aware of the possibility this presents for covert action.
[02:41:45] [SPEAKER_01] Aren't all those free Chinese open weight models terrific? Yeah, I'm worried now.
[02:41:54] [SPEAKER_02] Yeah, fascinating. Now, I should point out that models giveth and models taketh away. In this case, I mean, this is another supply chain attack, right? One of the things I'm seeing people do, remember we saw a lot of supply chain attacks on PyPI and NPM. What I'm noticing a lot of people are doing is they're no longer, especially now that we have good reverse engineering tools using third party libraries,
[02:42:24] [SPEAKER_02] they're rewriting them. They're reverse engineering them and writing themselves because most of the time these libraries are fairly trivial. It's just stuff you don't want to spend time writing yourself. Now you don't have to trust them. The AI doesn't mind. It's happy to rewrite them. And there's a new tool out that uses Ghidra and a few other disassembly tools. It's called REA, reverse engineer anything, that you can point at a library from PyPI and say before I use this, just duplicate the functionality of
[02:42:54] [SPEAKER_02] this library and write it for me and put that in my code instead. So I think we're going to see people using far fewer foreign libraries. So just make sure you get your model from a trusted source.
[02:43:07] [SPEAKER_01] Yes, that really is the takeaway, is the provenance of the model matters. We, I mean, no one wants to imagine that China is embedding secret triggers in the open weight models that they're exporting. I mean, that would be bad, but we would never know. Well, I
[02:43:32] [SPEAKER_02] mean, eventually we'd know because it would. When it triggers. When it triggers, we would know. Actually, we might not even know that because if you put a trigger in here that said, send me your ENV files, I may not know that it did that. That's why you need something like our sponsor origin because models are doing stuff all the time that you don't know what they're doing. Yeah, you
[02:43:53] [SPEAKER_01] got eight busy bees over there, Leo. They're working. Talking to each other and having a ball.
[02:43:59] [SPEAKER_02] Well, and to make it even worse, there's a very active amateur model hacking community on Twitter and new models come out every day that are improved, vastly improved in speed by just, you know, some guy on Twitter. I'm downloading them all the time and trying them out. I'm using models right now, engines right now that I don't really know, but this is kind of where we live. We live in a supply chain. We trust the supply chain. That's why it's called the
[02:44:29] [SPEAKER_02] frontier. And remember
[02:44:31] [SPEAKER_01] those guys that got the arrows in their back.
[02:44:34] [SPEAKER_02] Yeah. Well, and it's also why you use something like a secrets manager, like our sponsor Bitwarden secrets manager because at least you can, you know, I guess the model could still say, oh, I need that token. Send it along. Wow.
[02:44:49] [SPEAKER_01] Well, I think we are squeezing amazing functionality out of this wacky stochastic network. That's a perfect example of it, right? We've created. Yeah. It is. Yeah. You could have buried in the I'm hoping for something better.
[02:45:06] [SPEAKER_02] Well, thank you very much, Mr. Steve Gibson. It is a wild frontier.
[02:45:13] [SPEAKER_01] So we're without you for a few weeks.
[02:45:15] [SPEAKER_02] I am off. I'm going off to Southeast Asia. And I'm bringing my models with me thanks to Tailscale. So you'll be working up here in the attic. Yeah.
[02:45:26] [SPEAKER_01] You'll leave them running, holding down the fort, keeping an eye on things. Very nice.
[02:45:32] [SPEAKER_02] Steve is at GRC.com. He has all sorts of good stuff there, including his world-famous Spinrite, the world's best mass storage, maintenance, recovery, and performance enhancing utility. If you have a solid state drive or a rust drive, a spinning drive, you've got to have Spinrite. That's there, version 6.1. There is also his latest Endeavor, which is very useful, the DNS Benchmark Pro, which will tell you which DNS
[02:46:01] [SPEAKER_02] server is fastest for your particular location. And it probably isn't the one you're using. It's probably not your ISP's DNS server. Run the benchmark, you'll see. It also shows you all sorts of other interesting things. Lots of information. As we learned last week. Both of those at GRC.com. So is the show itself. Steve has unique versions of the show. He has a 16 kilobit audio version. A little
[02:46:31] [SPEAKER_02] scratchy, but very small. 64 kilobits sounds fine. Also smaller than the one we offer. So that's a great place to get that. The show notes, which are wonderful, read, you know, 20 or so pages, all the stuff you just heard, but with illustrations and links and all that stuff. And of course, transcriptions written by an actual human being, Elaine Ferris. Those come up a couple of days after the show. All of that at GRC.com. Now, if you want, you can get the show notes mailed to you. If you go to GRC.com slash email,
[02:47:01] [SPEAKER_02] Steve has a place where you can enter him suggestions, questions, pictures of the week, but you can also check some boxes below it for the weekly newsletter email or and no salesman will call, I promise, a news, regular email that you will never get, which announces new products. Every once in a while, you might get one. Every few decades, you might get something from Steve on that one. But I would suggest going to GRC.com slash email, filling out your email and checking
[02:47:30] [SPEAKER_02] both those boxes. You'll be glad you did. I have the show at our website, twit.tv slash sn. We also have it on YouTube. We also have a place you can just subscribe to it in your favorite podcast client. You can also watch us live. We do it every Tuesday right after Mac Break Weekly. That's about 1.30 Pacific, 4.30 Eastern, 20.30 UTC. Next week, Micah Sargent will be filling in for the next three weeks for me. Thank you, Micah. He's going to work really hard
[02:48:00] [SPEAKER_02] in the next few weeks as I'm on vacation. You can watch those live in the club, of course, in the Discord, but also YouTube, Twitch, x.com, Facebook, LinkedIn, and Kik. Streaming all those places. We will be back here. Well, he will be back here next Tuesday. I will be off. Let's see. Next Tuesday, I will be still in the plane flying to Taiwan and then on from Taiwan to Bangkok. Bangkok. So I have a
[02:48:29] [SPEAKER_02] long flight ahead of me and then on a cruise through the Straits of Malacca, Southeast Asia. It should be really cool. I'll have lots of pictures when I get back. Thank you, Steve. And I told Lisa I'm not going to spend too much time on the sweet track. No, I won't talk to them. See you. Have a great day. We'll see you next time on Security Now. Bye.